Third-party JavaScript can affect SEO when external scripts alter the Document Object Model (DOM) during rendering or compete with primary page assets for browser resources. Modern websites routinely load external code for tag management, consent management platforms (CMPs), client-side A/B testing, analytics, and interactive UI widgets. Because search engines that render JavaScript evaluate the final rendered HTML rather than just the initial server response, any script with page-level execution permissions can modify the signals crawlers process for indexing.
The technical risks of external scripts fall into two distinct categories: unintended DOM mutations and rendering resource contention. In the first case, third-party code may overwrite, strip, or inject indexable elements such as canonical tags, meta robots directives, internal links, or primary body copy-or fail to load when a crawler fetches the page, leaving expected content out of the rendered DOM. In the second case, heavy script execution blocks the browser's main thread, delays visual rendering, or injects unstyled layout elements that degrade Core Web Vitals.
Managing these risks requires inspecting the discrepancy between raw source HTML and the rendered DOM, understanding how stateless search engine crawlers interact with conditional scripts like cookie banners or geolocation redirects, and establishing engineering guardrails so external tools cannot silently alter indexable page elements.
How external scripts mutate the rendered DOM and indexable elements
When a browser or a JavaScript-capable search engine crawler fetches a URL, it first downloads the raw server response HTML and parses it to construct the initial Document Object Model (DOM). If that HTML includes external
<script>
tags, the rendering engine fetches and executes those scripts, granting them full access to standard DOM APIs-such as
document.createElement()
,
appendChild()
,
removeChild()
, and
innerHTML
. Any script running in the main document context (outside of a sandboxed
<iframe>
) has the same permissions to read, insert, modify, or delete nodes in the live DOM tree as first-party application code.
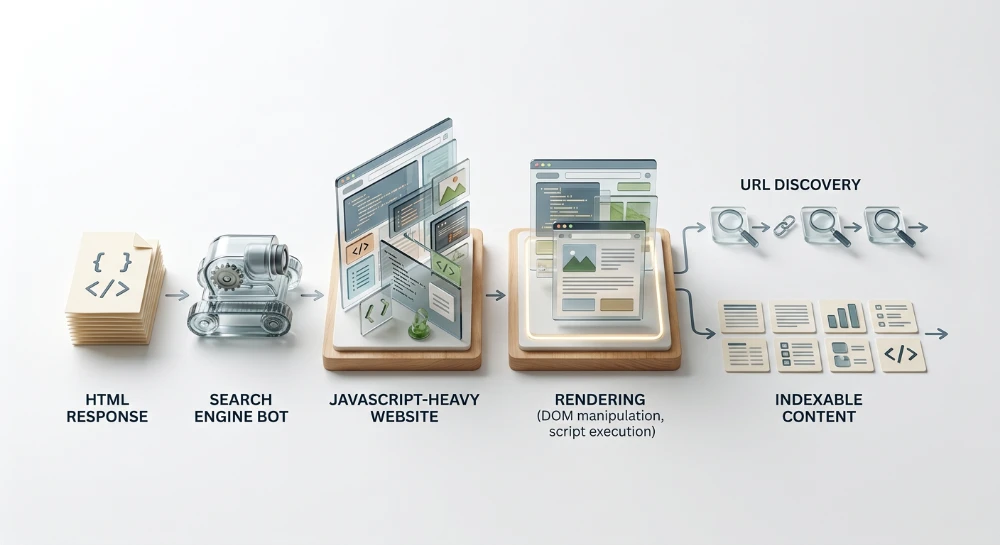
This execution model creates a potential discrepancy between the initial raw HTML and the final rendered HTML. Search engines that render JavaScript evaluate the rendered DOM after scripts execute. Consequently, client-side mutations made by external scripts directly alter the HTML structure, metadata, and content that the crawler extracts for indexing.
Common sources of Third-Party DOM manipulation
External scripts mutate indexable elements either by design-when marketing or product teams deploy workarounds outside the core codebase-or as an unintended side effect of UI manipulation:
-
Tag managers (such as Google Tag Manager): Custom HTML tags or custom JavaScript variables are sometimes used to deploy SEO patches-injecting missing
JSON-LDstructured data, rewriting<title>elements, inserting canonical tags, or modifying meta descriptions without waiting for backend engineering releases. -
Client-side A/B testing and personalization platforms: Testing scripts alter page layouts by hiding, removing, or replacing existing DOM nodes in the
<body>. These scripts may rewrite primary headings (<h1>), swap out body copy, or replace standard<a href="...">navigation links with JavaScript event listeners that crawlers do not follow. -
Client-side localization and translation widgets: External localization scripts often detect user attributes or URL parameters and overwrite the default language text in the DOM, sometimes also dynamically injecting or modifying
hreflanglink elements and canonical URLs in the<head>. - Automated SEO overlay tools: Third-party scripts marketed as automated SEO fixes intercept the page load to rewrite internal anchor text, heading hierarchies, and meta directives directly in the client browser.
Rendering capability vs. execution reliability
Evaluating the impact of third-party DOM manipulation requires separating what rendering crawlers can process from what happens when external dependencies fail:
-
Rendered DOM evaluation (stable technical fact): Search engines with rendering pipelines (such as Google's Web Rendering Service) compile the final DOM after executing JavaScript. If a third-party script overwrites a server-rendered
<title>or strips a block of internal links from the DOM during rendering, the crawler processes the modified state. - Third-party injection of critical signals (conditional risk): Relying on external scripts to inject indexable content, canonical tags, or structured data works only when the script loads and executes cleanly before the crawler captures the rendered DOM. Because third-party scripts depend on external network requests, DNS resolution, and third-party server availability, any network failure, script error, or execution delay leaves the crawler with only the initial server HTML.
Signal conflicts: Appending vs. replacing head directives
A frequent failure mode occurs when a third-party script attempts to update an indexing or canonicalization directive by appending a new DOM node to the
<head>
rather than locating and updating the existing element.
For example, the initial server HTML may contain a self-referencing canonical tag or a standard indexing directive:
<!-- Initial Server HTML -->
<head>
  <link rel="canonical" href="https://example.com/category/shoes" />
  <meta name="robots" content="index, follow" />
</head>
If a tag manager script or client-side plugin injects a new tag using
document.head.appendChild()
without removing or modifying the original node, the rendered DOM will contain multiple conflicting declarations:
<!-- Rendered DOM After Script Execution -->
<head>
  <link rel="canonical" href="https://example.com/category/shoes" />
  <meta name="robots" content="index, follow" />
  <!-- Injected by third-party script -->
  <link rel="canonical" href="https://example.com/shoes-promo" />
  <meta name="robots" content="noindex" />
</head>
Search engines handle multiple declarations according to specific conflict-resolution rules:
-
Multiple
meta name="robots"tags: Search engines evaluate the most restrictive directive present in the rendered DOM. If the server sendsindex, followand an external script appends anoindextag (or leaves a stagingnoindexrule active inside a tag manager container), the restrictivenoindexdirective takes precedence and prevents the page from being indexed. Conversely, if the server sendsnoindexand a script appends anindextag without removing the server-side tag, the page remains unindexed. -
Multiple
rel="canonical"tags: When a page contains two different canonical URLs in the rendered DOM, search engines may ignore both declarations due to the ambiguity, falling back to other canonicalization signals and potentially selecting a URL different from what either the server or the script intended. -
Head disruption via non-head elements: If a third-party script injects visible UI elements-such as an analytics pixel wrapped in a
<div>or an<iframe>-directly into the<head>above the server-rendered SEO tags, the HTML parser implicitly closes the<head>element at that point and moves all subsequent tags into the<body>. Search engines ignore<link rel="canonical">and<meta name="robots">tags that end up inside the<body>.
When a third-party script must modify a head directive as a temporary measure, the script must query the existing DOM node (for example, via
document.querySelector('link[rel="canonical"]')
) and overwrite its
href
or
content
attribute in place, and any injected visual containers must be appended strictly to
document.body
.
Run a deep technical crawl to identify 4xx errors, missing meta tags, and indexation blockers.
Crawler rendering constraints and external script failures
Search engine rendering engines-such as Google’s Chromium-based Web Rendering Service (WRS)-assemble a page by fetching the initial HTML document and subsequently requesting the external subresources required to construct the rendered DOM. Unlike a user’s browser, which maintains persistent local caches and waits indefinitely for slow network responses, automated rendering pipelines operate under strict resource budgets, stateless execution environments, and cross-domain crawling rules.
When a page relies on third-party JavaScript to populate or modify indexable elements, any interruption in fetching or executing that external file alters what the search engine indexes. If an external script fails to load or errors out during execution, the rendering engine does not halt indexing of the page; instead, it captures and indexes the fallback state of the DOM as it exists without that script's modifications.
External script failure modes during crawler rendering
External scripts fail during search engine rendering for four primary technical reasons:
-
robots.txtdirectives on the third-party host: Search engine crawlers check therobots.txtfile of every external origin before fetching subresources from that domain. If a third-party vendor, CDN, or tag management endpoint disallows user agents likeGooglebotin its ownrobots.txtfile, the crawler will not request the script. Because the file sits on an external domain, the host website cannot override this block via its own configuration. - Uncached resource latency and network timeouts: Crawlers generally execute in a stateless manner and do not rely on a pre-warmed browser cache from prior user sessions, though rendering pipelines may temporarily cache widely used subresources independently of standard HTTP cache headers. Each external origin requires DNS resolution, TCP handshakes, and TLS negotiation unless cached by the crawler's internal infrastructure. Rendering engines do not enforce a single, publicly documented fixed timeout threshold; instead, they stop waiting for network requests once internal rendering budgets or network idle heuristics are met. If a third-party server responds slowly or initiates a long chain of sequential script requests, the rendering engine may take its snapshot of the DOM before the script finishes loading.
-
Uncaught JavaScript exceptions in a stateless environment: Crawlers typically render pages without existing cookies, populated
localStorage, or browser history, and many skip executing standard event loops tied to physical user interactions (such as scrolling or mouse movement). If a third-party script assumes a specific storage object or global variable exists and attempts to read a property from anundefinedobject without error handling (try...catchor optional chaining), it throws an uncaughtTypeErrororReferenceError. An unhandled exception terminates the current execution context. If first-party rendering logic or subsequent DOM mutations are bundled into the same execution stack or rely on a callback from the failed script, those downstream operations never run. -
Cross-Origin Resource Sharing (CORS) and HTTP errors: When a third-party script dynamically fetches JSON payloads-such as localized product data, review snippets, or navigation menus-via
fetch()orXMLHttpRequest, a misconfiguredAccess-Control-Allow-Originheader on the external API or a transient5xxserver error will block the data payload, leaving the target DOM containers empty.
Evaluating fallback DOM states
Because third-party script execution cannot be guaranteed during every crawl, technical architecture must account for the fallback state of the document. The resulting indexing behavior depends on what resides in the raw server HTML prior to external script execution:
| Third-Party Script Role | Initial Server HTML State | Rendered DOM When Script Fails or Times Out | Indexing Impact |
|---|---|---|---|
| Injects primary body copy, product descriptions, or user reviews |
Empty container elements (e.g.,
<div id="reviews"></div>
)
|
Containers remain empty in the rendered snapshot | The page is indexed without the injected text, reducing topical coverage on the URL. |
| Builds primary navigation menus or pagination links client-side |
Placeholder elements or anchor tags without
href
attributes
|
No crawlable
<a href="...">
nodes exist in the DOM
|
Crawlers cannot discover or follow the internal link paths that depended on the script. |
| Overwrites default placeholder metadata with page-specific tags |
Generic site-wide
<title>
or fallback
rel="canonical"
pointing to a root URL
|
Fallback server tags remain unmodified in the
<head>
|
Search engines process the generic title or incorrect canonical URL, which can lead to URL de-duplication errors. |
Removes a temporary
noindex
tag after client-side validation
|
<meta name="robots" content="noindex">
present in server HTML
|
The
noindex
directive remains in the rendered
<head>
|
The page is excluded from the search index entirely. |
Decision rules for Server-Side vs. Third-Party execution
To prevent external network failures or third-party vendor changes from altering indexable signals, apply strict architectural boundaries between server-delivered HTML and client-side enhancements:
-
Deliver indexable elements in the initial HTTP response: Primary body content, heading hierarchies,
<title>tags, meta directives, canonical tags, and crawlable<a href>navigation links should be rendered on the server (via SSR or static generation) so they are present in the initial HTML payload. -
Do not use third-party scripts to reverse restrictive directives: Never ship a page with a server-side
noindextag or an off-page canonical URL with the expectation that an external script or tag manager will swap it to an indexable state on the client. - Migrate index-critical third-party widgets to server-side fetching: When third-party data-such as customer reviews, Q&A modules, or localized inventory descriptions-is meant to be indexed as part of the page, fetch that data via server-to-server API calls (with caching) and embed the markup directly into the server-rendered HTML, rather than relying on a client-side third-party script to build the DOM during crawler rendering.
- Isolate third-party execution contexts: Wrap first-party initialization code and third-party hooks in independent execution blocks or error boundaries so that an uncaught exception in an external marketing or analytics script cannot halt the execution of first-party hydration or UI scripts.
Consent management platforms, A/B testing, and geolocation scripts
Certain third-party scripts are designed to alter the DOM, restrict script execution, or redirect the browser based on user state, session attributes, or network location. Because search engine crawlers generally operate as stateless clients with predictable network origins, scripts that evaluate consent cookies, experimental buckets, or IP addresses often trigger edge cases that do not occur during normal human browsing.
Consent management platforms and stateless crawlers
Search engine crawlers normally do not store or return session cookies across requests, and they do not interact with UI prompts to grant tracking consent. Consequently, whenever a crawler loads a page protected by a Consent Management Platform (CMP), the CMP evaluates the request in its default, unconsented state.
How the CMP handles this unconsented state determines what the rendering engine indexes:
-
DOM placement and content dilution: Most CMPs inject a modal dialog or banner directly into the document. If the CMP inserts a lengthy list of vendor disclosures and legal text at the very top of the
<body>element before the primary page markup, that boilerplate becomes the first text encountered in the rendered DOM. This can occasionally cause search engines to pull cookie policy text into search result snippets when the page lacks clear descriptive metadata or prominent opening prose. Injecting the consent container at the end of the<body>and positioning it visually with CSS prevents the banner markup from preceding the main content in the DOM tree. -
Destructive vs. non-destructive blocking: Some strict CMP configurations hide or strip the underlying page content from the DOM until the user clicks an acceptance button. Because a crawler never clicks the button, destructive blocking leaves the crawler with an empty page or only the consent wall to index. A non-destructive overlay-where the full primary HTML remains intact in the DOM while the banner is layered on top via CSS
position: fixedandz-index-allows the crawler to parse the underlying document even while the prompt is visually active. - Auto-blocking of dependent scripts: CMPs frequently intercept or suppress other third-party scripts until consent is recorded. If a site routes indexable elements-such as JSON-LD structured data, product reviews, or dynamic internal links-through a tag manager or external widget that is categorized under a blocked consent group, those elements will never render for a stateless crawler. Scripts responsible for rendering indexable page content must either be exempted from consent blocking (if they do not process personal data) or moved to server-side rendering.
Client-Side A/B testing and personalization scripts
Client-side experimentation and personalization tools operate by intercepting the browser rendering process, evaluating targeting rules, and mutating the DOM to display a variant. To prevent the user from briefly seeing the original server-rendered page before the variant is applied-a visual flicker often called the Flash of Original Content (FOOC)-testing suites commonly deploy an anti-flicker snippet. This snippet hides the document body (typically applying
opacity: 0
or
visibility: hidden
) until the testing script finishes downloading and modifies the DOM, or until a failsafe timer expires.
When a crawler renders a page running client-side experiments, both DOM replacement and redirect tests can introduce indexing conflicts:
- Anti-flicker delays and incomplete rendering: If the external testing script experiences network latency or fails to load, the page remains hidden until the anti-flicker timeout finishes. While crawlers parse the DOM rather than relying solely on visual pixels, delaying script execution and layout completion increases the risk that the rendering engine captures the DOM before delayed client-side components have settled.
-
Split-URL redirects and canonical conflicts: In a redirect test, the testing script sends a portion of visitors from the original URL (Variant A) to a distinct test URL (Variant B) via
window.location.replace(). If Variant B is left indexable and contains a self-referencing canonical tag, search engines may index the test URL alongside or instead of the original page. Conversely, if a crawler is redirected to Variant B, any canonical tag on Variant B pointing back to Variant A creates a redirect-to-canonical loop if the testing script continually forces the crawler back to Variant B. - Substantial DOM replacement and cloaking risks: Replacing minor UI components (such as call-to-action phrasing or button placement) does not alter the core topical signals of a page. However, using a client-side script to swap out the entire primary heading, body copy, or link architecture-especially if targeting rules treat user-agents or specific IP ranges differently-can look similar to cloaking and cause search engines to index volatile, inconsistent content across crawls.
To prevent experimental variants from polluting the index, configure redirect tests so that alternate test URLs include a
<link rel="canonical">
pointing to the original baseline URL, or apply a
noindex
directive to temporary test URLs that should never appear in search results. Once an experiment concludes, hardcode the winning variant into the server-side codebase and remove the active DOM-mutation rule from the testing script rather than leaving the third-party tool to patch the page indefinitely.
Geolocation and IP-Based redirection scripts
Third-party geolocation scripts query the visitor's IP address against a geographic database and execute a client-side redirect (or swap page content) to match the detected country or language. While intended to streamline regional routing for users, automatic IP redirects restrict crawler discovery on multi-regional and multilingual websites.
Major search engines conduct the majority of their crawling from a limited set of geographic locations, most notably the United States for Googlebot. Even when a search engine supports locale-adaptive crawling from secondary regional data centers, its primary discovery crawls regularly originate from US-based IP addresses.
When a geolocation script automatically redirects all US IP addresses to the US storefront or English subdirectory (for example, forcing a visitor requesting
/de/
or
/fr/
back to
/us/
):
-
A US-based crawler attempting to fetch the German (
/de/) or French (/fr/) URL executes the geolocation script. -
The script detects the crawler's US IP address and triggers a client-side redirect to
/us/. -
The rendering engine follows the redirect, views only the
/us/content, and treats the regional URLs as redirecting pages rather than standalone indexable documents. -
Any
hreflangannotations pointing to the/de/and/fr/URLs break because the target URLs do not resolve to a self-canonical, indexable200 OKstate for the crawler.
To support regional discovery without sacrificing user localization, replace automatic client-side IP redirects with non-intrusive country selector banners that allow users to switch regions manually while leaving the requested URL intact. If business requirements mandate automatic routing for human visitors, configure the geolocation logic to bypass automatic redirects when standard search engine crawler user-agents are detected, or rely on HTTP
Accept-Language
headers to suggest-rather than force-a regional store.
| Script Category | Primary Crawler Interaction Risk | Diagnostic Verification Method | Recommended Mitigation |
|---|---|---|---|
| Consent Management Platform (CMP) | Banner text precedes main content in DOM; strict blocking strips page body or halts scripts that inject indexable data. | Inspect rendered HTML in a fresh, cookie-less browser session or URL Inspection tool; verify the DOM order of the consent container and check whether main content and structured data are present without clicking accept. |
Place CMP markup at the end of the
<body>
using CSS for visual positioning; use non-destructive overlays; render indexable content and structured data on the server.
|
| Client-Side A/B Testing | Alternate test URLs get indexed; redirect tests create canonical loops; heavy DOM replacement alters indexed copy between crawls. | Inspect the canonical tag on Variant B URLs; compare raw HTML against rendered HTML when the testing container is active versus blocked in DevTools. | Point Variant B canonical tags to the original URL; avoid client-side redirects for crawlers; migrate winning test variants into server-rendered templates promptly. |
| Geolocation Redirects | Crawlers originating from a single country (such as the US) are redirected away from international subdirectories, preventing indexing of regional pages. | Fetch non-US regional URLs using a US-based proxy or the search engine's inspection tool and check whether the final rendered URL changes or the DOM swaps to the US version. | Replace forced IP redirects with a dismissible regional selector banner, and ensure all regional URLs resolve directly without redirecting crawler requests. |
Bulk Google and Yandex index checker
Verify agency reports and track live SERP status in Google and Yandex to protect your SEO ROI.
Core web vitals and main thread contention from Third-Party code
Beyond altering indexable DOM elements, external scripts directly compete with first-party page assets for network bandwidth and CPU time. In the browser, third-party code shares the same single-threaded execution environment as the host document. When external scripts delay rendering, occupy the main thread, or alter page geometry after initial paint, they degrade Core Web Vitals-specifically Largest Contentful Paint (LCP), Interaction to Next Paint (INP), and Cumulative Layout Shift (CLS). While Core Web Vitals are part of Google's page experience evaluation, any downstream ranking effect is conditional on overall site quality and query competition; however, the mechanical degradation of browser performance is direct and measurable.
Largest contentful paint (LCP) and critical path contention
LCP measures the time from navigation initiation until the largest image or text block visible within the viewport is rendered. Third-party scripts delay LCP through two primary mechanisms: HTML parser blocking and network contention.
When a synchronous
<script>
tag without
async
or
defer
attributes is placed in the document
<head>
-a common requirement for legacy anti-flicker snippets, client-side A/B testing tools, and some Consent Management Platforms-the browser must halt HTML parsing, establish a connection to the external origin (DNS lookup, TCP handshake, and TLS negotiation), download the payload, and execute the code before discovering or rendering the LCP element in the
<body>
.
Even when third-party scripts load asynchronously, early execution can still delay LCP:
- Bandwidth contention: Large third-party bundles requested early in the page lifecycle compete with the primary hero image or web fonts for available network bandwidth, particularly on constrained mobile connections.
- Preload scanner evasion: If the LCP element itself is injected via a third-party script-such as a hero banner managed through an external personalization platform or tag manager-the browser's preload scanner cannot discover the image URL in the initial HTML markup. The image fetch is delayed until the external script finishes downloading and executing.
- Main-thread rendering delays: Even if the LCP image finishes downloading over the network, the browser cannot paint it to the screen if a third-party script is actively monopolizing the main thread during the rendering phase.
Interaction to next paint (INP) and Main-Thread long tasks
INP assesses page responsiveness by measuring the latency of user interactions (clicks, taps, and key presses) throughout the entire lifespan of a page visit. Specifically, it measures the duration across three phases: input delay (waiting for the main thread to become available), processing time (running event callbacks), and presentation delay (calculating layout and painting the next visual frame).
Because the browser's main thread handles HTML parsing, style calculation, layout, painting, and JavaScript execution sequentially, it cannot process a user interaction while executing a script. Any uninterrupted task that occupies the main thread for 50 milliseconds or longer is classified as a Long Task. Third-party scripts frequently generate Long Tasks during two distinct windows:
-
Boot-up and hydration:
Tag managers firing dozens of marketing pixels on the
DOMContentLoadedorloadevents trigger intensive script parsing, compilation, and execution. If a user attempts to open a navigation menu or tap a filter while these scripts are initializing, the interaction experiences high input delay until the third-party Long Tasks yield the main thread. -
Event listener overhead:
Analytics suites, session replay recorders, and heatmap scripts often attach global event listeners to
click,keydown, orpointerdownevents. When a user interacts with the page, these third-party callbacks run synchronously alongside first-party application logic, extending the processing phase before the browser can paint the visual update.
Scripts that serialize the entire DOM to capture user sessions or continually query the DOM via broad
MutationObserver
instances are particularly prone to inflating both input delay and processing time on pages with large DOM trees.
Cumulative layout shift (CLS) from unreserved dynamic injection
CLS measures visual instability by calculating the impact fraction and distance fraction of unexpected layout shifts that occur outside a 500-millisecond window following direct user input. Third-party scripts are a primary driver of CLS when they inject visible UI components into the document flow after the initial render without pre-allocated geometric space.
Common third-party sources of layout shifts include:
- Display advertising iframes: Ad networks frequently inject variable-height creatives into ad slots or resize existing containers dynamically after an auction completes. If the host page does not enforce a minimum height or aspect ratio on the parent wrapper, the injected ad pushes adjacent body content downward.
-
Promotional bars and notification banners:
Marketing widgets that prepend announcement bars to the top of the
<body>rather than overlaying them with fixed positioning shift the entire viewport layout downward once the external script executes. -
Consent banners and chat widgets:
While fixed-position overlays (
position: fixed) generally do not push existing document flow, they still trigger CLS if the script initially renders the banner in-flow before applying positioning styles, or if a chat launcher animates its position using layout-triggering CSS properties liketop,bottom, orheightinstead of compositor-only properties liketransform: translate(). - Late-swapping web fonts and personalization: External scripts that inject custom stylesheets or replace existing headlines with longer personalized text variants after the initial paint cause text reflows that shift surrounding elements.
| Core Web Vital | Primary Third-Party Failure Mode | Browser-Level Mechanism |
|---|---|---|
| Largest Contentful Paint (LCP) |
Synchronous scripts in
<head>
; client-side injection of hero images; early bandwidth competition.
|
Halts the HTML parser; hides image URLs from the preload scanner; delays resource fetching and frame painting. |
| Interaction to Next Paint (INP) | Heavy script initialization; session recording DOM serialization; synchronous global event listeners. | Creates Long Tasks (>50ms) that block the main thread, increasing input delay and callback processing duration. |
| Cumulative Layout Shift (CLS) | Unreserved ad containers; prepended top-of-page promotional banners; late DOM content replacement. | Alters element geometry and triggers document reflow after the initial visual frame has been painted. |
A critical distinction when evaluating these metrics is the difference between synthetic lab tests and field data (such as the Chrome User Experience Report). Lab tools generally load a page in an uncached, unconsented state without scrolling or clicking. Consequently, a lab test may miss INP regressions caused by third-party tracking scripts that only fire after a user accepts a consent banner and interacts with a product form, or CLS caused by lazy-loaded ad units that resize as the user scrolls down the page. Evaluating the full performance impact of external code requires examining both initial load contention and post-interaction execution across the page lifecycle.
Auditing and diagnosing Third-Party script impact
Isolating the technical footprint of external code requires separating server-delivered HTML from client-side execution and measuring how individual script origins affect the browser main thread. A structured diagnostic workflow verifies both DOM integrity and runtime performance before engineering changes are scoped.
Step 1: Compare raw source HTML against the rendered DOM
To detect unauthorized client-side mutations, compare the initial server response against the post-execution DOM state across both local browser tools and search engine inspection interfaces.
- Capture the raw HTML response using the browser's View Page Source function or by inspecting the initial document response payload in the Chrome DevTools Network panel.
- Capture the live, post-execution DOM from the Chrome DevTools Elements panel after all network activity settles.
- Run the target URL through the Google Search Console URL Inspection Tool and select the option to view the tested page's rendered HTML, alongside the More Info tab to inspect page resource loading errors and JavaScript console messages.
Run a diff or targeted search across both HTML snapshots focusing on indexation-sensitive elements:
<title>
,
<meta name="robots">
,
<link rel="canonical">
,
<script type="application/ld+json">
, primary heading tags, and internal navigation links. Pay particular attention to tag duplication rather than simple replacement. If a server response includes a valid canonical or robots meta tag and a tag manager injects a second instance later in the
<head>
or
<body>
, search engines may face conflicting directives. Furthermore, if an element appears in your local DevTools Elements panel but is absent from the Google Search Console rendered HTML, inspect the URL Inspection Tool's page resources report to determine whether the responsible third-party script failed to load or was blocked by its own origin's
robots.txt
.
Step 2: Isolate script origins with network request blocking
When a DOM mutation, visual flicker, or layout shift is identified, attribute the behavior to a specific vendor by selectively blocking external domains in Chrome DevTools.
Open the Network panel, load the page in an incognito window to simulate a stateless first visit, and locate requests to third-party origins such as
googletagmanager.com
, consent management platforms, or A/B testing suites. Right-click a suspect request or domain and select the option to block the request URL or domain, or add wildcard patterns (for example,
*://*.vendor-domain.com/*
) inside the Network Request Blocking drawer. Reload the page with the cache disabled and observe the baseline behavior:
- If an overwritten title tag, stripped canonical link, or altered body paragraph reverts to its server-rendered state when a tag manager or personalization domain is blocked, that origin is confirmed as the source of the mutation.
- To trace the exact script injecting or modifying a node without guessing across dozens of network requests, right-click the affected parent node in the Elements panel and enable DOM subtree modification breakpoints before reloading, or search the loaded files in the Sources panel for the mutated selector or string.
- Compare visual stability in the Performance panel with and without specific third-party domains blocked to confirm whether a consent banner, ad wrapper, or promotional bar is responsible for recorded layout shifts.
Step 3: Audit Main-Thread bottlenecks and SPOF risks
Once functional DOM mutations are cataloged, evaluate the CPU and network cost of each external vendor using synthetic diagnostics and failure simulations.
| Diagnostic Tool / Feature | Primary Evidence Provided | Interpretation and Diagnostic Signal |
|---|---|---|
| Lighthouse Third-Party Usage & Bootup Time Diagnostics | Aggregated transfer size and main-thread blocking time grouped by third-party entity and individual script URL. | Identifies scripts with high script evaluation and parsing durations that contribute to Long Tasks and degrade INP responsiveness. |
| WebPageTest Waterfall Chart | Chronological request sequence, DNS/TLS negotiation timing, and main-thread CPU utilization tracks below the waterfall. | Reveals whether third-party requests execute before the LCP resource finishes downloading or saturate the main thread during early page rendering. |
| WebPageTest SPOF (Single Point of Failure) Tab | Simulated blackhole routing of specified third-party domains to silent timeout server endpoints. | Exposes critical rendering dependencies; if a hung third-party domain results in a blank viewport or permanently hidden content, the script is blocking rendering or gating visibility. |
When interpreting WebPageTest waterfalls, look closely at the vertical lines indicating First Contentful Paint and Largest Contentful Paint relative to third-party script execution bands. A third-party script with a small file size can still degrade rendering performance if it initiates a chain of secondary requests or triggers synchronous style recalculations early in the page lifecycle. Similarly, testing suspect origins in the WebPageTest SPOF tab verifies whether an A/B testing anti-flicker snippet or synchronous head script fails gracefully when the vendor's CDN experiences latency, or whether it leaves the document visually blank until the browser connection times out.
SEO structure and reciprocal link analyzer
Detect orphan pages, deep click depths, and toxic reciprocal links built by careless agencies.
Implementation patterns and governance to mitigate Third-Party risk
Once an audit identifies which external scripts mutate the DOM or contend for main-thread and network resources, engineering teams can apply specific loading patterns, architectural adjustments, and governance rules to isolate third-party code from the critical rendering path and indexable document structure.
Script loading attributes and resource hints
Removing parser-blocking third-party scripts from the document
<head>
is the primary defense against delayed rendering and Single Point of Failure (SPOF) timeouts. Unless a vendor script strictly requires synchronous execution prior to first paint, external script tags should use either the
async
or
defer
attribute.
| Attribute / Hint | Browser Execution Behavior | Recommended Third-Party Use Case |
|---|---|---|
async
|
Downloads the script in parallel without blocking HTML parsing, then pauses the HTML parser to execute the script immediately upon download completion. Execution order is not guaranteed. | Independent scripts that do not rely on a fully constructed DOM or other scripts, and that need to capture early lifecycle events (such as analytics beacons or tag manager containers). |
defer
|
Downloads the script in parallel without blocking HTML parsing, but delays execution until the HTML document has been fully parsed (just before the
DOMContentLoaded
event). Preserves execution order.
|
Non-essential UI widgets, interactive features, feedback tools, and scripts that inspect or attach event listeners to existing DOM nodes without needing to run before initial paint. |
rel="preconnect"
|
Completes DNS lookup, TCP handshake, and TLS negotiation with the specified cross-origin domain in advance. |
Reserve strictly for 1 to 3 third-party origins that are guaranteed to be requested early in the page load (such as a CMP or critical CDN). Overusing
preconnect
consumes CPU and socket resources on both client and server.
|
rel="dns-prefetch"
|
Resolves only the domain name to an IP address in the background before the resource is requested. | Lightweight fallback or supplement for lower-priority third-party domains where full TCP/TLS pre-connection is unnecessary or too expensive. |
A common failure mode occurs when developers add
async
to a script that internally uses
document.write()
or assumes the entire body DOM is already present; in the former case, the browser ignores the
document.write()
call, and in the latter, the script may throw a null reference exception if the download finishes before the HTML parser reaches the target element. For scripts that manipulate body elements,
defer
provides safer execution timing while still keeping the initial network fetch off the blocking path.
Lazy loading and static facades for interactive widgets
Third-party embeds that are not immediately visible or used-such as below-the-fold comment sections, social feeds, embedded video players, and customer support chat widgets-should not initialize during the initial page load.
For widgets positioned below the initial viewport, wrap the script injection logic inside an
IntersectionObserver
callback. Instead of placing the vendor's
<script>
tag directly in the HTML, observe a static placeholder element near the widget's target container. When the user scrolls within a defined root margin (for example,
rootMargin: "200px"
), the observer dynamically appends the external script to the document and disconnects itself. Because search engine crawlers generally do not scroll pages in the same manner as human users-often rendering with an expanded virtual viewport instead-ensure that any content required for indexing is rendered server-side rather than gated behind scroll-triggered third-party observers.
For heavy interactive widgets that appear above the fold or globally across the viewport, such as live chat clients or embedded YouTube and Vimeo players, implement the facade pattern:
- Render a lightweight HTML and CSS element that visually matches the third-party widget (such as a static thumbnail image with a play icon, or a styled button resembling the chat launcher).
-
Attach passive event listeners (such as
pointerenter,focus, orclick) to the static facade. - On user interaction, dynamically fetch the full third-party SDK, replace the static placeholder with the live iframe or widget container, and replay the click or open action if supported by the vendor API.
Using a facade eliminates the third-party network payload and main-thread parsing cost entirely for sessions where the user never interacts with the widget, and prevents those scripts from executing during stateless crawler rendering passes.
Server-Side tagging and web worker offloading
When marketing, analytics, and conversion tracking scripts create severe main-thread contention despite deferred loading, two architectural approaches can move execution off the browser's main thread or out of the client browser altogether.
Server-Side tagging
Server-side tag management (such as Google Tag Manager Server-Side or similar proxy architectures) replaces multiple third-party vendor scripts in the browser with a single data stream sent to a first-party cloud endpoint (for example,
metrics.example.com
). The cloud container receives the event payload and distributes data to third-party analytics and advertising endpoints server-to-server.
While this architecture substantially reduces client-side JavaScript downloads and CPU execution time, it carries technical and operational trade-offs:
- Cloud infrastructure costs shift to the site owner, as every pageview and event triggers requests processed by the self-hosted or managed server container.
- Vendors that rely on client-side browser APIs-such as session recording tools, heatmaps, visual A/B testing scripts, or fraud-detection scripts that inspect device characteristics and DOM events-cannot be migrated to a server-side container and must remain in the client browser.
- First-party endpoints do not bypass privacy regulations; server-side forwarding must still respect the user's consent state transmitted from the client-side CMP.
Web worker offloading
Libraries such as Partytown relocate third-party script execution from the browser's main thread into a background Web Worker thread. Because Web Workers do not have direct access to the synchronous DOM API (
window
,
document
), Partytown uses JavaScript Proxies and synchronous communication techniques (Via Service Workers or
Atomics
) to intercept and forward DOM operations between the worker and the main thread.
Before deploying Web Worker offloading in production, evaluate its compatibility constraints:
- Scripts that primarily collect data and send network beacons (analytics, pixels) generally perform well in a worker context.
- Scripts that perform high-frequency synchronous DOM reads and writes-such as layout measurement loops, interactive UI widgets, or client-side A/B testing tools-suffer heavy serialization overhead across the worker bridge, which can degrade performance or break the script entirely.
-
Third-party scripts loaded inside a worker often require a Reverse Proxy with Cross-Origin Resource Sharing (CORS) headers if the vendor does not serve permissive
Access-Control-Allow-Originheaders on their script files and secondary endpoints.
Layout stability and tag manager governance
Engineering patterns alone will not protect rendering performance or indexable HTML if non-engineering teams can deploy arbitrary JavaScript through a Tag Management System (TMS) without technical guardrails. Long-term mitigation requires combining CSS layout rules with strict container governance.
Reserving geometric space for dynamic UI
Whenever a third-party script injects visible elements into the document flow-such as promotional top bars, inline advertising slots, or customer review carousels-the parent template must reserve static dimensions using CSS properties like
min-height
or
aspect-ratio
prior to script execution. If an ad slot or dynamic widget can return variable heights or fail to fill, size the container to the most common dimension and verify whether collapsing an empty slot triggers a layout shift for visible content below it. For Consent Management Platforms, configure the banner as a fixed-position overlay (
position: fixed
) rather than an element inserted at the top of the
<body>
that pushes the document layout downward upon hydration.
Restricting tag manager permissions and custom HTML
To prevent marketing tags or rogue scripts from overwriting server-rendered SEO signals, enforce technical restrictions within the tag manager environment:
-
Disable or restrict the "Custom HTML" and arbitrary JavaScript tag types for standard users, requiring engineering code review before any script capable of calling
document.querySelector,appendChild, orinnerHTMLis published. -
In Google Tag Manager, implement a tag deployment restriction policy using the
gtm.allowlistandgtm.blocklistkeys in thedataLayerdeclaration. Specifically, adding thecustomScriptsclass togtm.blocklistprevents arbitrary custom HTML and JavaScript tags from executing on the page even if someone publishes them in the GTM container interface, allowing only vetted template tags to fire. -
Prohibit the use of tag managers to inject or modify indexable elements, including
<title>tags,<meta name="robots">directives,rel="canonical"links, primary body copy, and internal navigation links. Keep all indexable metadata and content within the application's primary codebase and deployment pipeline.
Ongoing audit and decommissioning cadence
Third-party risk accumulates as campaigns end, vendors change, and legacy scripts remain active in tag containers or page templates. Establish a recurring governance schedule:
- Maintain a manifest of every active third-party script domain and tag manager rule, documenting its business owner, purpose, and expiration or review date.
- Audit container configurations quarterly to remove paused tags, unreferenced triggers, and scripts belonging to terminated vendor contracts.
- Include rendered DOM diff checks in automated staging or continuous integration tests-asserting that the post-hydration DOM still contains the exact canonical URL, robots directives, and core structural elements delivered by the server response before releasing template or container updates.