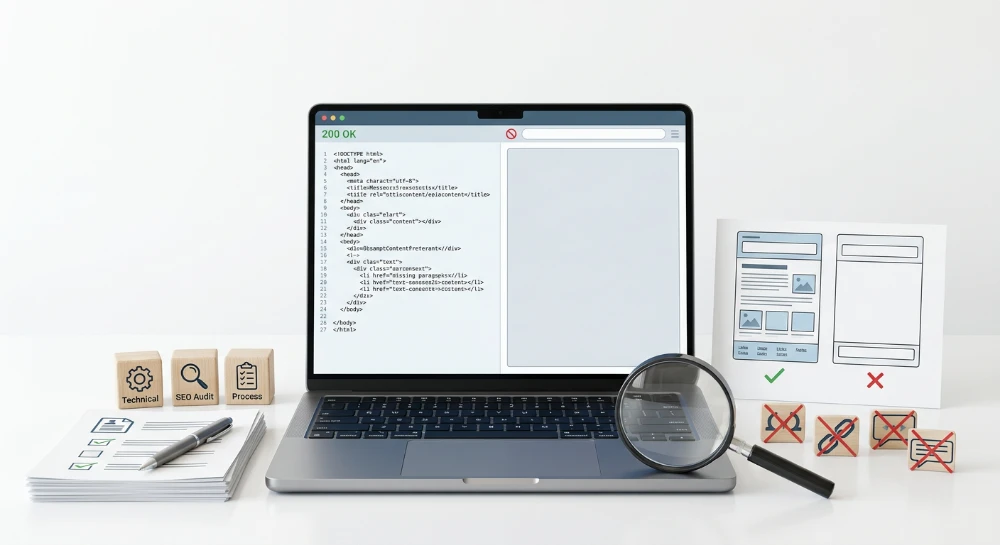
Auditing HTML rendering is necessary when a webpage returns a successful HTTP 200 status code but delivers an empty or incomplete document to search engines. This discrepancy typically occurs when a site relies heavily on client-side JavaScript to fetch content, assemble the layout, or inject critical metadata. While a human visitor using a modern browser sees a fully populated page, a crawler processing only the initial server response may encounter nothing more than a bare structural shell.
The challenge stems from the disparity between the initial HTML response and the fully rendered Document Object Model (DOM). If search engine bots cannot successfully execute the required rendering scripts-whether due to timeouts, blocked network resources, or code errors-they are left to process the incomplete version of the page. When primary text, canonical tags, or internal links depend entirely on client-side execution, rendering failures can cause search engines to drop content from the index or register the URL as a soft 404.
Detecting and resolving these missing elements requires isolating exactly where the rendering pipeline breaks down. This involves diagnosing individual page parity using developer tools, validating the engine's exact perspective through live inspection testing, and running comparative site crawls to scale the discovery of rendering failures across complex website architectures.
The mechanics of initial HTML vs. rendered DOM
Understanding rendering failures requires distinguishing between the raw source code returned by the server and the final structure generated by the browser. The initial HTML is the immediate text response delivered over the network when a URL is requested. The Document Object Model (DOM) is the dynamic, memory-based representation of the page constructed after the browser parses the HTML, executes associated JavaScript, and fetches additional data.
In traditional server-side rendering, the initial HTML contains the fully formatted text, links, and metadata. However, modern web development frequently relies on Client-Side Rendering (CSR) and Single Page Application (SPA) architectures. In a CSR model, the server offloads the assembly of the page to the user's device. The initial HTTP response typically consists of a skeletal HTML document containing little more than a script tag and an empty container element.
<!DOCTYPE html>
<html>
  <head>
    <title>Loading...</title>
    <script src="/app-bundle.js" defer></script>
  </head>
  <body>
    <div id="root"></div>
  </body>
</html>
When a standard browser loads this page, it downloads the JavaScript bundle, executes the framework logic, requests data from an API, and populates the empty container with the final content. This process, often involving a step called hydration where a framework attaches event listeners and injects data into the structural shell, happens quickly for users but presents a specific operational hurdle for search engine bots.
Search engines manage JavaScript-heavy websites using a two-phase crawling and indexing architecture. In the first phase, the crawler retrieves the initial HTML payload. Any content natively present in that raw source code is extracted and processed immediately. Because executing JavaScript requires significantly more computational resources than parsing static HTML, rendering is often deferred. The URL is placed in a rendering queue, leaving the engine with only the empty container element during the interim period.
The second phase begins when the rendering service becomes available to process the queued URL. A headless browser environment executes the JavaScript, fetches the necessary API endpoints, and captures the finalized DOM. If this process completes normally, the search engine updates its index with the rendered content. If the rendering phase is interrupted by execution timeouts, script errors, or network blocks, the finalized DOM is never constructed. When hydration fails or rendering is abandoned, the engine defaults to the content acquired during the first phase, recording an empty or incomplete document despite the initial successful server response.
Run a deep technical crawl to identify 4xx errors, missing meta tags, and indexation blockers.
Identifying missing content and structural elements
When a page relies on client-side execution to populate the DOM, specific structural and content elements are vulnerable to rendering failures. If the hydration process drops or is abandoned by the crawler, the resulting document lacks the signals necessary for proper indexing. Diagnosing these gaps requires evaluating the elements that most frequently fail to materialize when JavaScript execution is delayed or interrupted.
Primary body copy and soft 404s
The most immediate symptom of incomplete rendering is missing primary body copy. Text components such as product descriptions, article bodies, or user reviews are often fetched from an API post-load. If this content fails to render, search engines process a page containing only boilerplate navigation and footer elements. Pages lacking primary content are frequently classified as soft 404s, as the engine determines the URL offers no unique value despite returning a successful 200 HTTP status code.
Internal link navigation and routing
Navigation and internal linking structures are highly susceptible to implementation issues in JavaScript-heavy environments. Single Page Applications frequently utilize client-side routers to load new content without a full page refresh. Developers sometimes implement this routing using JavaScript onClick event listeners on generic elements like span or button tags, or on anchor tags missing an href attribute.
Search engine crawlers do not interact with the page or execute onClick events to discover URLs. For internal links to be crawlable, they must be formatted as standard HTML anchor elements containing a fully qualified or properly relative URL in the href attribute. When verifying internal links, the presence of the href attribute in the DOM is the strict requirement for path discovery.
Metadata and canonical directives
Critical metadata residing in the document head often depends on client-side execution to reflect the current page state. In many JavaScript frameworks, the initial HTML payload contains generic, site-wide placeholder tags. The specific title tag, meta description, and canonical URL are injected only after the JavaScript executes.
If this injection fails or happens too late, the crawler records the placeholder metadata. Missing or incorrect canonical tags can cause the engine to consolidate the wrong URLs, while generic titles degrade the relevance signals associated with the document. Verifying these elements requires confirming that the final injected tags overwrite the defaults rather than appending duplicates, which can confuse crawler parsing.
Dynamically injected structured data
Dynamically generated JSON-LD schema faces similar risks. Structured data is often assembled using variables fetched from client-side APIs or injected via tag management systems. If the script responsible for building the JSON-LD block times out or is blocked, the schema is absent from the rendered DOM. This absence prevents the search engine from extracting entities, product specifications, or breadcrumb structures, rendering the page ineligible for associated rich results.
Common causes of rendering failures
Rendering failures occur when the sequence of downloading, executing, and assembling client-side code breaks down before the page reaches its final state. These failures typically stem from code errors, network delays, restrictive server configurations, or architectural patterns that conflict with crawler behavior.
JavaScript execution errors
When a crawler or browser executes client-side code, it processes scripts sequentially. An unhandled exception or syntax error in a critical script can halt the execution thread. If the framework responsible for building the DOM encounters a fatal error before injecting the main content, the page remains in its initial, incomplete state. This failure mode is particularly common in single-page applications, where a single broken module or a variable reference error can prevent the entire routing and rendering sequence from completing.
Client-Side API timeouts
Client-side rendering frequently relies on asynchronous network requests to external APIs or databases to populate page content. Search engine rendering engines allocate a finite amount of time and resources to process each page. If an API request experiences high latency, or if the server fails to return a response before the crawler's render timeout is reached, the document is captured in its loading state. This results in the crawler processing a page that displays a loading spinner or an empty content container, missing the primary text, product details, or image grids.
Blocked rendering resources
To construct a page accurately, a crawler must be able to fetch the necessary JavaScript bundles, stylesheets, and API data. If these critical resources are disallowed by the robots.txt file, the rendering engine cannot download them. Without the application bundles required to parse the framework or the API endpoints needed to fetch the content, the crawler processes only the raw HTML response. This issue often surfaces when developers block generic directories to prevent crawlers from indexing raw JSON files or backend scripts, inadvertently breaking the rendering of the user-facing URLs that depend on those exact resources.
Content requiring user interaction
Search engine crawlers process pages passively. They do not scroll, click buttons, or trigger hover events to reveal content. Architectural patterns that require user input to modify the DOM routinely lead to rendering disparities.
- Infinite scroll implementations that rely entirely on JavaScript scroll event listeners, without providing standard pagination links in the DOM, limit the crawler to discovering only the initial batch of items.
- Script-reliant lazy loading implementations that require an element to enter the viewport before the script fetches the associated data or image source can prevent crawlers from processing below-the-fold content. Purely event-driven loading often leaves this secondary content absent from the rendered DOM.
- Tabbed interfaces and accordions that conditionally mount and unmount DOM nodes based on click events will hide unselected content from the crawler. Content should be present in the DOM and hidden via CSS rather than relying on JavaScript to inject it upon interaction.
SEO structure and reciprocal link analyzer
Detect orphan pages, deep click depths, and toxic reciprocal links built by careless agencies.
Manual verification using browser developer tools
Local browser developer tools provide an immediate method for diagnosing rendering dependencies on individual URLs before running large-scale automated crawls. The fundamental diagnostic technique involves comparing the initial server response against the fully executed page state.
Comparing the source HTML to the rendered DOM
To view the raw initial HTML response, open the page source using the browser's View Page Source command. This view displays the exact code delivered by the server before any client-side JavaScript executes. Search this raw document for critical page elements, such as primary body text, product specifications, canonical tags, or main navigation links.
Next, open the developer tools and navigate to the Elements panel. This panel displays the active Document Object Model after the browser has parsed the HTML, executed scripts, and injected dynamic nodes. Compare the presence of the critical elements between the two views.
A rendering dependency exists whenever content appears in the Elements panel but is absent from the raw page source. For example, if an article body is visible on the screen and in the Elements panel but missing from the raw source, search engines must successfully execute the page's JavaScript to process that text.
Diagnosing network and script failures
When expected content fails to appear in the Elements panel, the developer tools Network tab helps identify where the rendering process breaks down. This panel records every resource request made by the browser during page load.
Filter the Network panel by Fetch/XHR to isolate the client-side API calls responsible for retrieving dynamic content. Inspect the responses for these requests to verify that the server is returning the correct data payloads. A failed API call, indicated by a 4xx or 5xx HTTP status code, prevents the client-side scripts from populating the DOM, leaving the container elements empty.
Examine the execution behavior of external JavaScript files. Third-party scripts, such as tracking pixels, A/B testing overlays, or consent management platforms, can sometimes block the main thread. If a synchronous third-party script encounters a fatal error or hangs, it can halt the execution of subsequent scripts responsible for rendering the primary content. The developer tools Console panel will log these execution errors, helping correlate a failed script with missing DOM nodes.
As a final manual check, disable JavaScript entirely via the browser developer settings and reload the page. This simulates a strict non-rendering environment, instantly highlighting the exact baseline content and structural elements available to a crawler that fails to execute client-side scripts.
Validating the engine's view in Google search console
While browser developer tools provide a practical simulation of client-side rendering, they do not replicate Googlebot's specific rendering engine, network conditions, or timeout thresholds. To verify exactly what the crawler processes, the URL Inspection Tool in Google Search Console serves as the authoritative diagnostic environment.
Entering a URL into the inspection tool initially retrieves data from the current index. Because rendering issues often require real-time troubleshooting, select the Test Live URL option. This initiates a fresh fetch and render cycle, applying Googlebot's current technical constraints to the page.
Analyzing the rendered HTML
Once the live test completes, select View Tested Page to open the diagnostic side panel. The default HTML tab displays the serialized DOM snapshot captured after Googlebot executed the available JavaScript. This is the exact text and structure the search engine uses for parsing and indexing.
Search this HTML output for the critical elements identified during initial audits, such as primary body copy, injected canonical tags, or dynamically populated schema markup. If content that relies on JavaScript exists in the browser but is missing from this HTML tab, the crawler is failing to process the client-side scripts before its rendering cycle concludes.
Evaluating the rendered screenshot
The Screenshot tab provides a visual rendering of the page as seen by the crawler. This visual check quickly highlights missing structural blocks, failed hydration states, or infinite loading spinners that replace expected main content.
The screenshot represents a specific viewport based on the crawler type, typically a standard smartphone screen for mobile-first indexing. Content located far below the initial fold may not be visible in the image. If the visual layout appears truncated but the associated text is fully present in the HTML tab, the search engine has successfully processed that content.
Diagnosing failures in the more info tab
When the HTML or screenshot indicates an incomplete render, the More Info tab provides the technical logs necessary to isolate the root cause.
The Page Resources section lists external assets the crawler attempted to fetch. Review this list for resources marked as Blocked by robots.txt or Other error. The Other error status frequently indicates that an asset took too long to respond and exceeded the crawler's render budget. If a core JavaScript bundle or a primary JSON data endpoint fails to load due to these restrictions, the dependent DOM nodes will remain empty.
The JavaScript Console Messages section records execution errors encountered by the rendering engine. If a syntax error, an unsupported Web API call, or a hanging third-party script halts the rendering thread, the exact error log appears here. Correlating these console logs with the missing elements in the HTML tab helps pinpoint the specific script responsible for the failure.
Bulk Google and Yandex index checker
Verify agency reports and track live SERP status in Google and Yandex to protect your SEO ROI.
Scaling render audits across the website
While single-page inspections isolate specific script failures, large-scale detection requires automated site crawlers capable of executing JavaScript. Automating this process identifies systemic rendering dependencies and hydration failures across entire page templates or site sections without requiring manual verification for every URL.
The comparative crawl methodology
To audit rendering at scale, configure a desktop or cloud-based SEO crawler to perform a comparative analysis. This setup involves processing the target URLs twice: once parsing only the initial HTTP response source code, and a second time using an integrated headless browser to execute JavaScript and capture the fully rendered DOM.
When configuring the JavaScript rendering phase, set the headless browser to wait for network idle states or specific load events rather than relying strictly on a brief, fixed timer. Allowing adequate time for asynchronous data fetches ensures the crawler captures the finalized page state, reducing false positives where the tool simply records a timeout before the rendering thread completes.
Analyzing the render discrepancy delta
After the comparative crawl finishes, evaluating the delta between the raw HTML and the rendered DOM reveals exactly which structural elements depend on client-side execution. Sorting the crawl data by the largest discrepancies in specific extraction metrics highlights the most severe rendering dependencies.
Word count variance
Comparing the text node word count between the two crawl modes indicates how much readable content relies on JavaScript.
- Rendered count significantly higher: The core body copy requires client-side fetching to populate empty container nodes, making the content invisible to crawlers that do not render JavaScript.
- Rendered count significantly lower: A JavaScript execution error or hydration mismatch occurred, causing the application to overwrite pre-rendered HTML with an empty state, an infinite loading component, or a fallback error message.
Internal link parity
Crawlers extract internal links based on standard anchor tags. A mismatch in total extracted link counts between the HTML and rendered versions signals navigation instability. If the rendered DOM contains numerous links that the HTML source lacks, critical navigation menus or related-content modules depend on JavaScript execution. If the rendered DOM drops links that were present in the source, a rendering script is improperly suppressing DOM nodes during the hydration phase.
Heading tag consistency
Headings establish document structure and hierarchy. Crawlers will flag discrepancies if an H1 or primary H2 tag exists in the rendered DOM but is absent from the initial HTML. Systemic missing headings in the raw source mean search engines must successfully render every individual URL just to extract the primary topical signals.
Isolating systemic failures
Group the URLs with the highest variance by directory path or page template, such as product detail pages, category listings, or informational articles. If every product page exhibits a sudden drop in link counts during the JavaScript rendering phase, the root cause is typically a shared dependency, such as a failed UI component update or an API endpoint that blocks rendering when it times out. Isolating these patterns at the template level allows engineering teams to deploy a single architectural fix that resolves rendering parity across thousands of affected URLs.