JavaScript code splitting improves frontend performance by breaking monolithic bundles into smaller, on-demand chunks using dynamic
import()
statements, route-level separation, or component-level lazy loading. While this approach reduces initial download and parse times for users, it can affect search engine rendering by introducing multi-step network dependencies. Instead of executing a single script, the browser must discover, fetch, and execute a sequence of asynchronous files before the page reaches its final state.
When indexable text or internal links rely on client-side execution, search engine rendering services-such as Google's Web Rendering Service (WRS) running headless Chromium-must successfully fetch and execute these split chunks to construct the complete rendered DOM. Whether code splitting creates an SEO risk depends on your rendering architecture and what fails to load. If primary content is already present in the initial server-rendered HTML, a failed chunk may only break interactive features; however, in client-side rendered applications or lazily loaded content blocks, a single missing chunk can leave the rendered DOM incomplete or trigger a soft 404.
Maintaining crawl reliability requires addressing the failure modes that prevent crawlers from resolving split bundles, including deployment version skew, mismatched cache headers, and blocked asset paths. When build retention, HTTP caching, and component splitting boundaries are configured to account for stateless crawler requests, engineering teams can preserve fast user load times without sacrificing search visibility.
How code splitting affects crawler rendering and DOM construction
Module bundlers such as Webpack, Vite, and Rollup, alongside meta-frameworks like Next.js, Remix, and Nuxt, analyze an application's dependency graph at build time to divide JavaScript into smaller bundles. Instead of emitting a single file, the build process outputs distinct chunk categories:
- Vendor chunks containing third-party libraries and framework runtime code that rarely change across deployments.
- Route-level chunks generated automatically from file-system routing or explicit router configurations so that visiting a specific URL only loads the code required for that view.
-
Component-level chunks created when developers wrap specific UI elements or heavy modules in dynamic
import()calls,React.lazy(), or framework equivalents likenext/dynamic.
To support long-term browser and CDN caching, bundlers append a cryptographic hash of the file's contents to each filename (for example,
ProductDetails.8f9a2b.js
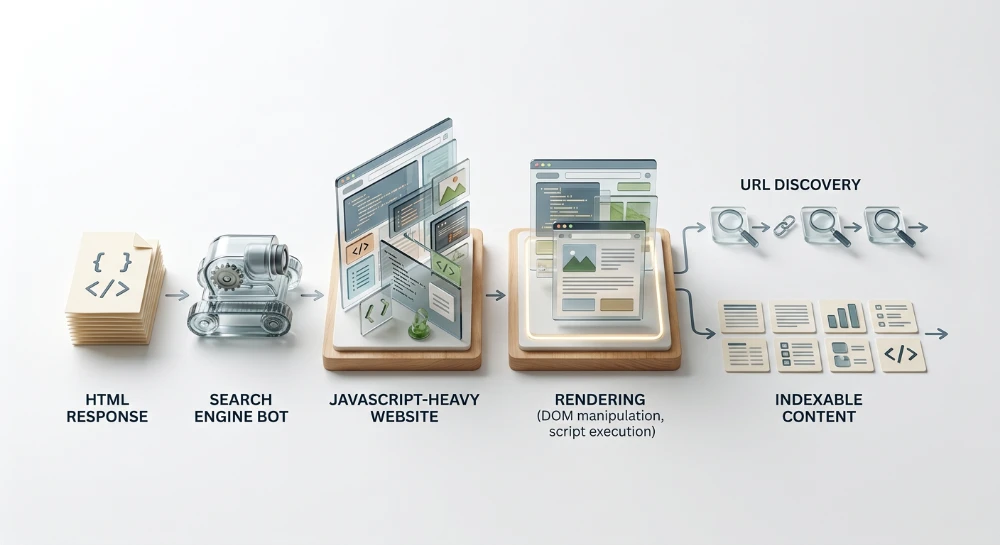
). A lightweight runtime manifest or entry script tracks which content-hashed filenames correspond to each route and component. When a search engine crawler processes a page, the rendering engine must load the initial HTML, execute the entry runtime, consult the manifest, and initiate secondary HTTP requests to fetch the required hashed chunks before it can execute the component logic and append the resulting nodes to the Document Object Model (DOM).
DOM construction across rendering architectures
The impact of a failed chunk request during this sequence depends on how much of the DOM is constructed on the server versus the client.
| Rendering Architecture | Initial HTML Payload | Role of Split Chunks | DOM State When a Chunk Fails |
|---|---|---|---|
| Client-Side Rendering (CSR) |
Minimal shell (such as an empty
<div id="root"></div>
) and script tags.
|
Fetches data, constructs the entire component tree, and injects primary markup into the DOM. | The root container or specific route view remains empty, or displays an error state instead of page content. |
| Server-Side Rendering (SSR) and Static Site Generation (SSG) | Complete HTML markup for the initial view, including primary text and links. | Attaches event listeners to existing DOM nodes (hydration) and loads client-only lazy components. | Server-rendered HTML remains in the DOM unless an unhandled hydration error triggers the framework to clear the root container; client-only lazy components fail to render. |
In a CSR application, DOM construction is entirely dependent on the network resolution of JavaScript bundles. The raw HTML response contains no indexable body copy or navigational links. If the headless browser fails to fetch the route chunk or a shared vendor dependency, script execution halts before the framework can mount the view, leaving the rendered DOM devoid of content.
In SSR and SSG architectures (such as Next.js, Nuxt, or Remix configured for server rendering), the server executes the route code first and sends pre-populated HTML to the crawler. When the headless browser loads the page, the core text and links are already present in the initial DOM. The browser still downloads the content-hashed JavaScript chunks to hydrate the page into an interactive application. If a chunk fails during this phase, two distinct behaviors can occur:
-
If the missing chunk is for a component wrapped in a client-only boundary (for example,
next/dynamicconfigured withssr: false), the server HTML remains intact, and only that specific component slot fails to populate. - If a core route or vendor chunk fails to load, hydration cannot complete. Depending on the framework's error handling, the browser may either leave the static server HTML untouched in an unhydrated state or, if a client-side exception is thrown during hydration without an isolating error boundary, tear down the server-rendered DOM tree and replace it with a client-side fallback UI.
Evaluating the SEO impact of unrendered chunks
A failed JavaScript chunk request does not automatically harm search visibility. Missing chunks only affect content discoverability when the unrendered code is responsible for injecting indexable text, metadata, or crawlable
<a href>
internal links that are absent from the initial HTML response.
To determine whether a code-splitting boundary introduces indexing risk, inspect the component's output against the raw server response:
- No discoverability impact: A dynamically imported chunk for an interactive pricing calculator, a modal dialog, a third-party chat widget, or a client-side chart fails to load. Because these elements do not contain primary page copy or crawlable navigation paths, the crawler still extracts the full indexable value of the page from the surrounding HTML.
- Direct discoverability impact: A dynamically imported chunk for a product description tab, a paginated article feed, a related-products link block, or an entire CSR route fails to load, and that markup was not pre-rendered on the server. Because the nodes never enter the rendered DOM, the search engine cannot index the text or discover the outgoing internal links during rendering.
Run a deep technical crawl to identify 4xx errors, missing meta tags, and indexation blockers.
Common causes of missing chunks and failed network requests
When a search engine rendering service processes a code-split page, it relies on the initial HTML response and the bundler's runtime manifest to discover and fetch secondary JavaScript files. If any of those network requests fail, the headless browser cannot execute the code inside the missing bundle. Whether a failed chunk request prevents the page from rendering depends on how the application handles the missing resource, though the network failures themselves typically stem from four technical mechanisms.
Version skew and deployment invalidation
Version skew occurs when the HTML document or runtime manifest evaluated by the client belongs to a different build generation than the static assets currently hosted on the origin server or CDN. Because bundlers append content hashes to chunk filenames (such as
ProductDetails.8f9a2b.js
) to support long-term caching, any modification to a component's source code generates a new filename on the next build.
This mismatch commonly happens through two pathways:
-
Stale HTML or manifest caching: A CDN or edge cache serves an older HTML document (or an unhashed runtime manifest) that still references
ProductDetails.8f9a2b.js, while a newer deployment has already replaced that file withProductDetails.3c4d1e.jsand purged the previous build directory. - Delayed rendering execution: Search engine crawlers often separate the initial HTTP fetch of the HTML document from the headless browser rendering pass, or execute dynamic imports while a rolling deployment is in progress. If a deployment purges older assets during the interval between when the crawler fetches the HTML and when the rendering service requests the referenced chunks, the chunk URLs in the initial document no longer exist on the server.
When the headless browser requests the purged filename, the server responds with an HTTP
404 Not Found
. In Webpack and similar bundler runtimes, this failed network request rejects the dynamic import promise and throws a client-side
ChunkLoadError
.
HTML fallback responses and MIME type mismatches
In Single-Page Application (SPA) hosting environments, web servers and CDNs are frequently configured with a catch-all rewrite rule that routes any unrecognized path to
/index.html
with an HTTP
200 OK
status-or serves a custom HTML error page with a
404
status-so the client-side router can handle navigation.
If this rewrite rule is applied globally without excluding static asset directories, a request for a missing or purged JavaScript chunk returns an HTML document with a
Content-Type: text/html
header instead of a JavaScript payload. This triggers two distinct failure modes in the rendering browser:
-
Strict MIME type blocking: When the server includes the
X-Content-Type-Options: nosniffresponse header, Chromium refuses to execute a script resource unless its declared MIME type matches an executable JavaScript type (such asapplication/javascriptortext/javascript). The browser aborts execution immediately and logs a MIME type mismatch error in the console. -
Syntax parsing exceptions: If
nosniffis not present and the browser attempts to parse the response body as JavaScript, it encounters the opening<!DOCTYPE html>or<html>tag and throws an immediateSyntaxError: Unexpected token '<'.
From a diagnostic standpoint, when a missing chunk request returns an HTTP
200 OK
with an HTML body instead of a
404 Not Found
, network monitoring tools that only filter by HTTP status codes will not flag the broken asset request.
Crawler access blocks in robots.txt and edge security
Even when all chunk files exist on the server and match the current build manifest, access control rules can prevent search engine crawlers from retrieving them.
-
Disallowed asset directories in
robots.txt: Search engine rendering services obeyrobots.txtdirectives before fetching subresources. If aDisallowrule blocks framework build paths-such as/_next/static/,/assets/,/static/js/, or wildcard rules matching/*.js$-the crawler cancels the chunk request before it reaches the network. Unlike a server 404, arobots.txtblock occurs locally within the crawler's fetching pipeline, meaning no HTTP request is recorded in origin server access logs. -
CDN and WAF bot filtering: Web Application Firewalls (WAFs), rate limiters, or CDN security rules may misclassify burst requests from headless rendering instances or unrecognized crawler IP ranges. When a single page load triggers dozens of concurrent chunk requests, edge security rules may return an HTTP
403 Forbidden,429 Too Many Requests, or an HTML challenge page for a subset of those files, causing partial execution failures even when the initial HTML document was served normally.
Granular Over-Splitting and request waterfalls
Code splitting configurations that set minimum chunk size thresholds too low, or wrap every small UI sub-component in a separate dynamic
import()
, can fragment a single route into dozens or hundreds of tiny JavaScript files. While HTTP/2 and HTTP/3 multiplex concurrent requests when assets are known upfront, component-level code splitting often creates sequential dependency chains.
In a nested splitting architecture, the browser must download, parse, and execute the parent route chunk before it discovers the dynamic import for a child container chunk, which in turn must execute before requesting a grandchild component chunk. Each step in this waterfall requires a full network round trip and main-thread evaluation pass. Under high origin latency or constrained rendering timeouts, deep request waterfalls increase the probability that late-discovered chunks fail to resolve or execute before the rendering service captures the final DOM snapshot.
| Failure Mechanism | Typical Network Response | Browser Console / Execution Signal |
|---|---|---|
| Version skew (purged build assets) |
HTTP
404 Not Found
on hashed
.js
URL
|
ChunkLoadError: Loading chunk X failed
or unhandled promise rejection
|
| SPA catch-all fallback on missing chunk |
HTTP
200 OK
or
404
with
Content-Type: text/html
|
MIME type mismatch block (with
nosniff
) or
Uncaught SyntaxError: Unexpected token '<'
|
robots.txt
disallow on asset path
|
Request aborted prior to network transmission |
Resource load failure reported as blocked by
robots.txt
; subsequent
ChunkLoadError
|
| WAF or CDN rate limiting |
HTTP
403 Forbidden
or
429 Too Many Requests
|
Failed script network request; partial hydration or missing component render |
| Nested request waterfall timeout | Pending, canceled, or timed-out network requests | No exception thrown if promises remain pending; incomplete DOM or unresolved loading state |
How failed chunks produce incomplete pages and soft 404s
When a dynamic
import()
or lazy-loaded chunk request fails inside a headless browser, the JavaScript runtime rejects the underlying Promise. What enters the final rendered DOM depends on how the application and its framework handle that rejected Promise or pending request before the rendering service takes its snapshot.
Unhandled exceptions and empty containers
If an application does not catch a rejected dynamic import Promise, the runtime throws an unhandled exception-such as an uncaught
ChunkLoadError
or a
TypeError: Failed to fetch dynamically imported module
. In client-side rendered applications, an uncaught error during route initialization halts component tree mounting. The root container (such as
<div id="root"></div>
or
<div id="app"></div>
) remains empty, or the page retains only the static layout shell while the main route view fails to populate.
In server-rendered applications undergoing client-side hydration, an unhandled chunk failure during the hydration pass can cause the framework to abort hydration for the affected subtree. Depending on the framework's runtime behavior, the browser may either preserve the initial server-rendered HTML without attaching event listeners or tear down the server-rendered DOM nodes when switching to client-side error recovery, wiping out the content that was initially present in the raw HTML response.
Error boundaries and Client-Side error states
Modern frontend frameworks provide error-catching boundaries (such as React Error Boundaries or Vue
onErrorCaptured
hooks) to prevent a single failed chunk from crashing the entire application. When a lazy-loaded component throws a chunk load error inside an Error Boundary, the framework catches the exception and renders a fallback UI in place of the broken component tree.
While this fallback provides a controlled experience for human users, it creates a status code mismatch for search engine crawlers. Because the initial HTML document was already delivered by the server with an HTTP
200 OK
status code, the client-side JavaScript cannot retroactively change the HTTP response header to a
404
or
500
status. Instead, the headless browser renders the Error Boundary fallback text-often a generic notice such as "Something went wrong" or "Failed to load module"-inside a page that technically reported a successful HTTP
200
response.
Unresolved suspense boundaries and persistent loading states
A third DOM state occurs when a chunk request does not immediately reject, or when the application suppresses the rejection without rendering an error view. When a component is wrapped in a suspense mechanism (such as
React.Suspense
or asynchronous component wrappers in Vue), the framework renders a fallback placeholder-typically a loading spinner, shimmer placeholder, or "Loading..". text-while waiting for the chunk Promise to resolve.
If the network request for the chunk hangs due to a deep waterfall or stalls until the rendering service reaches its execution timeout, the Promise remains pending. The suspense boundary never resolves to the target component, and the rendering engine captures the DOM while it still displays the skeleton loader.
| Client-Side Handling Pattern | Resulting Rendered DOM State | Content and Link Visibility |
|---|---|---|
| Uncaught Promise rejection / unhandled exception | Empty root container, blank route outlet, or aborted hydration subtree | Target component text and internal links are absent from the rendered DOM |
| Framework Error Boundary catches exception |
Generic error fallback UI rendered inside an HTTP
200 OK
page
|
Primary content is replaced by error text; error message text may be indexed or trigger a soft 404 |
| Pending Promise inside a Suspense boundary | Unresolved skeleton UI or loading spinner captured at snapshot time | Placeholder markup is captured instead of the lazy-loaded text and navigation elements |
How incomplete renders trigger soft 404s
Search engines evaluate both the HTTP status code and the rendered page content before indexing a URL. When a server returns an HTTP
200 OK
status code, but the rendered DOM after JavaScript execution contains an empty container, a generic Error Boundary message, or only a persistent loading spinner, search engines may classify the page as a soft 404.
Whether a failed chunk leads to a soft 404 or partial indexing depends on the scope of the missing bundle:
- Route-level chunk failure: If the failed chunk represents the entire primary view of a client-rendered page, the rendered DOM lacks unique body content. Search engines may treat the page as a soft 404 and exclude it from the index, or drop previously indexed content if the failure occurs during a recrawl.
- Component-level chunk failure: If the core article or product description is present in the initial HTML or loads via a successful primary bundle, the page will generally avoid a soft 404 classification. However, if a failed secondary chunk was responsible for rendering related product grids, pagination controls, or contextual internal links, the crawler simply fails to discover those specific text blocks and outgoing URLs.
Bulk Google and Yandex index checker
Verify agency reports and track live SERP status in Google and Yandex to protect your SEO ROI.
Diagnosing chunk load errors and incomplete renders
Identifying code splitting failures requires checking both the network layer for failed script requests and the resulting DOM for missing content. Because chunk errors often occur intermittently during deployments or affect only specific cached HTML states, a complete diagnostic workflow combines single-URL inspection, local network simulation, and automated crawl verification combined with error telemetry.
Step 1: Inspecting rendered HTML and resource failures in Google search console
The URL Inspection tool in Google Search Console provides direct visibility into how Googlebot fetches and renders a specific page. When a page exhibits indexing drops or unexpected soft 404 warnings, inspect both the last crawled state and the live state.
- Enter the target URL into the URL Inspection tool and view the stored crawl data before running a live test. Because version skew is often transient, the historical crawl view is necessary to confirm whether Googlebot encountered a missing chunk during its most recent scheduled visit, even if a live test currently succeeds.
- Click Test Live URL and open View Tested Page to examine the current rendering behavior.
- In the HTML tab, compare the raw server response against the rendered DOM. Verify whether text blocks, product grids, or navigation links that rely on asynchronous chunks appear in the rendered output or if the container remains empty or stuck on a loading state.
-
Open the More Info tab and review the Page resources list. Look for content-hashed JavaScript files (such as
chunk-a1b2c3.js) flagged with aBlocked by robots.txtstatus or an HTTP404 Not Found/403 Forbiddenerror. -
Check the JavaScript console messages panel within More Info. When a dynamic import fails during rendering, the console typically logs exceptions such as
Uncaught ChunkLoadError: Loading chunk [id] failedor a strict MIME type error indicating that an HTML fallback page was returned instead of a script.
Step 2: Simulating chunk failures locally with chrome DevTools
After identifying which chunks a page requests, reproduce the failure mode in a local or staging environment using Chrome DevTools to evaluate how the application handles missing bundles.
- Open Chrome DevTools, navigate to the Network tab, and filter requests by JS.
- Reload the page and distinguish the main entry bundle from secondary route or component chunks loaded asynchronously.
- Right-click a specific route-level or component-level chunk and select Block request URL (or Block request domain if chunks are served from a dedicated asset subdomain).
- Perform a hard reload and inspect the Elements panel (which represents the rendered DOM) alongside the Console panel.
Evaluating the resulting DOM reveals the exact failure state a crawler encounters when that specific chunk cannot be fetched:
-
If the page relies on Client-Side Rendering (CSR) and a route chunk is blocked, check whether an unhandled exception leaves the root mount node empty or if an Error Boundary renders a generic error message while the document retains an HTTP
200status code. - If the page uses Server-Side Rendering (SSR) or Static Site Generation (SSG), check whether blocking the chunk causes the client framework to discard the initial server-rendered HTML during hydration error recovery, or if the core content survives in the DOM without interactivity.
Step 3: Auditing at scale with crawlers and error telemetry
Single-URL testing cannot reliably catch intermittent deployment skew across thousands of URLs. Detecting partial renders across an entire site requires combining JavaScript-enabled SEO crawlers with client-side error monitoring.
Auditing rendered output with SEO crawlers and headless scripts
Configure a JavaScript-capable SEO crawler-such as Screaming Frog or Sitebulb-with Chromium rendering enabled, or run an automated headless browser script using Playwright or Puppeteer. To isolate incomplete renders caused by failed chunks, evaluate the following signals across page templates:
- Raw vs. rendered content discrepancies: Compare word counts and internal link counts between the raw HTML response and the rendered DOM. For CSR pages, a rendered word count near zero indicates a primary bundle or route chunk failure. For hybrid SSR pages that lazy-load secondary modules (such as related item carousels or pagination), a drop in rendered outgoing links compared to standard pages sharing the same template indicates a component-level chunk failure.
- Unresolved fallback selectors: Configure custom extraction rules using XPath or CSS selectors to scan the rendered DOM for persistent skeleton loaders, spinner containers, or Error Boundary fallback elements that should have been replaced before the rendering window closed.
-
Sub-resource status codes:
Enable the crawl configuration option to store and report all page resources, then filter for JavaScript files returning
4xxor5xxstatus codes.
Cross-Referencing Client-Side error logs
Because synthetic crawls only capture a single point in time, review client-side error tracking platforms (such as Sentry or Rollbar) to measure how often chunk failures occur during live deployments.
Filter error logs for
ChunkLoadError
,
Failed to fetch dynamically imported module
, or
Unable to preload CSS
exceptions. Segment these events by user agent (such as
Googlebot
,
AdsBot-Google
, or
bingbot
) and correlate the timestamps against your CI/CD deployment history. A spike in chunk exceptions among bot user agents immediately following a production release indicates that crawlers are attempting to execute stale HTML documents or build manifests that reference purged asset hashes.
Preventing version skew through caching and build retention
Preventing missing chunk
404
errors during and after deployments requires decoupling the caching lifecycle of entry-point HTML documents from the lifecycle of hashed static assets, alongside retaining historical build artifacts to serve in-flight rendering sessions.
Separating Cache-Control policies by asset type
Version skew frequently occurs when a CDN or intermediate cache serves an outdated HTML document or unhashed runtime manifest after a new deployment has already replaced the underlying JavaScript files. To ensure crawlers and browsers always receive synchronized asset references, apply distinct
Cache-Control
headers based on whether a file name contains a content hash.
| Resource Type | Example Path | Recommended Cache-Control Header | Technical Purpose |
|---|---|---|---|
| HTML Documents |
/products/item-a
,
/index.html
|
no-cache, no-store, must-revalidate
or
public, max-age=0, s-maxage=60, must-revalidate
|
Forces the client or CDN edge to revalidate the entry document so it references the latest deployment's chunk hashes. |
| Unhashed Manifests and Service Workers |
/asset-manifest.json
,
/sw.js
|
no-cache, must-revalidate
|
Prevents runtime chunk-mapping files from pointing to purged bundle filenames. |
| Content-Hashed Chunks (JS/CSS) |
/_next/static/chunks/482-9b8d7a.js
,
/assets/vendor.3f2a1c.js
|
public, max-age=31536000, immutable
|
Allows long-term caching because any code modification generates a new filename during the build process. |
If your architecture uses edge caching for HTML documents via
s-maxage
or
stale-while-revalidate
, trigger an automated CDN cache purge for HTML routes and unhashed manifests only after the new static chunks have been uploaded to origin or object storage. Purging the HTML cache before the new hashed chunks are available on all edge nodes creates a temporary window where early requests reference files that have not yet propagated.
Retaining historical build artifacts across deployments
Strict cache headers alone cannot prevent version skew for crawlers that are already mid-render when a release occurs, or for rendering queues that process a previously fetched HTML payload minutes or hours after the initial HTTP request. If a deployment pipeline overwrites the static output directory and deletes the previous build's files immediately upon release, any in-flight rendering session requesting an older chunk hash will receive a
404 Not Found
.
Configure deployment pipelines to use additive asset publishing rather than destructive directory replacement:
-
Upload static assets to shared object storage:
Instead of serving hashed chunks solely from the ephemeral local filesystem of a container or virtual machine, upload build outputs (such as
/dist/assets/or/_next/static/) to persistent object storage (such as Amazon S3 or Google Cloud Storage) fronting your CDN. -
Deploy using non-destructive sync commands:
When copying new build artifacts to the storage bucket, omit deletion flags (such as omitting
--deleteinaws s3 sync). This leaves previous content-hashed chunks intact alongside the newly generated files. -
Implement a retention grace period:
Use storage lifecycle policies or scheduled cleanup scripts to retain historical chunks for a defined window (for example, 7 to 30 days, or keeping the last
Nproduction builds) before pruning them.
In containerized or multi-instance environments that serve static files directly from application servers during a rolling deployment, ensure the load balancer does not route requests for new chunk hashes to older instances that do not yet have the files, nor route requests for older chunk hashes to new instances that have wiped the previous build directory. Centralizing static assets on an external CDN backed by object storage eliminates instance-level file mismatches during rollout phases.
Implementing platform skew protection and deployment binding
When using serverless or edge-hosted meta-frameworks where routes, server actions, and static manifests are tightly coupled to a specific build, retaining static JS files may not resolve mismatches if the client runtime also interacts with version-specific server endpoints.
Where supported by the hosting platform or framework (such as Vercel's Skew Protection or custom deployment-binding middleware), configure the application to bind each page session to a specific deployment identifier:
-
Deployment ID injection:
During build time, the platform or bundler embeds a unique
deploymentIdinto the HTML document and client-side runtime requests (via query parameters, custom HTTP headers, or cookies). - Version-pinned routing: When the headless browser requests subsequent lazy-loaded chunks or data payloads, the edge network inspects the deployment identifier and routes those sub-requests to the exact build artifacts and serverless function versions that generated the initial HTML response.
To verify that build retention and caching rules are functioning properly, inspect the response headers of both an HTML route and a dynamically imported JS chunk in a staging or production environment, then run a deployment while simulating throttled network requests for the previous build's chunk URLs to confirm they continue returning HTTP
200
with the
application/javascript
MIME type.
SEO structure and reciprocal link analyzer
Detect orphan pages, deep click depths, and toxic reciprocal links built by careless agencies.
Rendering fallbacks and component splitting boundaries
Even with strict cache headers and deployment retention policies, network timeouts or edge caching anomalies can still cause individual chunk requests to fail. Protecting content discoverability requires structuring frontend code so that failed asynchronous imports do not prevent primary page content or internal links from appearing in the DOM.
Defining component splitting boundaries
The primary architectural decision rule for crawl resilience is to decouple indexable content from client-only asynchronous execution. Deliver primary body text, metadata, structured data, and navigational links in the initial HTML payload via Server-Side Rendering (SSR) or Static Site Generation (SSG). Reserve client-only lazy loading-such as
React.lazy()
wrapped in a
Suspense
boundary, or framework equivalents like Next.js
next/dynamic
configured with
ssr: false
- strictly for non-indexable UI elements.
| Component Type | Recommended Rendering and Splitting Strategy | Result If Chunk Request Fails |
|---|---|---|
| Primary article text, product descriptions, headings, and canonical/meta tags | Include in the initial SSR or SSG HTML response. Even if the component code is split for client hydration, keep server rendering enabled. | Hydration may fail or abort, leaving interactive event listeners unattached, but the static text and metadata remain intact in the initial HTML. |
| Primary navigation, pagination, breadcrumbs, and contextual internal links |
Render standard HTML anchor tags with
href
attributes on the server. Avoid hiding links inside client-only drawer or menu chunks that only mount after interaction.
|
Client-side routing transitions may break, but crawlers can still extract the
href
URLs directly from the server-rendered DOM.
|
| Interactive widgets, calculators, charts, modals, and authenticated account panels |
Split into separate chunks using client-only dynamic imports (for example,
ssr: false
) wrapped in isolated
Suspense
and Error Boundaries.
|
The widget fails to render and falls back to a localized placeholder, while the surrounding indexable page content remains unaffected. |
When applying error boundaries in component-driven frameworks, scope them around individual lazy-loaded features rather than wrapping only the root application container. If a non-essential widget chunk fails to load, a localized error boundary prevents the uncaught exception from bubbling up and unmounting the entire server-rendered page tree during hydration.
Recovering from chunk errors with retry and reload wrappers
When a user or crawler loads an application and triggers a dynamic import that fails due to version skew or a transient network error, wrapping the dynamic
import()
call in a retry helper (often implemented as a
lazyWithRetry
utility) can recover the render before an error boundary replaces the view.
This pattern intercepts promise rejections from
import()
calls and applies a two-stage recovery mechanism:
-
Immediate network retry:
If a chunk request fails due to a momentary network drop, retrying the same
import()promise after a brief delay can resolve the module without reloading the page. -
Controlled hard reload on version skew:
If the error matches a missing chunk signature (such as
ChunkLoadErrororFailed to fetch dynamically imported module), retrying the same content-hashed URL will continue to return a404if the build was purged. Instead, the wrapper catches the error and invokeswindow.location.reload()to fetch the latest HTML document and updated runtime manifest from the origin.
When implementing a hard reload fallback, always guard against infinite reload loops. If a chunk is permanently missing due to a broken build artifact or a misconfigured CDN path rather than version skew, an unguarded
window.location.reload()
will execute repeatedly. Store a boolean flag or timestamp keyed to the current path in
sessionStorage
before triggering the reload:
function lazyWithReload(importFn, componentName) {
  return React.lazy(async () => {
    const storageKey = `retry-lazy-${componentName}`;
    const hasRetried = window.sessionStorage.getItem(storageKey);

    try {
      const component = await importFn();
      window.sessionStorage.removeItem(storageKey);
      return component;
    } catch (error) {
      if (!hasRetried) {
        window.sessionStorage.setItem(storageKey, 'true');
        window.location.reload();
        return { default: () => null };
      }
      throw error;
    }
  });
}
If the chunk fails a second time after the page reloads, the wrapper sees the
sessionStorage
flag, skips the reload, and throws the error to the nearest localized error boundary so the rest of the document can finish rendering.
Flattening network waterfalls with resource hints
Even when all chunks exist and return HTTP
200
, deeply nested dynamic imports create sequential network waterfalls. If the browser must download and execute the main entry bundle before discovering that a route chunk is needed, and then execute that route chunk before discovering a child component chunk, the cumulative latency increases the risk that rendering completes slowly or times out under constrained network conditions.
To eliminate discovery delays for critical split bundles, emit resource hints directly in the initial HTML
<head>
:
-
Module preloading (
<link rel="modulepreload">): For applications outputting native ES modules (such as Vite builds),modulepreloadinstructs the browser to fetch, parse, and compile the JavaScript module into the module map immediately in parallel with the entry script. -
Script preloading (
<link rel="preload" as="script">): For standard bundled scripts,preloadinitiates the network fetch early in the document lifecycle so the chunk is already in the browser cache when the runtime executes the dynamic import call.
Most modern SSR frameworks and bundler plugins automatically generate preload tags for the chunks associated with the current route via build manifests. However, if custom code splitting is introduced inside client components that only evaluate after initial state resolution, inspect the network waterfall in Chrome DevTools to verify whether critical chunks are delayed until late in the execution timeline, and limit preloading strictly to chunks required for the initial route view to avoid competing for bandwidth with primary document resources.