Dynamic imports and code splitting are standard frontend techniques for reducing initial JavaScript bundle sizes and minimizing main-thread work. However, deferring module loading with the
import()
syntax can directly affect indexable content if primary copy, navigation, or internal links are delayed or excluded from the rendered Document Object Model (DOM). While splitting code improves user-facing performance metrics, it introduces an architectural trade-off between page speed and search engine accessibility.
Using dynamic imports does not automatically prevent content from being indexed. Modern search engines like Google process JavaScript through a Web Rendering Service (WRS) capable of fetching and executing split code chunks. Whether dynamically imported content is actually discovered and indexed depends on three implementation conditions: whether the component's markup is included in the initial Server-Side Rendered (SSR) HTML response, what specific browser event triggers the client-side network request for the JavaScript chunk, and whether the visiting crawler executes JavaScript at all.
When a dynamic import relies on user interactions like clicks or specific scroll thresholds to fetch a module, automated crawlers typically will not trigger the request, leaving that content absent from the rendered page. Furthermore, even if a module loads immediately upon page initialization, relying solely on client-side execution shifts content discovery to the rendering phase and leaves the markup invisible to non-rendering bots and many AI crawlers. Maintaining search visibility alongside frontend performance requires separating SEO-critical markup that belongs in the initial HTML payload from purely interactive UI components that can safely load on demand.
How search engines process dynamically imported modules
When module bundlers such as Webpack, Vite, or Rollup encounter a dynamic
import()
statement during the build process, they extract the referenced module and its dependencies into a separate JavaScript file, commonly called a chunk. Instead of bundling the entire application into a single payload, the bundler generates a lightweight runtime manifest that maps module identifiers to their corresponding output filenames. At runtime, reaching the dynamic import triggers an asynchronous HTTP request to fetch that specific chunk, parse the JavaScript, and inject the resulting elements into the browser's Document Object Model (DOM).
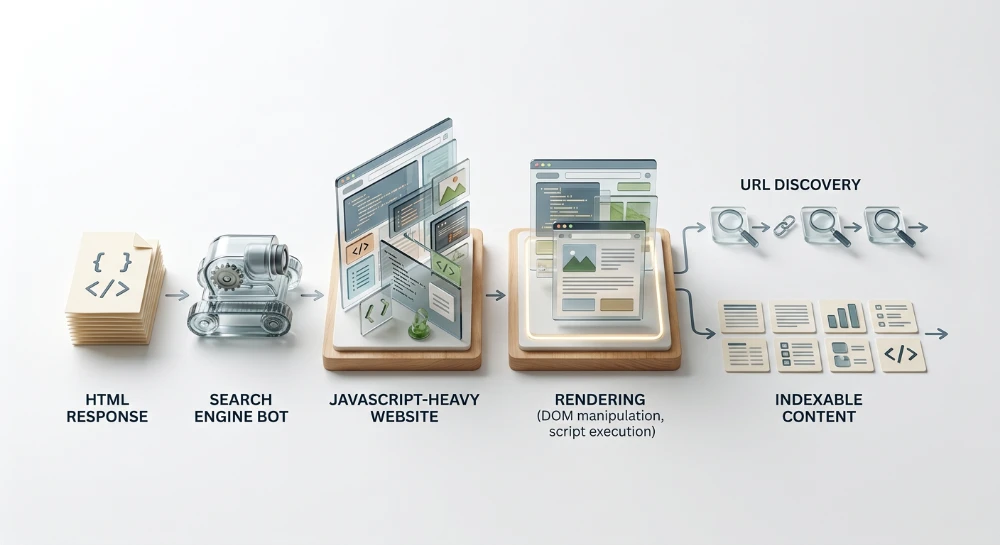
For search engines, this architecture creates a structural gap between the initial raw HTML response and the final rendered DOM. If a component is loaded strictly via client-side dynamic imports without server-side rendering, the initial HTTP response from the server contains only the application shell-such as an empty
<div id="app"></div>
container or a loading placeholder-alongside the entry-point script tags. The actual text, headings, and anchor tags inside the split module do not exist in the raw source code; they only appear in the rendered DOM after the browser environment downloads and executes the secondary JavaScript chunk.
Rendering engines vs. Non-Rendering crawlers
Whether a crawler can access content inside a dynamically imported chunk depends on its rendering capabilities and how the application triggers the network request:
-
Search engines with full rendering pipelines: Google processes pages in two phases-crawling the initial HTML response and subsequently passing the page to its Web Rendering Service (WRS). Because WRS runs a headless Chromium environment, it executes the entry-point JavaScript, resolves the bundler's runtime manifest, and makes the necessary network requests to fetch dynamically imported chunks. Consequently, standard code-splitting patterns-such as route-level splitting or component chunks that load automatically upon page initialization-are generally resolved and indexed once Google renders the page. Bing's rendering pipeline similarly uses a headless Chromium-based environment to execute JavaScript, though its rendering queue cadence and timeout tolerances can differ from Google's.
-
Non-rendering search, social, and AI crawlers: Many automated systems do not run a headless browser. Social media preview bots, certain site-verification and monitoring tools, and major AI crawlers-including OpenAI's GPTBot and Anthropic's ClaudeBot-typically parse only the raw HTML returned in the initial HTTP response. Because these crawlers do not execute client-side JavaScript, they never trigger the runtime manifest to request secondary chunks. Any content, metadata, or links isolated inside a client-only dynamic import remain completely invisible to these bots.
The cost of deferring discovery to the rendering phase
Even when targeting search engines that execute JavaScript, relying entirely on client-side chunk fetching for primary content shifts content discovery from the initial crawl to the rendering phase. Instead of extracting text and links immediately from the first HTTP response, the search engine must allocate rendering resources, execute the main bundle, wait for the secondary chunk requests to resolve over the network, and snapshot the final DOM.
While Google's WRS often processes pages quickly, deferring discovery introduces additional points of failure and potential latency. Each dynamically imported chunk requires a separate network round-trip during the rendering session. If a page chains multiple dynamic imports sequentially-where one chunk imports another-the resulting network waterfall increases the time required to assemble the DOM. If chunk requests fail due to transient network timeouts, server overload, or uncaught JavaScript exceptions in the parent bundle, WRS captures the incomplete DOM state, leaving the deferred content out of the indexable snapshot.
Run a deep technical crawl to identify 4xx errors, missing meta tags, and indexation blockers.
Decision framework: What to lazy load vs. render on the server
Modern JavaScript frameworks allow developers to configure code splitting at the component level, choosing whether a dynamically imported module is pre-rendered on the server or fetched exclusively on the client. Deciding between Server-Side Rendering (SSR) or Static Site Generation (SSG) and pure Client-Side Rendering (CSR) requires evaluating two factors: whether the component contains signals required for search indexing, and where the component sits in the initial viewport.
Components that belong in the initial HTML payload
Any page element that establishes topical relevance, defines indexability rules, or provides crawl paths should be rendered into the initial HTML response. Even if a framework splits the underlying JavaScript into separate chunks for client-side hydration, the server should still output the complete HTML markup on the first request.
- Document metadata and directives: Title tags, meta descriptions, canonical tags, and meta robots directives must reside in the initial raw HTML. Search engines evaluate these signals before deciding whether to queue a page for rendering, and non-rendering crawlers rely on them exclusively.
-
Primary body copy and headings: The main heading (
<h1>), subheadings, and core textual content that satisfy the user query should be present immediately. Pre-rendering this text ensures that search engines and AI bots can extract the primary content without waiting for JavaScript execution. -
Primary navigation and internal links: Header menus, breadcrumbs, pagination controls, and contextual in-copy links (
<a href="...">) drive URL discovery. Including them in the initial payload allows crawlers to extract and queue outbound URLs during the initial HTML parse rather than waiting for the rendering pipeline. - Structured data: While Google can process JSON-LD injected dynamically via JavaScript, rendering structured data directly in the server HTML eliminates the risk of script timeouts preventing rich result eligibility and ensures compatibility with other parsers that do not execute JavaScript.
Components suited for Client-Only dynamic imports
Client-only dynamic imports-where the server outputs an empty placeholder or loading state and the browser fetches the JavaScript chunk after initial load-should be reserved for heavy, interactive UI features that do not contribute to the page's indexable text or link graph. Deferring these modules reduces the initial JavaScript bundle size and limits main-thread blocking during page startup, which can help improve responsiveness metrics such as Interaction to Next Paint (INP).
Strong candidates for client-only lazy loading include:
- Authenticated and user-specific UI: Account settings modals, shopping cart drawers, and profile dashboards are closed to unauthenticated search crawlers and contain no public indexable value.
- Interactive tools and visualizers: Complex charting libraries, WebGL canvases, mortgage calculators, and multi-step product configurators often require substantial third-party JavaScript libraries. Provided the page already includes static introductory copy explaining the tool, the interactive application itself can be fetched asynchronously.
- Third-party and auxiliary widgets: Customer support chat widgets, feedback forms, and video player embeds (when placed below the fold) can be deferred until the main document finishes loading.
- Secondary modal content: Image lightboxes, size guides, or share dialogs that are only relevant when a user actively requests them.
Component rendering decision matrix
| Component Type | Recommended Strategy | SEO Impact if Client-Only (CSR) | Performance Impact if Client-Only (CSR) |
|---|---|---|---|
| Above-the-fold Hero & Primary Heading | SSR / SSG in initial HTML | Delays primary content discovery until rendering phase | Degrades LCP due to sequential network waterfalls |
| Primary Body Copy & Product Descriptions | SSR / SSG in initial HTML | Invisible to non-rendering bots; vulnerable to chunk fetch failures | Can trigger layout shifts (CLS) if unstyled placeholders expand |
| Main Navigation, Breadcrumbs & Pagination | SSR / SSG in initial HTML | Slows down crawl discovery of linked internal URLs | Minimal performance benefit; HTML links are lightweight |
| Below-the-fold Interactive Charts / Calculators | Dynamic Import (SSR or CSR with fixed-size container) | Neutral if descriptive text is already present in static HTML | Reduces initial bundle size and main-thread parse time (helps INP) |
| User Account Modals, Cart Drawers & Chat Widgets | Dynamic Import (Client-Only / CSR) | None (non-indexable utility elements) | Removes unused JavaScript from initial load path |
The Above-the-Fold LCP Trade-Off
A common optimization anti-pattern occurs when developers apply client-only dynamic imports to every component on a page to maximize initial bundle reduction, inadvertently lazy loading the above-the-fold hero banner, primary product image, or main heading. While this shrinks the initial HTML and main JavaScript bundle, it introduces a severe penalty to Largest Contentful Paint (LCP) alongside delaying content visibility for crawlers.
When an above-the-fold component is dynamically imported on the client, the browser cannot discover the LCP image or render the primary text block during the initial HTML parse. Instead, it must complete a sequential network waterfall: download the HTML, download and execute the main JavaScript bundle, parse the dynamic
import()
call, fetch the secondary component chunk, execute that chunk, and only then request the underlying image or paint the text. Keeping above-the-fold indexable components in the initial server-rendered HTML ensures both immediate crawler visibility and early resource discovery for the browser's preload scanner.
Implementation pitfalls that hide content from crawlers
Even when a search engine uses a headless browser like Google's Web Rendering Service (WRS) to execute JavaScript, specific code-level patterns can prevent dynamically imported modules from ever reaching the rendered DOM. Because automated rendering environments do not behave like human users, gating an
import()
call behind browser events or disabling server-side rendering on indexable components can prevent or delay DOM injection.
Interaction traps: Binding dynamic imports to user events
A common performance pattern is deferring the download of a component chunk until a user explicitly interacts with a trigger element, such as clicking a tab, hovering over a navigation menu, or pressing a key. While this pattern works well for non-indexable application state (like opening a settings modal), it hides content from search engines when applied to indexable text or internal links.
Search crawlers generally do not simulate arbitrary user interactions such as
onClick
,
onHover
,
onMouseEnter
, or
onKeyDown
events during page rendering. If the dynamic
import()
statement sits inside an event handler, the network request for that JavaScript chunk is never initiated, and the resulting HTML nodes are never injected into the DOM.
// Anti-pattern for indexable content: Chunk is only fetched on click
function ProductSpecifications() {
  const [SpecsComponent, setSpecsComponent] = useState(null);

  const handleLoadSpecs = async () => {
    const module = await import('./DetailedSpecs.js');
    setSpecsComponent(() => module.default);
  };

  return (
    <div>
      <button onClick={handleLoadSpecs}>View Technical Specifications</button>
      {SpecsComponent && <SpecsComponent />}
    </div>
  );
}
In the example above, a rendering crawler sees only the button element. If tabbed interfaces, accordions, or mega-menus contain content or crawlable links that need to be indexed, the underlying HTML must be rendered into the DOM during initial page load-even if visual display is toggled via CSS-rather than fetched on demand via an event-driven
import()
.
Viewport and scroll traps
Developers often combine dynamic imports with the
IntersectionObserver
API or scroll event listeners to lazy load below-the-fold sections-such as related product carousels, customer reviews, or supplementary article sections-only as the user scrolls down the page.
During automated rendering, Google WRS does not scroll the page in increments like a human user; instead, headless Chromium typically renders the page using a tall virtual viewport to capture content beyond the initial fold. However, relying on scroll-driven triggers to initiate network requests introduces two distinct failure conditions:
-
If the component loader listens specifically for browser
scrollevents (window.addEventListener('scroll', ...)) rather than viewport intersection, the event never fires during a static viewport expansion, leaving the dynamic import unexecuted. -
If an
IntersectionObserveris configured with restrictive thresholds, large negativerootMarginvalues, or depends on layout shifts from previously loaded chunks to enter the viewport, the observer callback may fail to trigger before the rendering engine takes its final DOM snapshot.
When below-the-fold sections contain indexable copy or internal link modules, their HTML should be included in the initial server response, while reserving
IntersectionObserver
for hydrating interactive behaviors or lazy loading below-the-fold image assets.
Framework-Specific SSR overrides
Modern hybrid frameworks like Next.js, Nuxt, and Remix support Server-Side Rendering (SSR) for dynamically imported components by default. When configured properly, the server executes the module, includes its rendered markup in the initial HTML payload, and splits the client-side JavaScript bundle so it hydrates separately.
However, developers frequently override this behavior when a component references browser-only globals like
window
,
document
, or
localStorage
at the module level, which causes server builds to fail. Passing an SSR-disabling flag resolves the build error quickly, but completely strips the component's HTML from the initial server response.
// Next.js example: Disabling SSR strips the component from initial HTML
import dynamic from 'next/dynamic';

const RelatedArticles = dynamic(() => import('../components/RelatedArticles'), {
  ssr: false,
  loading: () => <p>Loading related articles...</p>,
});
When
{ ssr: false }
is applied in Next.js-or when standard
React.lazy()
is used in a purely client-rendered setup without server-side streaming or prerendering support-the initial HTTP response contains only the fallback placeholder (such as the loading text or spinner). This creates two technical liabilities:
- Crawlers that do not execute JavaScript receive only the fallback state and never see the component's content or links.
- For crawlers that do execute JavaScript, discovery of the component's content is entirely shifted to the client-side rendering pipeline, making it vulnerable to network timeouts, script execution errors, or blocked chunk requests.
Instead of disabling SSR via framework flags to bypass reference errors, keep SSR enabled for indexable components and isolate browser-specific API calls inside lifecycle hooks (such as React's
useEffect
) that only run in the browser after the initial server render is complete.
Bulk Google and Yandex index checker
Verify agency reports and track live SERP status in Google and Yandex to protect your SEO ROI.
Infrastructure failure modes: Blocked chunks and version mismatches
Even when component code properly supports rendering, network and deployment configurations can prevent crawlers from fetching dynamically imported JavaScript chunks. Unlike component-level pitfalls, these failures occur at the infrastructure layer, causing module requests to fail before execution can begin.
Blocked asset directories in robots.txt and CDN rules
Module bundlers compile dynamic imports into separate files stored in framework-specific output directories, such as
/_next/static/chunks/
in Next.js,
/assets/
in Vite, or
/static/js/
in standard Webpack setups. When a rendering engine processes the page, it must be able to fetch these external chunk URLs over the network.
A common operational error is applying broad
Disallow
directives in
robots.txt
to hide build artifacts or internal application folders:
User-agent: *
# Prevents crawlers from fetching Next.js JavaScript chunks
Disallow: /_next/
# Prevents crawlers from fetching standard static build assets
Disallow: /static/
Search engine rendering engines obey
robots.txt
directives for subresources. If a dynamically imported chunk resides in a disallowed path, the crawler aborts the network request before fetching the file. Similarly, CDN firewall rules, hotlink protection, or cross-origin resource sharing (CORS) misconfigurations on asset subdomains can reject requests from headless crawler user agents.
When a chunk request is blocked, the
import()
promise rejects inside the rendering environment. Depending on how the application handles promise rejections, this causes one of two rendering outcomes:
- If the dynamic component is wrapped in a framework error boundary, the rendering engine captures the error fallback UI instead of the target content.
- If the rejection goes unhandled, the script throws an uncaught runtime exception, which can halt client-side rendering and leave the component tree incomplete or empty.
To prevent this, ensure that all public static asset paths where bundlers emit code-split JavaScript files remain accessible to crawlers in both
robots.txt
and CDN security policies.
Deployment cache invalidation and ChunkLoadError
Modern build tools append content hashes to generated chunk filenames (for example,
ProductDetails.a1b2c3d4.js
) so browsers and CDNs can cache static files indefinitely. When a developer modifies a component and deploys a new build, the bundler generates a new hash (such as
ProductDetails.e5f6g7h8.js
) and updates the HTML document and runtime manifest to reference the new filename.
This mechanism creates a race condition during deployments when old build artifacts are immediately purged from the origin server or CDN:
-
A search crawler fetches the HTML document and runtime manifest for a page just before a new deployment, or receives a slightly stale HTML response from an edge cache. This document references
ProductDetails.a1b2c3d4.js. -
A new deployment completes. The deployment pipeline deletes the previous build directory and replaces it with the new build containing
ProductDetails.e5f6g7h8.js. -
The rendering engine executes the JavaScript from the earlier HTML payload and requests
ProductDetails.a1b2c3d4.js. -
Because the old file was deleted during deployment, the server returns an HTTP 404 status (or serves a fallback 404 HTML page with a
text/htmlMIME type, which triggers a strict MIME-type error in the browser console). -
The bundler runtime fails to parse the module and throws a
ChunkLoadError, leaving the dynamically imported content missing from the rendered DOM.
This version-hash mismatch is particularly common when crawling and rendering do not happen simultaneously, or on websites with frequent CI/CD deployments.
Mitigating version mismatches across deployments
Preventing
ChunkLoadError
exceptions during crawling requires coordinating how HTML documents and hashed static assets are cached and retained across releases:
- Retain previous build assets temporarily: Configure deployment pipelines or object storage buckets (such as AWS S3 or Google Cloud Storage) to keep static chunks from the previous several builds-or for a rolling window of several days-rather than wiping the output directory on every deploy. Because chunk filenames contain unique content hashes, retaining old JavaScript files alongside new ones does not cause naming collisions.
-
Separate cache headers for HTML and hashed chunks: Configure the CDN to serve hashed JavaScript chunks with long-lived, immutable caching (
Cache-Control: public, max-age=31536000, immutable). Once a chunk is requested and cached at the CDN edge, the CDN can continue serving that specific hashed file to crawlers even if the origin server moves on to a newer release. Conversely, HTML documents and non-hashed build manifests should use short TTLs orCache-Control: no-cache(ors-maxagewith immediate purge-on-deploy) so crawlers always receive the latest chunk references. -
Avoid serving HTML fallbacks for missing static paths: Configure the web server or single-page application (SPA) router so that missing requests under static asset paths (like
/assets/*or/_next/static/*) return a strict HTTP 404 status rather than falling back toindex.htmlwith a 200 OK status. While a 404 still causes the chunk load to fail, it prevents the CDN from accidentally caching an HTML document under a permanent JavaScript URL.
Auditing and validating dynamically imported content
Verifying whether dynamically imported modules are accessible to search engines requires a structured diagnostic workflow. Rather than assuming that a component visible in a standard browser session is also visible to crawlers, technical teams should test the page across three stages: the initial server response, the unassisted client-side network waterfall, and the search engine's rendered DOM snapshot.
Step 1: Compare the raw HTTP response against the inspected DOM
The first step is to isolate which page elements are delivered in the initial server payload and which depend entirely on client-side chunk fetching. Browser developer tools display the live, post-execution DOM in the Elements panel, which can obscure whether a component was rendered on the server or injected later via JavaScript.
-
Fetch the raw HTML response without executing JavaScript by using the browser's View Page Source function or running a basic command-line request:
curl -s https://example.com/target-page | grep -i "target content snippet" - Open the same URL in Chrome DevTools, navigate to the Elements panel, and search for the exact same text snippet or link element in the live DOM tree.
-
Compare the two outputs. If the target body copy or
<a href>links exist in the Elements panel but are absent from the raw HTTP response, the component relies on client-side execution. Note that modern frameworks using streaming SSR or React Server Components may include the content inside inline<script>payloads rather than standard HTML tags in the raw source; however, if the text is completely missing from the raw response, it must be fetched via a separate network request during rendering.
Step 2: Observe unassisted chunk requests in the network panel
Once client-dependent components are identified, verify whether their corresponding JavaScript chunks are requested automatically upon initial page load or if they wait for a user trigger that a crawler will not perform.
- Open Chrome DevTools and select the Network panel.
- Check the Disable cache checkbox to force the browser to request all assets fresh, and select the JS filter to isolate JavaScript files.
- Position the mouse cursor outside the browser viewport so no accidental hover or scroll events occur, then reload the page.
- Inspect the network waterfall once network activity settles. Identify the specific dynamically imported chunks responsible for the target content.
- Begin scrolling down the page or clicking interactive tabs while watching the Network panel. Any new JavaScript chunk requests that appear only after scrolling or clicking indicate that the dynamic import is gated behind an event listener or intersection threshold. Content inside these delayed chunks is at high risk of being missed during automated rendering.
Step 3: Validate rendering in Google search console
Local browser testing confirms how the application behaves, but final validation requires testing how Google's Web Rendering Service processes the page and its asynchronous chunks. Use the URL Inspection Tool in Google Search Console (via the Test Live URL option) or the Rich Results Test for pages that are not yet verified in a Search Console property.
- Run a live test on the target URL and open the View Tested Page panel.
-
Select the HTML tab to inspect the Rendered HTML. Search the code directly for the target text fragments and verify that crawlable links are rendered as standard
<a href="...">elements with resolved URLs. Do not rely on the Screenshot tab for validation; a component may fail to appear in the visual screenshot due to viewport sizing while still existing in the rendered DOM, or conversely, text may be visually rendered inside a canvas or image element without existing as indexable markup. -
Switch to the More Info tab and open the Page resources report. Review the list of couldn't be loaded resources to check whether any hashed JavaScript chunk URLs failed to fetch due to
robots.txtblocks, HTTP 404 responses from deployment version mismatches, or network timeouts. -
Check the Console messages panel under More Info. Look specifically for uncaught exceptions such as
ChunkLoadError, failed dynamic import promises, or syntax errors that halted script execution before the component could mount to the DOM.
| Diagnostic Observation | Root Cause | Recommended Action |
|---|---|---|
| Content is present in raw HTML and Rendered HTML | Component is server-rendered (SSR or SSG) before hydration | No action needed; content is accessible to both rendering and non-rendering crawlers. |
| Content is missing from raw HTML, but present in Rendered HTML | Chunk is fetched automatically on load and executed by WRS | Acceptable for secondary content, though non-rendering bots will miss it. Move primary SEO elements to SSR if non-rendering crawlers are a priority. |
| Content is missing from Rendered HTML; no chunk error in Page resources | Import is likely gated behind user interaction or a strict scroll observer | Refactor the component to load eagerly during initial render or enable SSR for that module. |
| Content is missing from Rendered HTML; chunk shows Failed or Redirection error in Page resources | Infrastructure block, CDN restriction, or stale deployment hash (404) |
Unblock static asset directories in
robots.txt
and configure build retention or immutable CDN caching for hashed chunks.
|