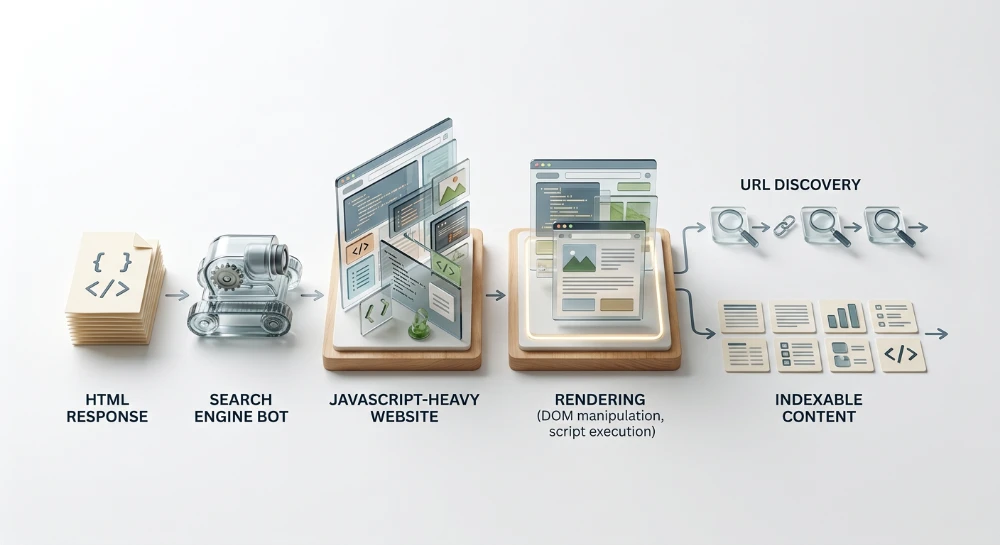
JavaScript SEO addresses how search engines crawl, render, and index websites that rely on JavaScript to deliver content, navigation, or metadata. The core technical challenge lies in the discrepancy between the initial HTTP response-the raw HTML source sent by the server-and the rendered Document Object Model (DOM) produced after client-side scripts execute. When primary page text, internal links, or indexation directives are absent from the initial HTML payload, search engines must execute JavaScript before they can fully evaluate the page.
While search engines like Google use a headless browser to render pages, relying on client-side execution introduces additional processing steps and potential failure points. A crawler first parses the raw HTML response for immediate directives and links before queuing the page for rendering. If robots.txt rules block required JavaScript bundles, if API requests fail or time out, or if the initial HTML contains a restrictive directive like a
noindex
tag, the search engine may never assemble or index the complete DOM. Furthermore, many secondary crawlers, social media scrapers, and automated data fetchers do not execute JavaScript at all, reading only the initial server response.
Ensuring search visibility on JavaScript-driven sites requires aligning the rendering architecture with how crawlers process the pipeline from initial fetch to final indexing. Technical teams must account for how client-side routing affects URL discovery, how dynamic DOM manipulation interacts with HTTP status codes and canonical tags, and how lazy-loaded elements behave without human interaction. Validating these implementations involves comparing raw source code against the rendered DOM to confirm that search engines receive complete, unambiguous signals at every stage of crawling and rendering.
The search engine processing pipeline: Crawling, rendering, and indexing
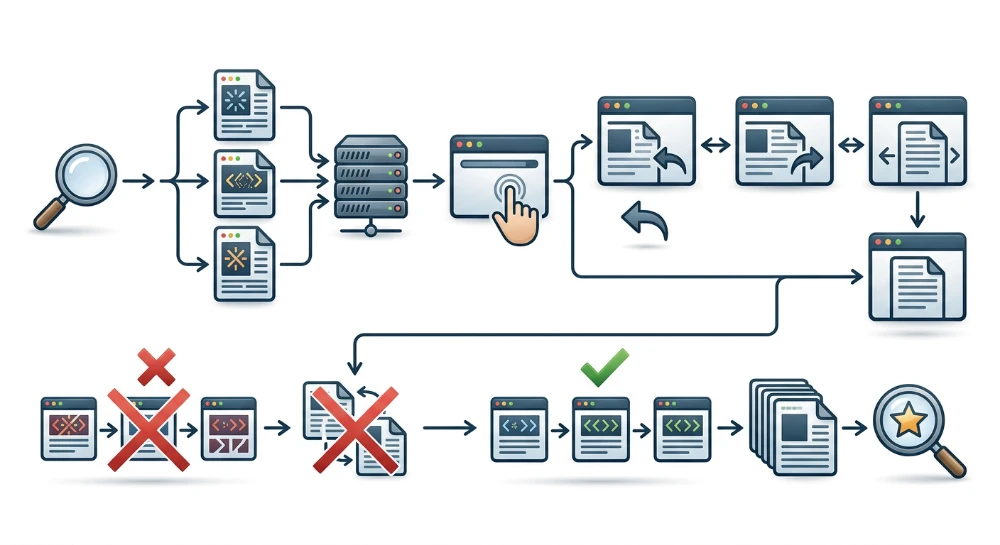
Rendering-capable search engines process webpages through a multi-stage pipeline rather than executing JavaScript immediately upon fetching a URL. In Google's documented architecture, this pipeline separates initial downloading and HTML parsing from browser execution-handled by the Web Rendering Service (WRS), which is based on headless Chromium-before passing the final document to the indexing system.
-
Initial HTTP Fetch and Raw HTML Parsing:
The crawler requests a URL from the server and receives the HTTP status code, response headers, and raw HTML payload. Before any JavaScript executes, the parser reads this initial response to extract immediate page-level directives (such as
X-Robots-Tagheaders,<meta name="robots">tags, and initialrel="canonical"links) and standard<a href>links present in the server response. Newly discovered URLs are sent back to the crawl scheduler. -
The Render Queue:
If the initial HTTP response permits indexing (meaning it returns a valid status code and lacks a
noindexdirective), the page is placed into a rendering queue. Because spinning up a headless browser environment and executing scripts requires significantly more compute resources than parsing static text, rendering is deferred until system resources are available. The delay between the initial fetch and rendering is conditional on queue demand and site scale rather than a fixed time window. - JavaScript Execution and DOM Assembly: Once the page reaches the front of the queue, the Web Rendering Service loads the document into headless Chromium. The renderer fetches external JavaScript bundles, stylesheets, and XHR/Fetch API payloads required by the page, executes the scripts, and constructs the rendered Document Object Model (DOM).
- Rendered Parsing and Indexing: After the renderer determines that page loading has settled, it takes a snapshot of the rendered HTML. The indexing pipeline parses this rendered DOM to extract the final page text, metadata modifications, structured data, and any additional links injected by JavaScript.
Operational constraints: Resource availability and caching
The headless browser in the rendering stage operates under strict network and caching behaviors that directly affect whether the DOM assembles accurately.
First, the renderer respects
robots.txt
directives when requesting sub-resources. During rendering, a page often requests external JavaScript files, CSS, and JSON payloads from internal or third-party APIs. If a
Disallow
rule in
robots.txt
blocks the URL path for a core JavaScript bundle or a backend API endpoint, the renderer will not fetch that resource. Consequently, the scripts depending on those files fail to execute, leaving the rendered DOM incomplete. Technical audits must verify that
robots.txt
permits crawler access to all endpoints required to construct primary page content and navigation.
Second, search engine crawlers aggressively cache static sub-resources (such as
.js
and
.css
files) across multiple page renders to reduce network overhead, sometimes ignoring standard HTTP
Cache-Control
headers. If a development team deploys updated JavaScript code that alters how content or metadata is rendered, but keeps the filename identical (for example,
/static/app.js
), the Web Rendering Service may execute a cached, outdated version of the script against the new HTML. To ensure the renderer fetches updated code upon deployment, build pipelines should implement content fingerprinting-appending a unique hash of the file's contents to the filename (such as
/static/app.8f9b2a.js
) so that code changes generate a new URL.
Crawler capability differences across user agents
While Googlebot uses an evergreen headless Chromium renderer and Bingbot executes JavaScript to a lesser extent, full client-side rendering support is not universal across automated user agents. Evaluating a site's rendering requirements depends on which bots need to extract content from the URLs.
| Crawler Category | JavaScript Execution Capability | Primary Data Source Extracted |
|---|---|---|
| Major Search Engines (e.g., Googlebot, Bingbot) | Executes JavaScript via a headless browser pipeline, subject to queue conditions and resource availability. | Both initial raw HTML and the final rendered DOM. |
| Social Media Scrapers (e.g., Open Graph, X/Twitter, LinkedIn bots) | Generally does not execute JavaScript. |
Initial raw HTML response only (specifically
<head>
metadata for link previews).
|
| AI/LLM Data Fetchers and Traditional Static Crawlers | Typically does not execute JavaScript; fetches raw HTTP payloads for speed and low compute cost. | Initial raw HTML response only. |
Because social media preview generators and many AI retrieval bots only parse the initial server response, any Open Graph tags, title tags, or primary body text injected exclusively in the browser via client-side JavaScript will remain invisible to those systems, even if Googlebot successfully renders and indexes the page.
Run a deep technical crawl to identify 4xx errors, missing meta tags, and indexation blockers.
How rendering architectures affect HTML delivery
A website's rendering architecture determines whether primary content and metadata arrive in the initial HTTP response or appear only after JavaScript executes in the browser. For search engine crawlers and automated user agents, the chosen architecture dictates whether a URL can be evaluated immediately from raw HTML or must wait for client-side execution.
| Architecture | Initial HTTP Response Payload | Client-Side Execution Role | Crawler Processing Profile |
|---|---|---|---|
| Client-Side Rendering (CSR) |
Minimal HTML shell (e.g.,
<div id="root"></div>
) and script references.
|
Fetches data, constructs the DOM, and injects content and metadata. | Requires full JavaScript rendering; non-executing bots see an empty document. |
| Server-Side Rendering (SSR) |
Complete HTML document generated per request, including body content and
<head>
tags.
|
Hydrates the existing DOM to attach event listeners and enable interactivity. | Content and links are available immediately in raw HTML to all user agents. |
| Static Site Generation (SSG) / Incremental Static Regeneration (ISR) | Complete HTML document pre-built at deploy time or regenerated in the background. | Hydrates pre-built markup into an interactive application if using a frontend framework. | Fastest initial HTML delivery; zero dependency on client-side rendering for initial content extraction. |
| Dynamic Rendering | Pre-rendered static HTML sent to detected bots; CSR shell sent to human users. | Full CSR execution for standard browser user agents; none required for recognized bots. | Delivers immediate HTML to listed user agents, but introduces parity and maintenance risks. |
Client-Side rendering (CSR) in single page applications
In a strictly client-side rendered Single Page Application (SPA), the web server responds to document requests with a generic HTML skeleton. This initial payload typically contains default or placeholder
<head>
metadata, an empty mounting element (such as
<div id="app"></div>
), and links to JavaScript bundles.
<!DOCTYPE html>
<html lang="en">
<head>
  <meta charset="utf-8">
  <title>Default App Title</title>
  <script src="/static/js/main.a1b2c3.js" defer></script>
</head>
<body>
  <div id="app"></div>
</body>
</html>
Because the initial HTTP response contains no page-specific text, headings, or navigation links, crawlers cannot extract meaningful content during the initial fetch. The URL depends entirely on the search engine's rendering pipeline to download the JavaScript bundles, execute API requests to retrieve content, and assemble the rendered DOM. If an API call fails, times out, or is blocked during the headless browser session, the resulting DOM remains empty or incomplete.
Server-Side rendering (SSR) and static site generation (SSG)
Server-Side Rendering (SSR) and Static Site Generation (SSG) shift HTML assembly away from the client browser, ensuring the initial HTTP response contains the complete document markup, including populated
<title>
tags, meta descriptions, canonical tags, structured data, and primary body copy.
- Server-Side Rendering (SSR): The server executes the JavaScript framework on every incoming request (or behind a caching layer), fetches required data from backend APIs, and compiles the full HTML string before sending the response. This approach suits dynamic pages where content changes frequently.
- Static Site Generation (SSG) and Incremental Static Regeneration (ISR): SSG compiles the complete HTML for every URL during the build process, serving static files directly from a CDN or origin server. ISR extends this model by allowing pages to be generated or updated on-demand in the background after deployment without requiring a full site rebuild.
With both SSR and SSG, search engines can parse text and extract links immediately upon receiving the raw HTML response, bypassing the need to wait for the rendering queue to discover core content. Furthermore, user agents that do not execute JavaScript receive the complete document.
Hybrid rendering and hydration risks
Modern JavaScript frameworks (such as Next.js, Nuxt, and Angular) commonly use a hybrid model: the initial request is fulfilled via SSR or SSG, and the browser then performs hydration. During hydration, the client-side JavaScript bundle downloads, executes, and attaches event listeners to the existing server-rendered HTML nodes, transitioning the static document into an interactive SPA for subsequent navigation.
While hybrid rendering provides complete initial HTML, the hydration phase introduces a specific technical failure mode for rendering-capable crawlers. Because search engines like Google still execute JavaScript on server-rendered pages to inspect the final rendered state, client-side scripts can inadvertently overwrite or strip valid server-delivered markup.
Common hydration and post-render overwrite issues include:
- Hydration Mismatches and DOM Replacement: If the UI tree generated by the client-side JavaScript does not match the HTML structure sent by the server (for example, due to differing locale settings, timestamps, or uninitialized client state), the framework may discard the server-rendered DOM subtree and re-render it from scratch. If client-side data fetching fails during this fallback, content that was present in the raw HTML can disappear from the final rendered DOM.
-
Client-Side State Overwriting Metadata:
A server may send an accurate page-specific
<title>or canonical tag in the raw HTML, only for an improperly configured client-side state manager or head-management library to overwrite it with a generic default value when the JavaScript initializes. - Unauthenticated Client API Calls: A page might render full content on the server using internal credentials, but upon hydration, the client-side code triggers a redundant API fetch that fails or returns an empty state, replacing the server-rendered text with a loading spinner or error message in the rendered DOM.
Dynamic rendering as a legacy workaround
Dynamic rendering is an architectural workaround where the web server inspects the incoming
User-Agent
HTTP header to route requests differently. Standard user browsers receive the normal client-side rendered SPA shell, while known bot user agents are routed to a separate pre-rendering service (such as Puppeteer or Rendertron) that executes the JavaScript and returns a static HTML snapshot.
Google's documentation explicitly characterizes dynamic rendering as a temporary workaround rather than a recommended long-term solution. Maintaining a separate rendering layer solely for bots introduces operational overhead and several failure modes:
- Content Parity and Cloaking Risks: If the pre-renderer caches outdated snapshots, fails to load specific scripts, or uses a different viewport configuration than the main application, the HTML served to crawlers can diverge from what human users see. Search engines may treat significant discrepancies between the bot payload and user payload as cloaking.
- User-Agent List Maintenance: The routing logic requires maintaining an accurate list of crawler user-agent strings. Any legitimate crawler, social scraper, or AI fetcher omitted from the routing configuration receives the unrendered CSR shell.
- Infrastructure Overhead: Running a separate headless browser fleet to generate snapshots on the fly consumes substantial server compute and can increase server response times for crawlers if snapshots are not cached effectively.
For sites currently relying on dynamic rendering, migrating to native SSR, SSG, or ISR eliminates the dual-pipeline architecture and ensures both users and automated crawlers receive the same initial HTML payload.
URL discovery, internal linking, and Client-Side routing
Search engine crawlers discover new pages primarily by extracting URLs from links on previously crawled pages. In JavaScript frameworks, developers often replace standard HTML navigation with event listeners and programmatic state changes to create seamless page transitions. However, if these navigation patterns do not expose standard HTML link markup in the DOM, crawlers cannot extract the destination URLs, isolating the underlying pages from internal link discovery.
Requirements for crawlable links
For a search engine to reliably extract and follow an internal link, the link must be formatted as a standard HTML anchor element (
<a>
) containing an
href
attribute that resolves to a valid web address (HTTP or HTTPS). Crawlers evaluate the DOM for these specific attributes rather than interacting with the page like a human user. Because search engine renderers generally do not simulate arbitrary user clicks on interactive elements to see if a navigation event occurs, links that rely exclusively on JavaScript click handlers are invisible to the link extraction process.
Common frontend navigation patterns yield different outcomes during link extraction:
| Implementation Pattern | Code Example | Crawler Extraction Behavior |
|---|---|---|
| Standard anchor tag with resolvable path |
<a href="/products/shoes">Shoes</a>
|
Crawlable. The crawler extracts the
href
value and resolves it against the document base URL.
|
| Anchor tag with progressive enhancement |
<a href="/products/shoes" onclick="navigate(event, '/products/shoes')">Shoes</a>
|
Crawlable. Human users experience fast client-side navigation via the click handler, while crawlers extract the valid
href
attribute.
|
| Anchor tag with pseudo-protocol or empty fragment |
<a href="javascript:void(0)" onclick="navigate('/products/shoes')">Shoes</a>
|
Not crawlable. The
href
attribute does not contain a resolvable URL path.
|
| Non-anchor element with event listener |
<button onClick={() => router.push('/products/shoes')}>Shoes</button>
|
Not crawlable. Crawlers do not extract URLs from
<button>
,
<div>
, or
<span>
elements, nor do they execute the attached event handler.
|
| Anchor tag using non-standard attributes |
<a data-url="/products/shoes">Shoes</a>
|
Not crawlable. Search engines look specifically for the
href
attribute and ignore custom data attributes for link discovery.
|
Modern JavaScript routing libraries (such as React Router, Vue Router, or Next.js
<Link>
components) typically compile down to standard
<a href="...">
elements in the DOM while intercepting clicks in the browser via
event.preventDefault()
. When building custom navigation components, pagination controls, or product grids, developers should verify in the browser's DOM inspector that the final rendered output produces an actual
<a>
tag with a complete URL path rather than a generic container attached to an event listener.
Discovery timing: Raw HTML links vs. JavaScript-Injected links
While rendering-capable search engines like Google can extract
<a href>
links from both the initial raw HTML and the final rendered DOM, the stage at which the link appears affects discovery timing and crawler compatibility:
- Links in the Raw HTML: When anchor tags are present in the initial server response (via SSR, SSG, or static HTML), the crawler extracts and queues the destination URLs immediately during the initial crawl pass, before any JavaScript is executed. Furthermore, crawlers and data fetchers that do not execute JavaScript can still discover and follow these links.
-
Links Injected via JavaScript:
In a pure CSR architecture, or when navigation menus and related-product modules are fetched asynchronously after page load, the initial HTML contains no links. The search engine must first pass the page through the rendering queue, execute the JavaScript, and wait for the API responses to populate the DOM before it can discover the outgoing URLs. If the script responsible for rendering the navigation fails, times out, or is blocked by
robots.txt, those internal links are never discovered from that page.
Client-Side routing: History API vs. hash fragments
In a Single Page Application, navigating between views happens inside the browser without requesting a full page reload from the server. For search engines to index individual views-such as distinct product pages, category filters, or articles-each view must be assigned a unique, clean URL managed through the browser's History API.
History API routing (recommended)
Modern SPA routers use the HTML5 History API (specifically
history.pushState()
and
history.replaceState()
) to update the URL in the browser's address bar when a user navigates to a new view. This produces standard path structures such as
https://example.com/category/widgets
. Because these are distinct, standard URLs, search engines can crawl, render, and index each view independently.
Implementing History API routing requires proper server configuration. When a user clicks a link inside the app, the client-side router handles the transition. However, when a search engine crawler requests
https://example.com/category/widgets
directly, the request goes straight to the web server. In a CSR setup, the server must be configured with a fallback rule that serves the application's entry shell (usually
index.html
) for all valid application routes, allowing the client-side router to read the URL path and render the corresponding view.
Hash-Based routing (legacy pattern)
Older SPA frameworks often relied on hash-based routing (such as
https://example.com/#/category/widgets
or
https://example.com/#widgets
) because changing the URL fragment (everything after the
#
symbol) does not trigger a browser page reload and requires no special server configuration.
Hash-based routing prevents reliable indexing of individual application states. According to standard URI specifications (RFC 3986), fragment identifiers are processed exclusively on the client side to point to a secondary resource or section within a primary document; browsers and crawlers strip the fragment before sending the HTTP request to the server. Consequently, search engines generally treat
https://example.com/#/about
and
https://example.com/#/contact
as references to the exact same base document (
https://example.com/
). Crawlers typically ignore the fragment portion and only index the root URL, leaving all view states behind the hash unindexed. Applications still using hash routing should migrate their router configuration to the History API so every indexable view resolves to a distinct path.
SEO structure and reciprocal link analyzer
Detect orphan pages, deep click depths, and toxic reciprocal links built by careless agencies.
Indexation directives, meta tags, and HTTP status codes in JavaScript
Search engines evaluate page-level directives and metadata at two distinct stages: once when parsing the initial HTTP response and raw HTML, and again after executing JavaScript to construct the rendered DOM. When client-side scripts inject, modify, or attempt to remove tags, conflicts between the initial source and the final DOM can cause search engines to drop the page from the rendering pipeline or misinterpret indexing signals.
Meta robots and the noindex trap
The sequence in which search engines process
noindex
directives creates a common failure mode in JavaScript applications. When a rendering-capable crawler like Googlebot fetches a URL, it checks the HTTP response headers (specifically
X-Robots-Tag
) and the raw HTML
<meta name="robots">
tag before queuing the page for rendering. If a
noindex
directive is present in the initial payload, the crawler obeys that directive immediately and skips the rendering phase altogether.
Because the headless browser never executes the page's JavaScript when an initial
noindex
is detected, client-side scripts cannot be used to remove or change a
noindex
tag to
index
. A frequent developer pattern in Single Page Applications (SPAs) is to place a default
<meta name="robots" content="noindex">
in the base
index.html
shell to prevent empty error states from being indexed, relying on the router to overwrite the tag with
index, follow
once an API call succeeds. Under this configuration, search engines read the initial
noindex
, abort rendering, and never see the JavaScript modification, leaving valid pages excluded from the index.
Conversely, adding a
noindex
tag via JavaScript does work as intended. If the initial HTML allows indexing, the crawler proceeds to render the page. If client-side code subsequently injects
<meta name="robots" content="noindex">
into the DOM-for instance, when an API returns an empty product category or an out-of-stock state-the indexer reads the newly injected directive from the rendered DOM and excludes the URL.
Canonical tags and conflicting signals
Search engines that render JavaScript can extract and respect
<link rel="canonical">
tags injected into the DOM during client-side execution. However, relying on JavaScript to manage canonical URLs introduces strict consistency requirements:
- If the raw HTML contains no canonical tag, a single canonical tag injected via JavaScript can be processed cleanly after rendering completes.
- If the raw HTML includes a default canonical tag (such as a self-referencing tag pointing to the root domain in an SPA shell) and JavaScript later injects a second canonical tag or modifies the existing attribute to point to the specific route, the crawler encounters conflicting signals between the raw parse and the rendered DOM.
-
If a script appends a new canonical tag without removing an existing one, leaving two
rel="canonical"elements in the rendered<head>, search engines may ignore both declarations and select a canonical URL based on other heuristics.
Whenever the rendering architecture allows, canonical tags should be delivered in the initial HTML response. If a purely client-side architecture requires injecting the canonical tag via JavaScript, the base HTML shell must omit any placeholder canonical element so that only one definitive tag ever exists in the document lifecycle.
Titles, meta descriptions, and structured data
Descriptive metadata and structured data are more tolerant of client-side manipulation than restrictive crawling directives. Rendering search engines read the
<title>
element,
<meta name="description">
, and JSON-LD (
<script type="application/ld+json">
) blocks from the final rendered DOM.
If a page serves a generic boilerplate title in the raw HTML and updates it via a state management library (such as React Helmet or Vue Meta) once component data resolves, the indexer processes the updated string. Similarly, JSON-LD blocks assembled dynamically in the browser from API responses are extracted and remain eligible for rich result processing, provided the scripts execute without unhandled exceptions and finish injecting the markup before the renderer takes its snapshot of the DOM.
Two operational constraints still apply to client-side metadata:
-
When modifying existing
<title>or<meta name="description">tags, the client-side head manager must overwrite the existing DOM node rather than appending duplicate elements to the<head>. - Crawlers and external systems that do not execute JavaScript-including social media preview scrapers (which read Open Graph and Twitter Card tags) and many non-rendering bots-only read the initial raw HTML. If accurate link previews or immediate metadata extraction by non-rendering user agents are required, metadata and structured data must be rendered on the server.
| Page-Level Element | Raw HTML has X, JS changes to Y | Raw HTML is empty, JS injects Y | Recommended Delivery Method |
|---|---|---|---|
noindex
Directive
|
If X is
noindex
, rendering is skipped; Y is ignored.
|
If Y is
noindex
, it is respected after rendering.
|
Server response (HTTP header or raw HTML) for intentional blocks; JS injection only for dynamic error/empty states. |
rel="canonical"
|
High risk of conflicting signals; crawler may ignore Y. | Supported by rendering crawlers if only one tag is injected. | Initial raw HTML whenever possible; if using JS, ensure zero canonical tags exist in the raw HTML shell. |
<title>
and Meta Description
|
Y overwrites X in the rendered DOM (if mutated in place). | Y is processed after rendering completes. | Initial HTML preferred for non-rendering bots and social scrapers; JS injection supported by rendering search engines. |
| JSON-LD Structured Data | Both or modified blocks are parsed from the rendered DOM. | Y is parsed and eligible for rich results if injection completes in time. | Initial HTML or reliable, unblocked JS injection that does not depend on slow third-party API calls. |
HTTP status codes and soft 404s in Client-Side rendering
A fundamental limitation of Client-Side Rendering (CSR) is that JavaScript running in the browser cannot set or alter the HTTP status code of the initial document response. In a standard SPA configuration, the web server uses a catch-all routing rule that returns the base
index.html
file with an
HTTP 200 OK
status code for every requested path, leaving route validation to the client-side application.
When a crawler requests a URL that does not exist (for example, a deleted product URL or a mistyped path), the server still responds with
HTTP 200 OK
and delivers the SPA shell. Once the JavaScript executes in the headless browser, the router recognizes that the path matches no valid route or receives a
404
response from an internal data API, and renders a visual "Page Not Found" component in the DOM.
Delivering error-page content alongside an
HTTP 200 OK
status code creates a soft 404. While search engines attempt to detect soft 404s automatically by analyzing the rendered text, relying on automated detection can lead to invalid or thin error URLs being indexed as legitimate pages, or cause the crawler to waste resources repeatedly fetching nonexistent routes.
When migrating to Server-Side Rendering (SSR) to return a native
HTTP 404 Not Found
status code is not feasible, developers can remediate client-side error states using one of two patterns:
-
Client-Side Noindex Injection:
Configure the application's error boundary or catch-all "Not Found" route component to immediately inject
<meta name="robots" content="noindex">into the document<head>when an invalid route or empty API response is detected. Although the initial status code remains200 OK, the renderednoindexexplicitly instructs the search engine not to index the error view. -
Client-Side Redirect to a Dedicated 404 Endpoint:
Configure the web server to return a true
HTTP 404status code for a specific static path, such as/404or/not-found.html. When the client-side router determines that a requested URL is invalid, executewindow.location.replace('/404')to redirect the headless browser to that endpoint. Usingreplace()rather than standard navigation keeps the broken URL out of the session history while allowing the crawler to follow the redirect and encounter the actual404HTTP response code.
Lazy-Loaded content and user interaction dependencies
Search engine rendering engines do not interact with web pages like human users. When a headless browser such as Google's Web Rendering Service loads a page, it remains stateless and passive: it does not move a cursor, click interactive elements, type into inputs, or physically scroll down the document.
To capture content positioned below the initial fold without simulating scroll events, search engine renderers typically expand the virtual viewport to a tall vertical height during rendering. Anything that loads automatically when the viewport expands becomes part of the rendered DOM passed to the indexer; anything that requires an explicit user action or a continuous scroll event listener generally remains unloaded.
Viewport expansion vs. scroll event listeners
Deferring offscreen images and text improves initial page load performance, but the JavaScript mechanism used to detect visibility determines whether search engines can discover that content.
-
IntersectionObserverAPI: When lazy loading is implemented using the standardIntersectionObserverAPI, the browser checks whether target elements intersect with the current viewport. When the search engine renderer expands its virtual viewport height, elements further down the page enter the intersection area, firing the callback and loading the content into the DOM. -
Native Browser Lazy Loading: Adding the
loading="lazy"attribute to<img>or<iframe>elements delegates visibility detection to the browser engine, which responds reliably to the expanded virtual viewport. -
Scroll Event Listeners: Legacy implementations that attach handlers to
window.onscrollordocument.addEventListener('scroll', ...)and calculatewindow.scrollYoffsets often fail during search engine rendering. Because the renderer resizes the window frame rather than scrolling through the document, thescrollevent may never fire, leaving below-the-fold containers empty in the rendered HTML.
Tabs, accordions, and Click-Triggered content
Interfaces frequently organize secondary information inside tabbed panels, collapsible accordions, or modal drawers. Because crawlers do not click UI triggers to reveal hidden views, the presence of that content in the rendered DOM depends entirely on how the component manages state.
If an accordion or tab component renders all of its text into the DOM on initial load and toggles visibility using CSS properties-such as
display: none
,
visibility: hidden
, or the HTML
hidden
attribute-search engines can parse and index the text directly from the HTML structure.
Conversely, if clicking a tab fires an event handler (such as React conditional rendering tied to local state without DOM presence, or an asynchronous
fetch()
request to an API) that mounts the content only after the click, that content does not exist in the initial rendered DOM. If text or links must be indexed, they should be mounted into the DOM during initial page rendering and hidden visually via CSS until the user interacts with the control.
Infinite scroll and load more pagination
Catalog pages and article feeds commonly replace traditional pagination links with infinite scroll or a "Load More" button. Both patterns present discovery barriers if implemented solely with client-side event triggers:
-
A "Load More" button controlled only by an
onclickhandler without an underlying URL will not be activated by a crawler, preventing discovery of any items beyond the initial batch. -
An infinite scroll feed driven by
IntersectionObservermay trigger once or twice when the renderer expands the virtual viewport, but it will not exhaustively load a multi-page dataset.
To make paginated datasets crawlable alongside dynamic loading, back infinite scroll or "Load More" patterns with discrete, crawlable pagination URLs (such as
?page=2
or
/page/2
) linked via standard
<a href="...">
elements in the DOM. While users can load items dynamically into the current view or update the URL using the History API as they scroll, the static anchor links provide the crawler with direct entry points to fetch and index the deeper segments of the catalog.
| UI Pattern | Crawler-Compatible Implementation | Implementation Pattern at Risk of Omission |
|---|---|---|
| Below-the-fold images and sections |
Native
loading="lazy"
or
IntersectionObserver
checking viewport intersection.
|
Custom scripts listening strictly for
window.onscroll
events.
|
| Tabs and accordions |
Content rendered into the DOM on load and hidden via CSS (
display: none
).
|
Content fetched from an API or mounted into the DOM only after an
onclick
event.
|
| Product grids and article feeds |
"Load More" or infinite scroll backed by crawlable
<a href>
links to paginated URLs.
|
<button>
triggers or scroll listeners that append items without distinct, linked URLs.
|
Bulk Google and Yandex index checker
Verify agency reports and track live SERP status in Google and Yandex to protect your SEO ROI.
Auditing and validating JavaScript rendering
Verifying how search engines process a JavaScript application requires testing the page across four levels: comparing the initial server response against the browser's rendered DOM, testing network dependencies, validating individual templates in search engine tools, and crawling the site at scale.
Step 1: Compare raw source against the rendered DOM
The fastest way to determine which SEO elements depend on client-side execution is to compare the browser's raw HTML view against its live DOM inspector.
- Open a representative URL in Google Chrome, right-click the page, and select View Page Source. This displays the exact raw HTML payload returned by the server before any scripts execute.
- Open Chrome DevTools on the same URL and open the Elements panel. This displays the live, serialized DOM after JavaScript execution.
-
Search both views for primary content and indexation signals to identify discrepancies:
-
Document metadata:
<title>and<meta name="description">tags. -
Directives:
<meta name="robots">and<link rel="canonical">tags. -
Navigation and body content: Primary headings, body copy, and internal
<a href="...">links. -
Structured data:
<script type="application/ld+json">blocks.
-
Document metadata:
When an element is missing from View Page Source but present in the Elements panel, its discovery depends entirely on the crawler executing JavaScript cleanly. A common failure mode occurs when both views contain a directive, such as a canonical tag, but the values differ. If the server outputs a default or self-referencing canonical in the raw HTML and a script later mutates that attribute in the DOM, crawlers may process conflicting signals.
Step 2: Simulate network failures and blocked dependencies
Inspecting the Elements panel in a standard browser session shows what renders under ideal local conditions, often benefiting from cached assets, active user sessions, or fast local network responses. To see how the page behaves when dependencies fail or are restricted, use the Chrome DevTools Network and Console panels.
First, open the Command Menu in Chrome DevTools and disable JavaScript, then reload the page. This immediately reveals what non-rendering crawlers receive and whether server-side rendering is functioning as expected. Re-enable JavaScript before testing individual network requests.
Next, reload the page with the Network panel open and filter by Fetch/XHR and JS. Identify the specific API endpoints and script bundles responsible for populating the main content and navigation. Right-click a third-party script or secondary API request and select the option to block the request URL, then reload the page. If an unhandled rejection in a non-essential script (such as an analytics tracker, personalization widget, or A/B testing tool) halts the execution thread before the main application mounts, the primary content will fail to render. Check the Console panel for uncaught TypeErrors or CORS failures that could interrupt DOM assembly during a headless crawl.
Step 3: Validate templates in search engine testing tools
Local browser checks simulate client-side behavior, but they do not replicate Google's Web Rendering Service (WRS) environment, which operates without persistent storage, enforces its own network timeouts, and obeys
robots.txt
rules. Use Google's diagnostic tools to verify what the search engine renderer actually captures.
-
Google Search Console URL Inspection Tool: Enter a URL and run a live test (Test Live URL). Once complete, open the View Tested Page panel. Inspect the HTML tab to verify that body copy, links, and injected tags appear in the rendered output. Check the Screenshot tab to confirm visual layout and viewport expansion, and review the More Info tab to identify page resources blocked by
robots.txtor uncaught JavaScript console errors encountered during the fetch. - Rich Results Test: For pages that cannot be tested in Search Console (such as staging environments accessible to Googlebot or unverified properties), run the URL through the Rich Results Test. In addition to validating structured data syntax, this tool uses the same headless Chromium infrastructure and provides access to the rendered HTML and resource loading logs.
When reviewing the More Info tab in either tool, distinguish between benign omissions and rendering blockers. Blocked tracking pixels or ad scripts rarely affect DOM construction, whereas a blocked internal API request or core JavaScript bundle labeled as disallowed by
robots.txt
or failed due to a timeout directly explains missing content in the rendered HTML tab.
Step 4: Audit raw versus rendered HTML at scale
Testing individual URLs in Search Console cannot catch template-Specific regressions or intermittent rendering failures across thousands of pages. To audit at scale, configure a desktop SEO crawler-such as Screaming Frog SEO Spider or Sitebulb-to crawl using its headless Chromium rendering mode alongside raw HTML capture.
When configuring the crawler, set the user-agent to Googlebot Smartphone, enable the option to store both raw HTML and rendered HTML, and adjust the rendering wait timer or network idle settings so asynchronous XHR requests have time to resolve. After the crawl finishes, compare the raw and rendered datasets across page templates to isolate four specific patterns:
| Audit Comparison Metric | Diagnostic Signal in Crawl Data | Underlying Technical Issue |
|---|---|---|
| Word count and body text | High word count in rendered HTML, near-zero in raw HTML on pages expected to use SSR. | Server-side rendering is failing or falling back to client-side rendering for specific routes or user agents. |
| Internal outlinks | Links discovered only in the rendered phase, or zero crawlable outlinks in both phases. |
Navigation relies on client-side injection, or UI components use non-standard link elements without
<a href>
attributes.
|
| Indexation directives | Canonical URL or meta robots status changes between the raw response and rendered DOM. | Client-side routing scripts or tag managers are overwriting server-delivered directives during hydration. |
| HTTP status vs. page content |
HTTP 200 status code combined with a rendered
<title>
or H1 containing "Page Not Found" or empty product grids.
|
Unresolved client-side routes or failed API responses are generating soft 404s without updating the status code or injecting a
noindex
tag.
|
If the crawler reports intermittent missing content on valid URLs when crawling in JavaScript mode, inspect the crawl logs for rendering timeouts. High concurrency from a desktop crawler running multiple headless browser instances can overwhelm origin servers or rate-limited APIs, causing scripts to time out and produce incomplete DOM snapshots that mimic rendering failures.