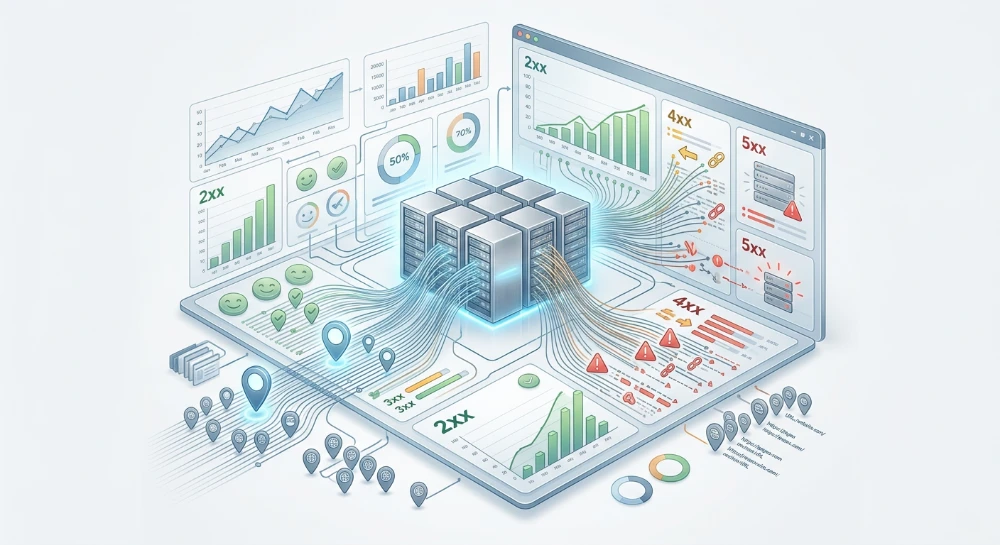
A soft 404 error occurs when a web server tells a browser or crawler that a page loaded successfully by returning a standard 200 OK HTTP status code, but the actual content of the page indicates otherwise. To a search engine evaluating the URL, the page appears to be missing, completely empty, or functionally dead.
This classification happens because search engines do not rely solely on server headers to determine a page's validity. If Googlebot crawls a URL and encounters a "page not found" text message, a zero-result site search page, or a rendering failure that leaves the primary content blank, it overrides the server's 200 OK response. The crawler relies on the rendered content to understand the true state of the URL.
Because search engines interpret these pages as missing, they treat a soft 404 exactly like a standard 404 Not Found or 410 Gone HTTP status. The immediate consequence is that the affected pages are dropped from the index, disqualifying them from appearing in search results even though the server claims they are active and healthy.
Why pages trigger a soft 404 classification
Search engines override a 200 OK HTTP status when the rendered page content closely resembles a dead or missing URL. This classification acts as a safeguard against indexing empty, broken, or fundamentally irrelevant pages. The override typically happens under four specific conditions.
Empty On-Site search results
Internal search engines and faceted navigation systems generate URLs dynamically based on user input. When a specific search query or filter combination yields zero results, the server often still returns a 200 OK status code along with the site's standard template. Search engine crawlers parse the page, detect common phrases like "no results found" or identify a completely empty item grid, and classify the URL as a soft 404 to avoid indexing blank destination pages.
Extremely thin or Template-Only content
A URL can trigger a soft 404 if the primary content area is missing, leaving only boilerplate elements such as the header, footer, and sidebars. This frequently occurs due to database query errors or CMS misconfigurations where a page template loads successfully, but the unique text, article body, or product data fails to populate. Without sufficient unique content to evaluate, the crawler concludes the page is functionally empty.
Client-Side JavaScript rendering failures
Websites relying heavily on client-side JavaScript for core content delivery risk soft 404 classifications if the rendering process fails during a crawl. Search engine bots operate with strict resource constraints. If a required script is blocked by robots.txt, an external API call times out, or the crawler encounters an execution error, the bot is left looking at the initial HTML skeleton. Even if the page loads perfectly for human visitors in a standard web browser, the crawler's inability to render the primary content forces it to interpret the page as blank.
Irrelevant redirects for deleted pages
A soft 404 classification also occurs when a deleted URL is redirected to a structurally unrelated destination, most commonly the root homepage. When webmasters implement 301 redirects for expired content instead of serving a standard 404 or 410 HTTP status, search engines evaluate the contextual relevance between the source URL and the destination. If the destination page does not serve as a direct equivalent to the missing content, the search engine treats the redirect as a soft 404. This mechanism prevents irrelevant pages from inheriting conflicting signals from unrelated deleted URLs.
Run a deep technical crawl to identify 4xx errors, missing meta tags, and indexation blockers.
How soft 404s affect indexation and crawling
When a search engine classifies a URL as a soft 404, the immediate operational impact is removal from the index. Because the crawler determines the content is functionally missing or empty, it processes the URL as if the server had returned a standard 404 Not Found or 410 Gone HTTP status code. The affected page is dropped from the index and becomes ineligible to appear in search results.
If a website triggers only a few soft 404 classifications, the effect remains localized. The search engine deindexes those specific URLs, while the rest of the site's valid content continues to be crawled and indexed normally. Small numbers of these classifications are common and rarely indicate a broader structural issue.
Impact on crawl efficiency at scale
The operational consequences change when a website generates soft 404s at scale. Search engine bots operate with finite resource limits for querying, downloading, and rendering web pages. When a server returns a legitimate 404 or 410 status code for a missing page, the crawler recognizes the signal at the HTTP header level and can abandon the request early.
In contrast, a soft 404 begins with a 200 OK response. This forces the crawler to process the full URL sequence: it must download the HTML, execute any required client-side rendering, and parse the resulting document object model before it can finally conclude that the page is practically empty. When a faulty routing system, unconstrained faceted navigation, or broken template generates thousands of these false 200 OK responses, the search engine must spend time evaluating low-value URLs.
For large websites, forcing crawlers to repeatedly process high volumes of dead or empty pages negatively affects crawl efficiency. Diverting crawler activity to evaluate tens of thousands of soft 404s can delay the discovery of newly published content or slow down the recrawling of priority pages that have been recently updated.
Diagnosing soft 404s in Google search console
The primary interface for identifying these errors is the Page Indexing report in Google Search Console. When Googlebot processes a URL returning a 200 OK HTTP status code but evaluates the content as missing, invalid, or empty, it groups the affected pages under the "Submitted URL seems to be a Soft 404" status. Reviewing the examples listed under this status often reveals URL patterns or specific site sections where database queries are failing or routing rules are improperly configured.
Comparing rendered HTML to raw source code
Once a pattern is identified in the Page Indexing report, the URL Inspection tool helps pinpoint the exact rendering behavior triggering the classification. Entering an affected URL and running a live test provides a snapshot of the page as Google's rendering service evaluates it. The critical diagnostic step is using the View Tested Page feature to extract and compare the rendered HTML against the raw source code initially delivered by the server.
This comparison isolates client-side rendering failures. If the raw source code contains the necessary script references and data objects, but the rendered HTML is missing the core content, a JavaScript execution issue or timeout is likely preventing the crawler from accessing the page content. Because the crawler's rendering environment cannot successfully paint the page, it sees a nearly empty container. This results in a soft 404 classification despite the initial 200 OK server response.
Conversely, if both the raw source and rendered HTML lack the expected primary content, the issue typically bypasses the rendering phase entirely. In these cases, the diagnostic focus shifts to server-side template errors, empty database responses, or intentionally thin pages that fail to provide enough unique text for search engines to process as valid content.
Proactive identification with Third-Party crawlers
Google Search Console highlights URLs that have already triggered a soft 404 classification during an active crawl. Third-party website crawling tools can help detect these conditions proactively, before search engines process the pages and alter their indexation status.
Technical teams can configure these tools to isolate thin pages returning a 200 OK status code by setting custom extraction or evaluation rules. A crawler can be set to flag any 200 OK page that possesses an extremely low word count, features an empty primary content container, or contains specific text strings commonly associated with empty search result pages or missing inventory. This allows for the identification and correction of functionally dead pages at scale without waiting for Googlebot to encounter the issue.
SEO structure and reciprocal link analyzer
Detect orphan pages, deep click depths, and toxic reciprocal links built by careless agencies.
Correcting server responses and resolving soft 404s
The correct resolution for a soft 404 depends entirely on the intended function and lifecycle stage of the URL. The objective is to align the server's HTTP response code and on-page indexation directives with the actual state of the content.
Handling permanently deleted content
If a page represents a discontinued product, a removed article, or a URL that never should have existed, a 200 OK status is invalid. The server must be configured to return an accurate error code.
- 404 Not Found: The standard response for missing content. Search engines will gradually drop URLs returning a 404 from their index.
- 410 Gone: A more explicit signal indicating the content was permanently removed and will not return. Search engines often process 410 status codes faster than 404s, which can accelerate the deindexation of dead URLs.
Implementing 301 redirects
When content has moved or a direct replacement exists, a 301 Moved Permanently redirect consolidates indexing signals to the new URL. However, this implementation requires strict relevance between the source and the destination.
Routing deleted URLs to structurally irrelevant destinations, such as the site's homepage or a broad top-level category, is a common misconfiguration. Search engines evaluate the destination payload. If the new page does not functionally replace the intent of the original URL, the search engine may ignore the redirect entirely or continue treating the redirect sequence as a soft 404.
Managing intentionally thin dynamic pages
Web architectures frequently generate URLs that are intentionally thin or dynamically empty. Examples include highly specific multi-select filter states in faceted navigation, session-specific sorting parameters, or category pages temporarily devoid of inventory.
Because these pages return a 200 OK by design but lack substantial unique content, they are highly susceptible to soft 404 classification. The standard resolution is to apply a
noindex
directive, either via a robots meta tag in the HTML head or an X-Robots-Tag HTTP header. This instructs crawlers to keep the URL out of the index, preventing the soft 404 classification while preserving the page's availability and function for human users.
Rescuing valid pages flagged incorrectly
When a structurally valid, intended-for-indexation page is flagged as a soft 404, the search engine has failed to parse an adequate content payload. Resolution requires diagnosing the disconnect between the page design and the crawler's perception.
If the raw HTML and rendered DOM genuinely lack sufficient text, the page requires content optimization. This involves expanding the primary content container with unique, descriptive text that distinguishes the specific URL from the site's standard boilerplate. Navigation menus, sidebars, and footers do not satisfy the primary content requirement.
If the content exists in the browser but relies on client-side JavaScript that the crawler fails to process, the rendering pipeline must be fixed. Corrective actions include:
- Implementing server-side rendering (SSR) or dynamic rendering to ensure the core content is immediately present in the initial HTML response.
- Removing network blocks on APIs required for client-side rendering.
- Optimizing script execution to ensure the DOM populates before the crawler's rendering environment times out.