Crawl budget is the intersection between a search engine's crawl capacity limit and its crawl demand for a specific website. While crawling is the foundational step for any page to be discovered and indexed, search engines must balance their own processing resources against the technical capabilities of the host server. They determine how many requests a server can handle without degrading the user experience, while simultaneously evaluating which URLs are actually worth prioritizing based on popularity, site structure, and content freshness.
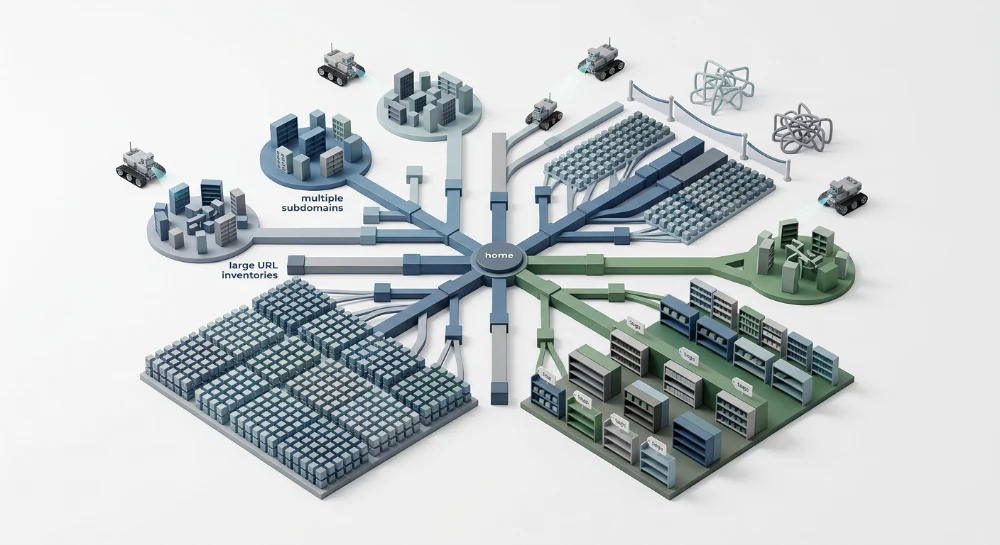
Because modern crawlers are highly efficient, active crawl budget management is not a practical concern for the vast majority of small to medium-sized websites. The concept generally only matters when a site reaches a scale or architectural complexity that strains standard crawl allowances. Enterprise websites with millions of URLs, extensive eCommerce catalogs utilizing faceted navigation, and rapidly updating news portals are the primary environments where crawl efficiency requires direct technical intervention.
If left unmanaged on these larger domains, architectural inefficiencies can force search engines to waste their allotted capacity on low-value URLs. When crawlers spend time navigating infinite parameter spaces, deep redirect chains, or large volumes of thin duplicate content, this inefficiency dilutes crawl demand. Consequently, the discovery of high-priority pages is delayed, extending the time it takes for new or updated content to be processed and evaluated for search results.
The two components of crawl budget: Capacity and demand
Search engines do not assign a fixed daily quota of URLs to process for a given domain. Instead, the volume of pages fetched during any specific timeframe is a dynamic calculation derived from two distinct variables: the crawl capacity limit and crawl demand. The final crawl rate fluctuates continuously as search engines evaluate these two factors.
Crawl capacity limit
The crawl capacity limit represents the maximum number of simultaneous connections a search engine crawler can make to a server, along with the time delay between individual fetches. The primary technical objective of this limit is to process as much information as possible without degrading the performance of the host server for actual human visitors.
This limit is directly tied to server performance and hostload. When a server responds quickly to requests, search engines interpret this efficiency as an indication that the host can handle more concurrent connections, which can raise the capacity limit. If the server response time slows down, or if the crawler encounters HTTP 5xx (Server Error) or HTTP 429 (Too Many Requests) status codes, the search engine automatically throttles its request rate to protect the host architecture.
Crawl demand
Even if a server possesses exceptional performance capabilities, search engines will only allocate resources to crawl a site if there is a recognizable need to evaluate its content. Crawl demand determines how much of the available server capacity a search engine actually utilizes.
Demand is driven primarily by URL popularity, internal link structure, and content freshness. Search algorithms prioritize URLs that receive frequent interaction or are prominently integrated into the site architecture through internal linking. Freshness also dictates scheduling; a crawler models return visits based on historical update patterns. A dynamic inventory page or a frequently updated index will generate substantially higher crawl demand than a static informational page.
The operational crawl rate of a website is the lower of these two components at any given moment. High demand cannot overcome a low capacity limit, which results in delayed discovery of new URLs as the crawler holds back to protect the server. Conversely, an over-provisioned server with high capacity will not see a high volume of crawler traffic if the site lacks the popularity and freshness signals necessary to generate crawl demand.
Run a deep technical crawl to identify 4xx errors, missing meta tags, and indexation blockers.
Which websites actually need to manage crawl budget?
For the vast majority of websites, crawl budget is not an operational concern. A standard corporate site, an informational blog, or a small-to-medium business domain with hundreds or even tens of thousands of URLs rarely reaches a threshold where search engines cannot process its pages. In these standard environments, discovery algorithms can easily evaluate the site without exhausting server capacity or falling behind on new content.
Active crawl budget management becomes necessary when the mathematical scale of a website, the frequency of its updates, or sudden architectural shifts outpace standard crawling behavior. The threshold for practical concern typically aligns with specific architectural patterns.
Large-Scale websites
Sites operating at massive scale-such as extensive directories, programmatic aggregators, or major user-generated content platforms-frequently manage millions of distinct URLs. At this volume, a search engine cannot crawl the entire site continuously. Without active guidance, crawlers may spend excessive time evaluating low-value or legacy pages while missing deep, high-priority URLs that drive value.
Ecommerce and faceted navigation
Online retailers often require crawl management not just because of product count, but due to URL geometry. eCommerce platforms rely on faceted navigation, allowing users to filter categories by attributes such as size, color, brand, or price. Each filter combination often generates a unique URL variation. Consequently, a site with a baseline of 10,000 products can easily generate hundreds of thousands of parameter URLs. Without strict management, crawlers will attempt to process every filter permutation, utilizing available capacity on near-duplicate category pages instead of discovering new product inventory.
News portals and publishers
For news organizations and publishers covering live events, the primary crawling constraint is time rather than sheer volume. These platforms depend on search engines discovering and indexing articles within minutes of publication. Crawl management for high-velocity sites focuses on directing crawler attention heavily toward fresh content hubs and XML sitemaps, ensuring that capacity is spent on breaking news rather than continuously re-evaluating static historical archives.
Site migrations and architecture overhauls
Crawl efficiency becomes temporarily important for sites of almost any size during major structural changes. When executing a domain migration, a comprehensive URL restructure, or a massive consolidation of content, search engines must process a sudden influx of redirect directives or entirely new URL paths. Optimizing the site for crawl efficiency before and during a migration ensures the search engine can process the new architecture as rapidly as possible, minimizing the time required to update the index.
Common sources of crawl waste
Crawl waste occurs when a search engine expends its allocated capacity requesting URLs that offer no indexable value. When a site presents a large volume of low-quality, redundant, or broken URLs, it dilutes the overall crawl demand for the domain. The search engine exhausts time and resources processing these low-priority requests, which delays the discovery of newly published pages and updates to priority content.
URL parameters and session identifiers
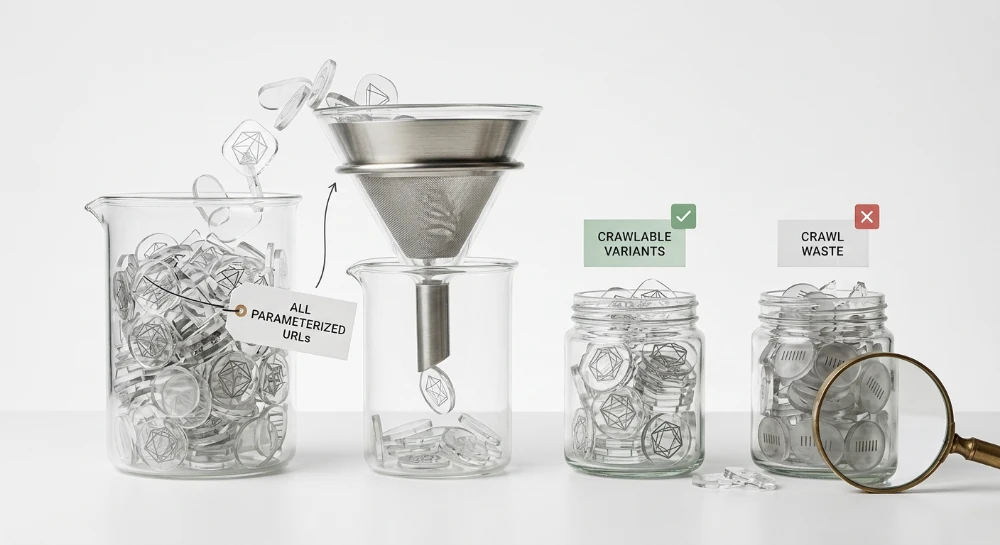
Unrestricted URL parameters are a primary cause of crawl inefficiency. Web applications often append tracking variables, session IDs, sorting directives, or display modifiers directly into the URL string. If internal links or user-generated pathways expose these variations to search engine bots, the crawler treats each unique string as a distinct page.
Because these parameters typically alter the presentation rather than the core content, they create a structurally infinite URL space consisting of exact duplicates. The crawler spends capacity repeatedly downloading the same content under different parameter variations, which dilutes the demand signals that should be concentrated on a single canonical URL.
Crawler traps
A crawler trap is an architectural flaw that generates a structurally infinite path of links, keeping the bot trapped in a specific section of the site. Common triggers include:
- Improperly configured calendar widgets that generate internal links to endless future and past months, regardless of whether events exist.
- Broken relative links that recursively append directories to a URL path, generating infinite chains such as /category/category/category/.
- Dynamic mapping interfaces that create unique URLs for every microscopic change in map coordinates.
These traps consume massive amounts of capacity because the bot continuously discovers what appear to be new, valid internal links, preventing it from allocating time to the rest of the site architecture.
Deep redirect chains
Every step in a redirect chain requires a separate HTTP request. If an outdated URL redirects through three intermediate URLs before resolving at the final destination, the search engine must expend four distinct crawl requests to process one piece of content. When mapped across thousands of URLs, redirect chains rapidly exhaust crawl capacity. In severe cases, the search engine may abandon the redirect path entirely before reaching the final 200 OK status code, leaving the priority page undiscovered.
Thin duplicates and Near-Duplicates
Presenting identical or highly similar content on multiple distinct URLs forces search engines to crawl all variations before algorithmically grouping them. Common sources of thin duplicates include:
- Inconsistent URL structures, such as trailing slash versus non-trailing slash URLs.
- Auto-generated tag pages or empty category hubs that lack unique primary content.
- Internal search result pages exposed to crawlers.
- Localized page variations that fail to provide unique regional content.
Consistently crawling these pages degrades the perceived average URL quality of the domain, which can eventually lower the overarching crawl demand for the site.
Soft 404 errors
A soft 404 occurs when a server returns a 200 OK HTTP status code for a URL that does not actually exist, is entirely empty, or displays a generic "page not found" message. Because the server explicitly claims the page is valid and successful, the crawler expends capacity downloading and parsing the HTML payload. It is only after rendering and evaluating the content that the search engine identifies the page as empty. A high volume of soft 404s forces the search engine to continually re-crawl dead URLs to verify their status, wasting capacity that should be directed toward active pages.
SEO structure and reciprocal link analyzer
Detect orphan pages, deep click depths, and toxic reciprocal links built by careless agencies.
Identifying signs of crawl inefficiency
The primary diagnostic tool for evaluating how search engines interact with a website is the Crawl Stats report in Google Search Console. This report aggregates historical request data, providing visibility into technical bottlenecks that may restrict crawl capacity.
Evaluating host status and performance metrics
The Host Status section of the report indicates whether the crawler encountered difficulties connecting to the server, resolving the DNS, or fetching the robots.txt file. Consistent failures in these areas prevent search engines from accessing the site, directly reducing the assigned crawl capacity.
Alongside availability, two performance metrics dictate how efficiently a search engine can process the site:
- Average response time: Search engines monitor how quickly a server responds to requests. If server response times increase, the crawler scales back its request rate to avoid degrading the experience for human users. A rising average response time often correlates directly with a drop in the total number of URLs crawled.
- Total download size: Large HTML payloads consume more capacity per URL. Monitoring average download size can highlight inefficient page templates, bloated inline scripts, or unexpectedly large DOM structures that slow down the parsing phase.
Monitoring status code spikes
The Crawl Stats report categorizes requests by HTTP response, making it possible to identify when the server is struggling to handle the crawl demand. Spikes in specific error codes are strong indicators that the server's hostload has been exceeded.
An HTTP 429 (Too Many Requests) status code occurs when the server, a rate-limiting firewall, or a content delivery network explicitly rejects the crawler for exceeding configured request limits. Frequent 429 errors signal a hard cap on crawl capacity, forcing the search engine to abandon the current request queue.
Similarly, a high volume of 5xx HTTP status codes, such as 500 Internal Server Error or 503 Service Unavailable, indicates that the server is overloaded or timing out. When a search engine encounters a cluster of 5xx errors, it assumes the server is under strain and will rapidly decrease its crawl rate to protect the infrastructure.
Analyzing server logs for granular activity patterns
While Google Search Console provides useful aggregates and samples, it does not display every URL requested. Server log files offer a complete, unfiltered record of every request made to the host. Log file analysis is necessary to verify exact crawler activity patterns at the server level.
By extracting requests containing search engine user agents and verifying the requesting IP addresses, practitioners can audit exactly how crawl capacity is distributed across the site architecture. Key patterns to evaluate in server logs include:
- The crawl frequency of high-priority URLs compared to legacy pages or low-value content.
- The specific timestamps of 5xx or 429 errors, which can be correlated with server events like database backups, product catalog imports, or cache purges.
- Crawler activity in unfiltered URL parameter spaces or staging environments that may not be fully surfaced in standard analytics or reporting tools due to sampling.
Correlating the sampled data from Search Console with the raw request data in the server logs confirms whether the search engine is successfully discovering priority content or wasting capacity on inefficient paths.
Core mechanisms for controlling crawler behavior
When diagnostic data confirms that a search engine is allocating capacity to low-value URL spaces or redundant requests, practitioners can implement specific directives and server responses to modify crawler scheduling and access.
Restricting access with robots.txt
The
robots.txt
file is the most direct method for preventing search engines from accessing specific sections of a website. By using the
Disallow
directive, site owners instruct compliant crawlers to skip specified URL paths entirely. Because the search engine drops these URLs before making an HTTP request, the associated server capacity is preserved for other pages.
This mechanism is highly effective for blocking vast spaces of structurally generated URLs that offer no search value, such as internal search result pages, unfiltered faceted navigation combinations, and user-specific session directories. It is important to distinguish the
Disallow
directive from the
noindex
meta tag. A
noindex
tag requires the search engine to request and render the page to read the instruction, which still consumes crawl capacity. When the goal is strictly to optimize hostload and crawling efficiency,
Disallow
is the appropriate tool.
Optimizing refresh crawls via HTTP caching
Search engines continuously revisit known URLs to check for content updates, a process known as refresh crawling. If a page has not changed since the last visit, serving the full HTML document wastes bandwidth and processing time. Configuring the server to support HTTP caching correctly optimizes this process.
When a crawler requests a previously discovered URL, it often includes an
If-Modified-Since
or
If-None-Match
HTTP header containing the timestamp or entity tag (ETag) of its last crawl. If the server verifies that the content remains identical, it can return a
304 Not Modified
HTTP status code with an empty response body. This confirms that the search engine's current indexed version is still accurate, allowing the crawler to update its internal freshness records without downloading the full page payload.
Removing dead URLs with 404 and 410 status codes
Properly handling deleted, expired, or permanently moved content prevents crawlers from wasting time repeatedly trying to access invalid paths. When a page is no longer available and has no relevant replacement, the server must return an accurate error code rather than a 200 OK status.
- 404 Not Found: Indicates that the resource is missing. Search engines will eventually drop 404 URLs from the index, but they typically retain them in the crawl queue for a period, retrying them occasionally to confirm the page is genuinely gone and not experiencing a temporary outage.
- 410 Gone: Provides a stronger, more explicit signal that the removal is permanent and intentional. Search engines typically process a 410 status code faster than a 404, accelerating the URL's removal from the active crawl queue.
Implementing a 410 status code is particularly useful during large-scale inventory purges or site migrations where thousands of URLs are deliberately deprecated at once.
Guiding discovery with XML sitemaps and lastmod tags
While XML sitemaps do not force a search engine to crawl a URL, they serve as a heavily weighted suggestion for URL discovery and prioritization. For sitemaps to positively influence crawl efficiency, they must contain only canonical URLs that return a 200 OK status code. Including redirected, dead, or disallowed URLs dilutes the sitemap's utility as a high-priority queue.
The `
The `