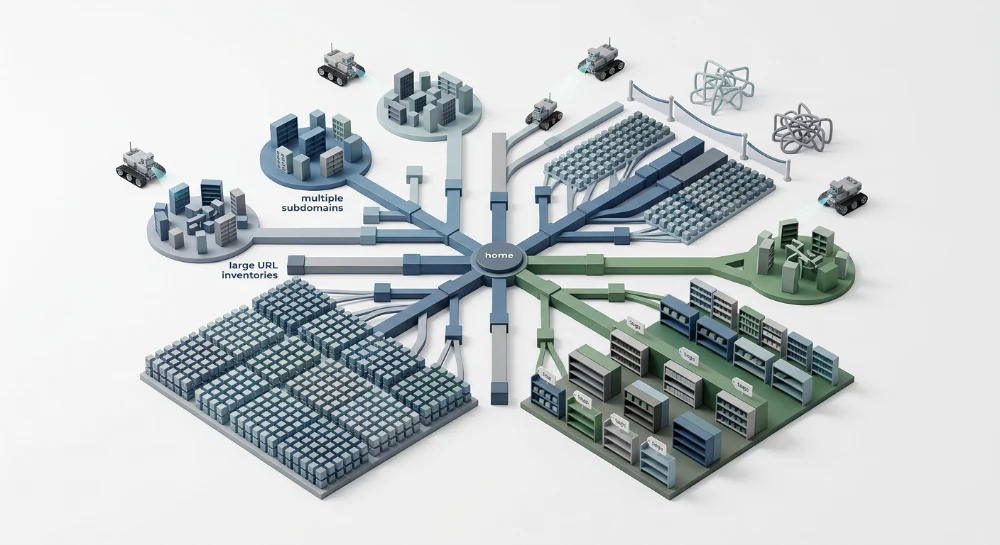
Managing the crawl budget for enterprise websites involves directing search engine bots efficiently across complex architectures. For large-scale sites with millions of URLs, multiple subdomains, or rapidly changing faceted catalogs, relying on default crawler behavior is rarely sufficient. At this scale, active crawl management is practically required to ensure that new and updated business-critical content is discovered and indexed without unnecessary delays.
Understanding crawl budget requires a clear distinction between two primary mechanisms: the crawl rate limit and crawl demand. The crawl rate limit is a technical constraint based on server capacity and responsiveness. Search engines intentionally restrict how many simultaneous connections they make to avoid overloading a server, meaning slow response times or frequent HTTP error codes can directly lower this limit. Crawl demand, conversely, is driven by search engine interest, which fluctuates based on URL popularity, perceived content value, and the freshness of the page.
When enterprise sites fail to align server performance with indexation goals, crawling becomes inefficient. If search engine bots are caught processing infinite catalog filters or waiting on slow server responses, they waste their allocated crawl capacity on low-value URLs. Actively mitigating these bottlenecks focuses crawl demand on the content that matters most, allowing search engines to process new products and essential site updates promptly.
Diagnosing crawl waste and server constraints
Effective crawl management starts with measuring how search engines interact with the server infrastructure. This requires two complementary data sources: server log analysis and the Google Search Console Crawl Stats report. While the Crawl Stats report provides a high-level summary of crawler interaction with the host, raw server logs offer the granular, URL-by-URL data necessary to identify exactly where crawl capacity is being spent.
Evaluating host status and crawl rate limits
Search engines actively monitor server health to avoid overwhelming host infrastructure. If a server appears to struggle under load, search engines will proactively lower the crawl rate limit. Monitoring the Host status within the Crawl Stats report helps identify when server performance is actively restricting indexation.
Three primary metrics dictate this server-side throttling:
- 5xx HTTP Status Codes: Frequent server errors indicate the infrastructure is failing to process requests, prompting crawlers to immediately back off to prevent causing an outage.
- 429 Too Many Requests: Returning a 429 status code acts as an explicit signal for bots to reduce their crawl rate.
- High Time-to-First Byte (TTFB): Search engines limit the number of simultaneous connections they open to a server. A consistently high TTFB means each page request occupies a connection for a longer duration, which directly reduces the total number of URLs that can be processed within the allotted crawl capacity.
Identifying crawl waste through log analysis
Server log analysis bridges the gap between server performance and crawl efficiency. By filtering server logs for search engine user agents, administrators can identify specific URL patterns that consume disproportionate crawl capacity.
Analyzing access logs reveals whether search engine bots are crawling efficiently or getting trapped. Common indicators of crawl waste include thousands of requests directed at non-indexable faceted navigation, infinite calendar loops, or expired campaign parameters. When crawlers expend their limited daily connections on these low-value URLs, they lack the remaining capacity to process business-critical pages, leading to indexation delays.
Interpreting 'discovered - currently not indexed'
The Page Indexing report in Google Search Console provides a critical diagnostic signal through the 'Discovered - currently not indexed' status. This classification means the search engine has found the URL, typically via an XML sitemap or internal link, but chose not to crawl it at that time. Resolving this requires determining whether the site has hit a server-capacity limit or if the URLs are suffering from low crawl priority.
Comparing this report against server log data helps diagnose the root cause. If logs reveal that bots are actively crawling thousands of low-value filter permutations while new product URLs remain in the 'Discovered' state, the site has likely reached its crawl rate limit due to structural inefficiency. The crawl capacity is exhausted before bots reach the targeted content.
Conversely, if host servers are responding quickly, server logs show minimal crawl waste, and the URLs still remain uncrawled, the issue is typically low crawl priority. In this scenario, the search engine algorithm has evaluated the URL pattern or linking structure and deemed the content as lacking sufficient value or importance to warrant immediate crawling.
Run a deep technical crawl to identify 4xx errors, missing meta tags, and indexation blockers.
Controlling faceted navigation and parameter traps
Large e-commerce and catalog sites rely on faceted navigation to organize inventory, but these systems routinely generate millions of URL permutations through filters, sorting options, and tracking parameters. When search engines discover every mathematical combination of category, color, size, price range, and sort order, they enter a parameter trap. This functionally infinite space of duplicate or low-value URLs quickly exhausts available crawl capacity.
Access control versus index control
Mitigating this scale of crawl waste requires a strict technical distinction between index control and access control. Implementations often mistakenly rely on index control mechanisms to manage crawl efficiency, which fails to solve the underlying resource constraint.
Index control utilizes HTML tags or HTTP headers, specifically the canonical link element and the noindex directive. These signals dictate how a search engine should consolidate or exclude a URL within its index. However, to read a canonical tag or a noindex instruction, the crawler must first initiate the HTTP request, wait for the server response, and parse the payload. Every URL processed this way consumes a unit of crawl capacity. While canonicals and noindex directives effectively prevent index bloat, they require crawling to function and therefore do not directly save crawl budget.
Access control operates before the HTTP request occurs. By utilizing the robots.txt file, server administrators can issue Disallow directives that instruct compliant crawlers to skip specific URL patterns entirely. Because the crawler aborts the request before contacting the server, the connection is preserved. This remains the primary mechanism for conserving enterprise crawl capacity, ensuring search engine bots retain the resources necessary to process priority pages.
Strategies for parameter management
Implementing effective access control for faceted navigation involves auditing all URL parameters and categorizing them by their utility to search discovery. Once identified, non-essential parameters can be restricted using pattern matching in the robots.txt file.
- Session IDs and Tracking: Parameters used strictly for analytics, user session tracking, or affiliate attribution generate unique URLs for identical content. Because the content payload does not change, these tracking variables should be disallowed.
- Sorting and Display Options: Parameters that change presentation without altering the core item set-such as sorting by price, altering the item count per page, or switching between grid and list views-should be blocked from crawling.
- Multi-Facet Combinations: While single-filter URLs often align with specific long-tail search behavior, combinations of three or more filters rarely do. A highly scalable approach is to configure the application logic so that complex multi-filter selections append a specific parameter or path footprint that is explicitly disallowed in robots.txt. This caps the crawlable depth of the facet tree while keeping broad categories accessible.
Standardizing parameter order
Crawl waste multiplies when internal linking or backend systems generate the same parameters in different sequences. If a site renders links to both
?color=red&size=large
and
?size=large&color=red
, search engines will process them as distinct endpoints. Enforcing a strict, alphabetical parameter order within the application code ensures that internal links consistently point to a single URL string, preventing the crawler from discovering redundant permutations.
Optimizing server performance and HTTP caching
Search engine crawlers operate within defined resource constraints per host, making server responsiveness a primary factor in determining the theoretical maximum Crawl Rate Limit. The speed at which a server processes a request and returns the initial response directly dictates how many URLs can be fetched during a crawl session.
Minimizing Time-to-First byte
Time-to-First Byte measures the duration from the client making an HTTP request to the server sending the first byte of data. When TTFB is high, crawler connections remain open longer, reducing the total volume of requests the crawler can execute. If search engines detect server strain, such as elevated connection timeouts or persistent 5xx status codes, they will proactively lower the crawl rate to avoid degrading the experience for human visitors.
To maximize crawl capacity, infrastructure configurations should prioritize low-latency HTML delivery through the following practices:
- Edge Delivery: Serve cacheable HTML from a Content Delivery Network to reduce geographic latency and offload traffic from the origin server.
- Object and Database Caching: Utilize in-memory data stores to cache complex database queries, reducing the backend processing time required to assemble dynamic category or product pages.
- Connection Reuse: Ensure HTTP Keep-Alive is enabled, allowing crawlers to use a single TCP connection for multiple requests rather than negotiating a new handshake for every URL.
Leveraging HTTP caching and 304 not modified
A significant portion of crawl demand is spent verifying whether known pages have changed. Without proper HTTP caching headers, the server must regenerate and transmit the entire HTML document for every crawler request, even if the content remains identical to the previous visit.
Configuring the server to process validation headers allows search engines to check for freshness efficiently. When a crawler requests a URL, it can include the If-Modified-Since header containing the timestamp of its last crawl, or the If-None-Match header containing a unique entity tag for the file. The server evaluates these headers against the current version of the content.
If the content has not changed, the server returns a 304 Not Modified HTTP status code. A 304 response consists only of HTTP headers and omits the body payload entirely. This mechanism provides two major crawl efficiency benefits:
- Bandwidth Conservation: By eliminating the transmission of the full HTML payload, server bandwidth is preserved for serving new and updated pages.
- Processing Speed: Search engine bots can parse a header-only response in a fraction of the time required to download and render a full document, allowing them to iterate through a list of known URLs much faster.
Protecting server capacity
Enterprise infrastructure must also be protected from non-essential bot traffic that competes with primary search engines for server resources. Aggressive scraping tools, unverified crawlers, and automated site auditors can saturate connection limits and artificially inflate backend processing queues. Implementing a Web Application Firewall to enforce rate limits on secondary bots ensures that computing resources remain available for primary search engine user agents, preventing artificial crawl bottlenecks.
Bulk Google and Yandex index checker
Verify agency reports and track live SERP status in Google and Yandex to protect your SEO ROI.
Directing crawl demand with scalable XML sitemaps
While server management establishes the maximum capacity for crawling, XML sitemaps provide the mechanism to direct search engine crawl demand toward specific URLs. For enterprise domains, an optimized sitemap architecture focuses bot activity on business-critical pages, newly published content, and recently updated inventory, preventing search engines from wasting resources on static or low-priority sections of the site.
Structuring sitemaps for Large-Scale architectures
A standard XML sitemap can contain a maximum of 50,000 URLs and must not exceed 50 megabytes uncompressed. Enterprise domains with millions of URLs must deploy a sitemap index file to aggregate multiple child sitemaps. Instead of grouping URLs arbitrarily or strictly by numerical pagination, structuring child sitemaps logically by page template, category, subfolder, or geographic market provides operational value. This segmentation isolates indexation patterns in search engine reporting tools, making it easier to identify specific page types that suffer from low crawl demand.
For organizations operating across multiple subdomains, sitemap management requires centralized coordination. A single sitemap index file hosted on the root domain can reference child sitemaps located on various subdomains, provided all subdomains are verified under the same domain property in the search engine webmaster tool. This cross-submission capability allows engineering teams to maintain a unified crawl instruction set without duplicating index files across disparate server environments.
Validating the lastmod attribute
The primary signal used to prioritize crawl demand within an XML sitemap is the lastmod attribute. This timestamp communicates the exact date and time the content at a specific URL was last modified. When implemented correctly, it allows search engine algorithms to compare the declared modification date against their internal crawl records, skipping known static pages in favor of newly modified content.
The efficiency gained from the lastmod attribute depends entirely on the accuracy of the timestamp. Search engines continuously evaluate the reliability of sitemap modification dates by comparing them against the actual changes detected in the HTML payload during a crawl. If the timestamps do not reliably correspond to actual content updates, search engines can begin ignoring the lastmod signal entirely for that domain.
To preserve trust in this signal and maintain efficient crawl prioritization, the lastmod attribute must be configured with strict constraints:
- Trigger updates only for meaningful changes to the primary content, such as a product description update, price change, or new main text.
- Do not update timestamps for global template changes, dynamic ad rotation, or minor navigational menu adjustments.
- Avoid automated systems that universally rewrite the lastmod date for all URLs during a daily database sync or static site generation build unless the underlying content genuinely changed.
When the lastmod timestamp consistently matches actual content modification, search engines can allocate crawl demand with high precision, ensuring that inventory changes and editorial updates are discovered rapidly even within catalogs spanning millions of URLs.
Crawl efficiency in complex rendering architectures
Client-side rendering using JavaScript frameworks introduces a multi-step process for search engine crawlers. When an architecture relies on the browser to assemble the page, the initial HTTP response often contains little more than an empty container element and links to JavaScript files. To discover the actual content, search engines must download the initial HTML, place the required scripts and API endpoints into a fetch queue, and eventually execute the code within a headless browser environment.
This rendering phase requires significantly more computational resources and time per URL than parsing static HTML. For an enterprise site managing hundreds of thousands or millions of pages, client-side rendering can severely reduce the total number of pages processed per day. The delay between the initial HTML fetch and the final rendering execution can also create a gap where new products, price changes, or editorial updates are delayed in reaching the index.
Server-Side rendering for High-Volume discovery
To maintain high crawl throughput, large-scale catalogs typically require Server-Side Rendering (SSR) or Static Site Generation (SSG). With SSR, the server executes the application logic and delivers a fully populated HTML document directly to the client or crawler.
Because the primary text, structured data, and internal links are immediately present in the initial HTTP response, search engines can extract links and process content without waiting for a secondary rendering pass. SSR is generally necessary under the following conditions:
- The site features a rapidly changing e-commerce inventory where delayed discovery results in outdated pricing or out-of-stock listings appearing in search results.
- The domain relies on deep pagination or complex internal linking structures that crawlers must traverse quickly.
- The application requires multiple cascading API calls to render primary content, increasing the risk of rendering timeouts in crawler environments.
Evaluating dynamic rendering
In environments where a legacy client-side application cannot be immediately refactored to support SSR, dynamic rendering offers a mechanism to restore crawl efficiency. This configuration detects search engine user agents at the server or CDN level and routes their requests to a pre-rendering service. The pre-renderer executes the JavaScript and returns static HTML to the crawler, while standard users continue to receive the client-side application.
While dynamic rendering can bypass the crawler rendering queue, it introduces specific infrastructure risks that must be monitored. If the pre-rendering service experiences high latency during a crawl spike, it can time out and return blank HTML payloads to search engines. Consequently, dynamic rendering is largely treated as a transitional step to stabilize crawl efficiency while migrating toward a native server-side or hybrid rendering architecture.