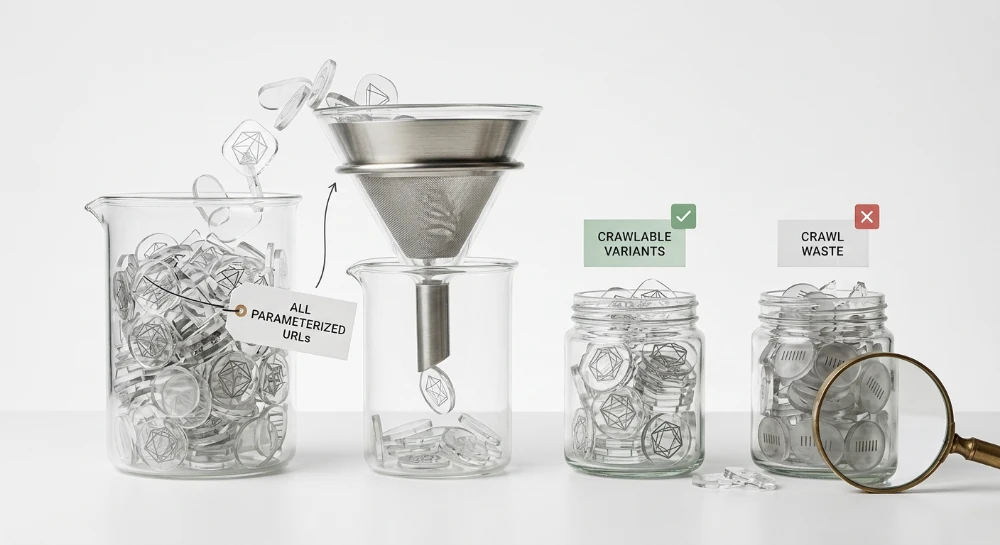
Faceted navigation is essential for user experience on large e-commerce and catalog websites, but it frequently introduces significant crawl waste. Because these filtering systems rely on URL parameters to sort and refine product listings, they generate a massive volume of dynamic URLs. As multiple attributes-such as size, color, brand, and price-are combined, the resulting query strings create a combinatorial problem that can expose an effectively infinite number of URL variations to search engine bots.
When crawlers discover and follow these multi-parameter combinations, they often enter crawler traps. This excessive crawling of overlapping filter states consumes server resources and crawl capacity, which can delay the discovery of new products or critical category updates. A common failure mode in managing this issue is relying solely on indexing controls. Directives like a canonical tag or a meta robots noindex do not solve the problem, as they do not stop a search engine from requesting the URL to read those instructions.
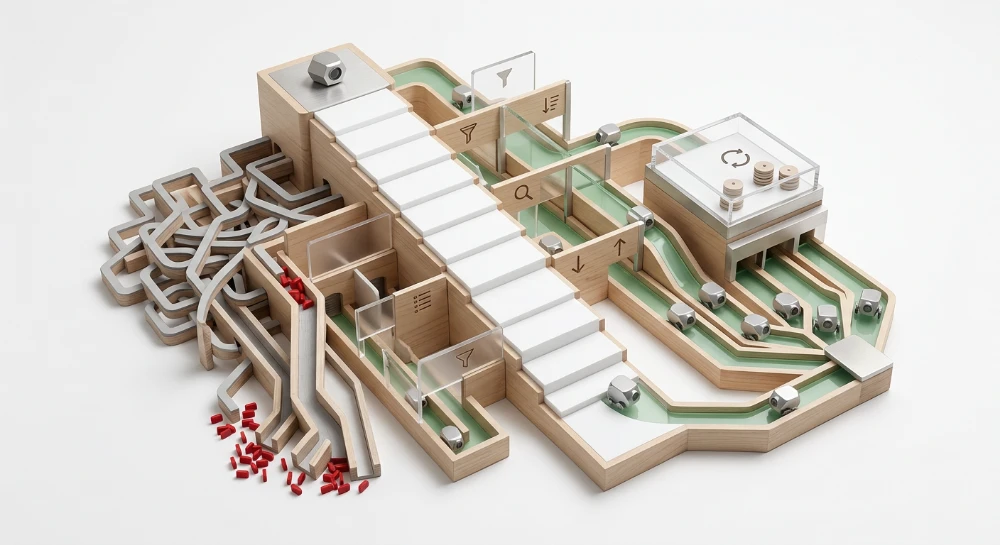
Resolving faceted crawl waste requires technical controls that block the underlying parameter space before a server request occurs. An effective implementation uses a combination of robots.txt directives and deliberate frontend HTML structures to restrict complex query combinations. The core challenge lies in balancing server load optimization with search demand, ensuring that infinite parameter chains are blocked while high-value, long-tail facet pages remain fully accessible to crawlers.
Identifying Facet-Driven crawl waste
Detecting crawl waste requires examining how search engine bots interact with the server, rather than observing the frontend interface. Because faceted navigation generates URLs dynamically based on user selections, the scale of the issue is often invisible until raw crawl data and diagnostic reports are analyzed. The two primary data sources for this diagnosis are server log files and Google Search Console.
Analyzing server log files
Server log files provide the exact record of crawler activity. By filtering the logs for requests made by search engine user agents, it is possible to quantify which URLs are consuming crawl capacity.
To identify facet-driven waste, isolate requests containing the specific query parameters used by the filtering system, such as size, color, brand, or price. Calculate the volume of these parameterized requests as a percentage of total crawler requests. If multi-parameter URLs account for a disproportionate share of the server hits-often fetching thousands of combinations that display overlapping product grids-the site is experiencing crawl waste.
Log analysis also reveals the depth of the parameter trap. Crawlers may be found requesting URLs with three, four, or five appended parameters, long after the resulting page ceases to offer unique products. Comparing the frequency of these requests against the crawl rate of static product detail pages helps determine if the filtering system is actively delaying the discovery of core inventory.
Evaluating the GSC crawl stats report
The Crawl Stats report in Google Search Console offers a high-level view of Googlebot request trends. While it lacks the line-by-line granularity of server logs, it can highlight macro-level symptoms of a crawler trap.
A sudden or sustained increase in total crawl requests without a corresponding increase in indexed pages frequently points to a parameter issue. Within the report, the crawl requests breakdown by purpose can be useful. A disproportionately high volume of discovery crawls, particularly when cross-referenced with example URLs in the report that contain long query strings, indicates that Googlebot is spending resources exploring infinite filter combinations rather than refreshing known, structural pages.
Interpreting the page indexing report
The Page indexing report provides a direct signal of how parameter traps affect search engine behavior. The most relevant status for diagnosing facet-driven crawl waste is "Discovered - currently not indexed".
This status indicates that Google has found the URL, typically by parsing a link on a category page, but has chosen not to crawl it yet to avoid overloading the site server. When search engine bots encounter an unconstrained faceted navigation system, they identify millions of multi-parameter URLs and add them to the queue. Because search engines allocate a finite amount of fetching capacity to a given domain over a specific timeframe, this large volume of dynamic URLs quickly fills the crawl queue.
If the "Discovered - currently not indexed" report is populated primarily by URLs containing complex filter strings, it confirms that the exposed parameter space is too large. The search engine is actively deferring the crawl of these variations. Left unmanaged, this backlog causes newly published products or critical category updates to remain undiscovered for extended periods, as they must wait in a queue dominated by low-value filter combinations.
Run a deep technical crawl to identify 4xx errors, missing meta tags, and indexation blockers.
Why indexing controls do not solve crawl waste
A common error in managing faceted navigation is attempting to solve crawl waste using indexing controls. While indexing controls and crawl controls both influence how a search engine interacts with a website, they operate at different stages of the search engine pipeline and serve entirely different functions.
Indexing directives dictate whether a URL should appear in search results and how ranking signals should be consolidated. Crawl directives dictate whether a search engine bot is permitted to request the URL from the server. Relying on indexing controls to manage crawl capacity fundamentally misunderstands the sequence of search engine operations.
The fetch requirement for Page-Level directives
The most frequent indexing controls applied to faceted navigation are the meta robots noindex tag and the canonical link element. Both are page-level directives, meaning they exist within the HTML document or the HTTP header.
For a search engine to read a page-level directive, it must complete the following steps:
- Add the discovered URL to the crawl queue.
- Make an HTTP request to the server.
- Wait for the server to process the database query and render the page.
- Download the HTML payload.
- Parse the code to locate the directive.
If a faceted navigation system generates five million unique parameter combinations, placing a noindex tag on all of them still requires the search engine to execute five million HTTP requests. The server load, database strain, and consumption of finite crawl capacity occur during the fetch phase. The noindex tag successfully keeps the URLs out of the search index, but it does nothing to prevent the crawl waste.
Canonicalization limits and crawl capacity
The canonical link element presents similar limitations when used as a substitute for crawl control. Canonicalizing a heavily parameterized URL back to the root category page provides a hint to the search engine about which version of the content is preferred. Search engines must still fetch the parameterized URL to discover this hint.
While search engines may eventually reduce the recrawl frequency of a known URL that consistently canonicalizes to another page, this behavior does not solve the combinatorial problem of faceted navigation. In an unconstrained parameter space, new URLs are continuously generated as links are discovered. Every new parameter combination must be fetched at least once to read the canonical tag.
Furthermore, canonical tags are hints, not strict directives. If a user applies multiple filters that significantly alter the page content, the search engine may determine that the filtered page is not a true duplicate of the root category. In such cases, the search engine might ignore the canonical hint entirely, leading to both crawl waste and potential index bloat.
To eliminate server load spikes and preserve fetch capacity for high-value structural pages, the intervention must occur before the HTTP request is made. This requires strict crawl controls that instruct the search engine not to request the parameterized URLs in the first place.
Implementing robots.txt crawl controls
To stop search engines from expending fetch capacity on infinite parameter combinations, instructions must be placed in the robots.txt file. Unlike on-page directives, robots.txt rules are processed before the HTTP request is made. When a crawler encounters a matching rule, it skips the URL entirely, preventing server load spikes and conserving crawl allocation for structural pages.
Utilizing wildcard syntax in disallow directives
Standard robots.txt directives support wildcard characters that allow site operators to target dynamic query strings. The asterisk (*) represents any sequence of characters, while the dollar sign ($) designates the end of a URL string. The question mark (?) functions as a literal character in robots.txt, making it useful for isolating the query string portion of a URL.
To prevent crawlers from entering a faceted navigation trap, the Disallow directive can be combined with wildcards to block specific parameter keys. If a site uses parameters like size or material for filtering, rules can be constructed to block any URL containing those keys.
User-agent: *
Disallow: /*?*size=
Disallow: /*?*material=
These rules instruct the crawler to ignore any URL path containing a question mark followed by the specified parameter string. This prevents crawl access to those individual filters and any multi-filter combinations that include the blocked keys.
To target URLs containing multiple parameters regardless of the specific key, a generic rule targeting the ampersand (&) can be applied. For example, blocking any URL with two or more query parameters can be achieved with a single rule.
User-agent: *
Disallow: /*?*&*
Overriding disallow directives with allow rules
Broad Disallow rules can inadvertently block high-value base categories or specific landing pages if they share the targeted parameter structure. The Allow directive resolves this by creating explicit exceptions. Search engines like Google and Bing evaluate conflicting robots.txt rules based on path length; the longest, most specific matching rule takes precedence, regardless of the order in which the rules appear in the file.
When configuring crawl controls, a general parameter can be blocked while an Allow rule ensures a specific parameter combination remains crawlable.
User-agent: *
Allow: /furniture/chairs?material=leather$
Disallow: /*?*material=
In this configuration, the specific URL path for leather chairs is permitted because the Allow rule contains more characters and is therefore more specific than the broad wildcard Disallow rule. The dollar sign ($) at the end of the Allow rule ensures that no further parameters can be appended to that specific URL, protecting the permitted path from becoming a new crawl trap if additional filters are applied.
Implementation procedure and validation
Deploying robots.txt controls requires a precise sequence to avoid accidentally blocking core site sections. The procedure follows a specific order of identification, drafting, and testing.
- Identify the exact parameter keys causing the crawl waste using server log files and crawler behavior reports.
- Draft Disallow rules targeting only those specific query strings, utilizing wildcards to account for arbitrary parameter ordering.
- Identify any base categories, static paths, or specific parameter combinations that must remain accessible to crawlers.
- Draft explicit Allow rules for these exceptions, verifying that the path strings are longer and more specific than the overlapping Disallow rules.
- Append the end-of-string character ($) to all Allow rules governing parameterized URLs to prevent subsequent parameter chaining.
- Test the rules against a sample of both desired base URLs and unwanted multi-parameter URLs using a robots.txt validator before updating the live file.
Once deployed, the crawl frequency on the blocked parameterized URLs drops immediately. Search engines will no longer fetch those specific variations. If the blocked URLs were previously indexed, they may eventually be removed from the index, though search engines can sometimes retain them under the status "Indexed, though blocked by robots.txt" if external or internal links still point to them. The immediate reduction in server load and the redirection of crawl fetch capacity to permitted pages generally outweigh this reporting artifact.
SEO structure and reciprocal link analyzer
Detect orphan pages, deep click depths, and toxic reciprocal links built by careless agencies.
Frontend implementations: Links vs. event listeners
Search engine crawlers discover new URLs primarily by parsing HTML documents for standard anchor elements containing an
href
attribute. When a faceted navigation menu is built using standard anchor tags, every permutation of those filters becomes an explicitly provided link for the crawler to extract and queue. Changing the HTML structure of the filter menu alters how search engines interact with these parameter combinations.
Limitations of the nofollow attribute
Adding a
rel="nofollow"
attribute to facet links is often treated as a crawl control measure, but it leaves the parameter traps vulnerable to discovery. Search engines evaluate the nofollow attribute as a hint rather than an absolute directive. If a multi-parameter URL is discovered through any other path-such as an external backlink, a misplaced internal link lacking the nofollow attribute, or an old sitemap-the crawler can still fetch the page. Because the standard anchor tag leaves the raw parameterized URL exposed in the document object model, relying solely on nofollow directives does not reliably prevent URL discovery.
Replacing anchors with buttons and event listeners
To prevent crawlers from discovering multi-parameter URLs in the frontend HTML, developers can replace standard anchor tags with HTML
<button>
elements governed by JavaScript event listeners. Search engine crawlers do not simulate user clicks on buttons, nor do they execute custom event listeners like
onClick
to discover navigation paths.
By structuring a non-indexable filter option with data attributes instead of a destination URL, the frontend provides the necessary instructions for the browser without exposing a link to crawlers. An implementation might use a structure such as
<button data-filter="color" data-value="red">
. A JavaScript function intercepts the user action, reads the attributes, and initiates the data retrieval process. Because there is no
href
attribute containing the query string, the crawler skips the element.
AJAX filtering and URL pushstate
Removing standard links requires a secondary mechanism to update the browser's address bar. Users expect to bookmark, share, and use the browser's back button on filtered pages. This functionality is maintained by combining asynchronous data fetching with the browser History API.
When a user activates a filter button, the JavaScript event listener requests the updated product list asynchronously, usually via AJAX or the Fetch API, and renders the new products into the existing page layout. Simultaneously, the script uses the
history.pushState()
method to update the URL in the address bar to reflect the active filter state.
This implementation updates the user's environment and maintains shareable URLs without ever embedding the resulting multi-parameter strings into the HTML
href
attributes. Crawlers parsing the initial document see only the structural buttons, effectively cutting off the internal discovery path for complex facet combinations.
Handling sorting, display, and pagination parameters
Not all URL parameters function identically, and applying a universal block across all query strings can damage site architecture. Parameters generally fall into distinct functional categories: those that reorganize existing content, those that change presentation, and those that expose new content. Categorizing these correctly determines the appropriate crawl directive.
Sorting and display parameters
Sorting parameters alter the order of items in a product grid. Typical implementations use keys such as
?sort=price-asc
or
?order=newest
. Display parameters change the presentation format or the number of items loaded per view, using keys like
?view=list
or
?limit=100
.
Neither parameter type changes the underlying inventory available within the category. A crawler accessing a category sorted by price low-to-high encounters the exact same product set as the default view, merely presented in a different sequence. Allowing search engines to crawl these variations multiplies the available URL combinations exponentially while providing zero new distinct landing pages for indexing.
Because they offer no unique discovery value and generate extensive duplicate crawl paths, sorting and display parameters should almost universally be blocked from crawling using robots.txt Disallow directives.
The distinct role of pagination
Pagination parameters, such as
?page=2
or
?p=3
, require the opposite approach. Unlike sorting or display settings, pagination provides the structural pathway required to reach items that do not fit on the primary category view. It exposes unique inventory.
If pagination parameters are blocked from crawling, the crawler cannot traverse the category tree to discover older, less popular, or deeper products. While XML sitemaps provide an alternative discovery mechanism, search engines rely heavily on the HTML link graph to establish contextual relationships and distribute internal link equity. Blocking pagination severs this direct hierarchical link path, effectively isolating products located on page two and beyond from the primary category structure.
For this reason, base pagination parameters applied directly to the main category URL must remain fully crawlable.
Combining pagination with restricted filters
Complexity occurs when pagination intersects with filtered states. A URL often contains multiple parameters simultaneously, such as
/shoes?color=blue&page=2
. The crawl rule for the paginated state must follow the rule established for the applied filter.
If a specific filter parameter is blocked to conserve server capacity, any paginated URL containing that restricted filter is automatically inaccessible to the crawler, provided the robots.txt pattern is structured to match the parameter regardless of its position in the query string. For example, a directive like
Disallow: /*color=
will prevent crawling of both the primary filtered page and its subsequent paginated views. No separate directive is needed to block pagination on filtered states.
Conversely, if an organization intentionally allows crawling on a specific high-value facet to capture search demand, the pagination sequence attached to that specific facet must also remain accessible. The configuration requires precise pattern matching to ensure the Disallow rules targeting complex, multi-facet combinations do not inadvertently block the standard pagination parameter required to traverse the allowed category paths.
Bulk Google and Yandex index checker
Verify agency reports and track live SERP status in Google and Yandex to protect your SEO ROI.
Balancing crawl control with search demand
While shutting down parameter traps is necessary for crawl efficiency, a blanket block on all filtered views often sacrifices long-tail traffic. Users frequently search for specific category-facet combinations, such as "blue running shoes" or "oak dining tables". If these high-value facet combinations are entirely blocked from crawling, the site cannot compete for those specific search queries. The objective is to preserve indexable landing pages for verified search demand while preventing the crawler from accessing infinite multi-facet combinations.
Deciding which facets to expose to search engines requires analyzing search volume and product inventory. Single facets like brand, material, or color applied to a primary category often warrant indexation. Conversely, highly specific combinations-such as a category filtered by brand, color, size, and price simultaneously-rarely have distinct search demand and often result in thin or duplicate content. A standard practice is to allow crawling and indexing for high-value single facets or two-facet combinations, while strictly blocking any deeper selections.
Mapping indexable facets to static URL paths
Exposing chosen facet combinations through raw query strings complicates crawl management. The most reliable approach is mapping verified, high-demand facet combinations to static URL paths. When a user selects a designated indexable filter, the application routes the request to a clean, sub-directory structure rather than appending a parameter to the query string.
For example, instead of allowing crawling on
/furniture/sofas?color=green
, the system exposes a distinct page at
/furniture/sofas/green
. This static URL functions as a standalone category page: it is fully crawlable, self-canonicalizing, and can be optimized with unique title tags and header elements targeting the specific search intent.
Once high-value facets are mapped to static URLs, their dynamic parameter equivalents must remain blocked. If the parameter-based URL continues to function and is crawlable alongside the static URL, it introduces duplicate content and undercuts the crawl optimization effort. The robots.txt file must continue to disallow the query string patterns. For instance, a directive like
Disallow: /*?color=
will prevent the crawler from accessing the dynamic variations, while the static path
/furniture/sofas/green
remains naturally accessible.
The faceted navigation interface must reflect this architectural mapping in its source code. When a user or crawler interacts with the "Green" filter on the sofas category, the underlying HTML anchor link must point directly to the static
/furniture/sofas/green
path, rather than a parameterized URL that redirects. This direct linking ensures that search engines crawling the parent category discover the optimized URL path immediately and can crawl the approved long-tail pages without hitting restricted parameters.