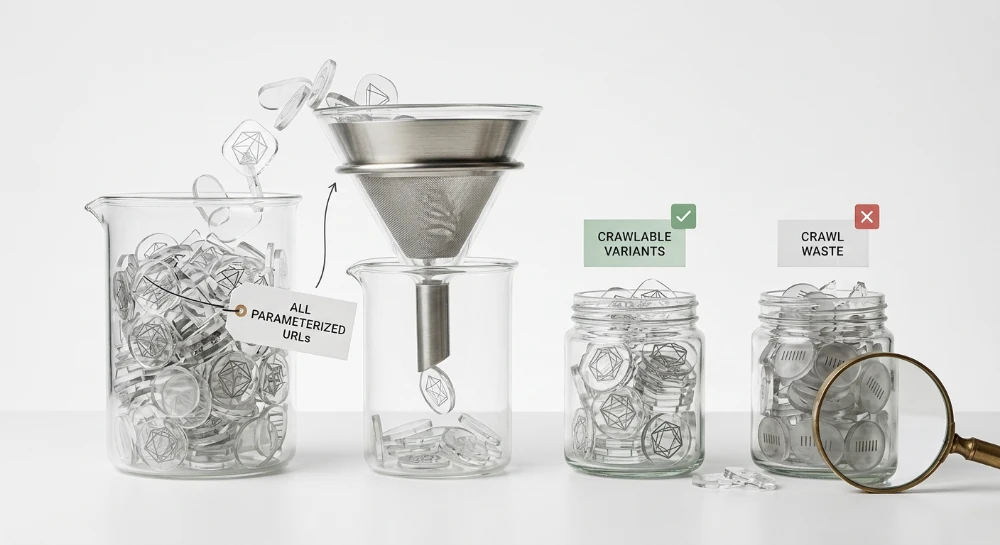
URL parameters are essential for tracking user behavior, managing sessions, and sorting dynamic content, but they are also a primary source of crawl waste. When search engines discover URLs appended with query strings-such as those generated by faceted navigation, affiliate tags, or price sorting-they often treat each new parameter combination as a distinct page to be crawled. Because dynamic parameters can be stacked and reordered indefinitely, they can generate a near-infinite number of URL variations that consume crawler capacity without adding unique, indexable value.
This rapid expansion of crawlable paths can force search bots to spend time evaluating duplicate or low-value pages rather than discovering new content or refreshing core inventory. The technical challenge is rarely just noticing that parameter bloat exists. Instead, it requires pinpointing exactly which active or passive parameters trigger the waste and isolating the internal linking structures or server configurations that expose these dynamic paths to search engines.
Resolving parameter-driven crawl waste depends on categorizing the function of each query string and mapping exactly how crawlers find them. By systematically analyzing search console data, server access logs, and site architecture, webmasters can quantify the true volume of wasted requests and locate the specific internal crawler traps driving the inefficiency.
Categorizing active vs. passive URL parameters
Identifying actual crawl waste requires evaluating the function of every query string appended to a URL. Not all parameters consume crawler capacity unnecessarily. The prerequisite for addressing parameter bloat is separating them into two distinct functional categories: active and passive.
Active parameters fundamentally change the content displayed on the page. When a user or crawler requests a URL with an active parameter, the server returns a distinct set of items, a specific product variation, or a new page of results that cannot be accessed through the base URL alone. Because they expose unique inventory, active parameters generally require search engine discovery.
Common examples of active parameters include:
- Core category filters that narrow an inventory set to a distinct subcategory, such as ?brand=samsung or ?type=sneakers.
- Pagination parameters that sequence through a list of results, such as ?page=2.
- Product variant parameters that load a specific, orderable item, such as ?color=blue or ?size=large.
If active parameters are improperly restricted from crawling, search engines may fail to discover the distinct content or deeper site architecture they represent.
Passive parameters do not change the core content of the document. Instead, they alter the presentation of existing content, track user behavior, or maintain a temporary user state across a visit. The underlying HTML returned by a passive parameter is functionally identical to the canonical version of the page, meaning the parameter adds no new indexable value.
Common examples of passive parameters include:
- Sorting and display modifiers that rearrange identical inventory, such as ?sort=price_asc, ?view=grid, or ?limit=100.
- Tracking parameters used by analytics platforms, such as ?utm_source=newsletter or ?gclid=123.
- Session and affiliate management parameters, such as ?session_id=abc or ?ref=affiliate456.
Because passive parameters yield duplicate content, search engines do not need to discover or crawl them to understand the site's inventory. Unchecked discovery of these passive paths is the primary driver of parameter-based crawl waste.
In practice, web applications frequently stack both active and passive parameters in a single URL string. A single request might contain a category filter, a sorting preference, and a tracking tag simultaneously. Categorizing each parameter independently establishes the baseline for crawl control: active parameters define the boundaries of the indexable site architecture, while passive parameters define the patterns that must be consolidated or blocked.
Run a deep technical crawl to identify 4xx errors, missing meta tags, and indexation blockers.
Identifying parameter bloat in Google search console
Google Search Console provides direct visibility into which parameterized URLs search engines are finding and how they evaluate those paths. The Page Indexing report logs URLs that Google has identified, offering a sample of the parameter patterns currently occupying the crawl queue.
Isolating parameters in the page indexing report
To locate parameter bloat, navigate to the Page Indexing report and focus on two specific exclusion statuses:
- Crawled - currently not indexed: This status indicates Googlebot actively fetched the URL, consuming a server request, but chose not to index the result. Passive parameters frequently populate this category because Google evaluates the fetched HTML, recognizes it as duplicate content, and discards it.
- Discovered - currently not indexed: This status means Google found the URL through internal links or external signals but postponed the fetch. A high volume of parameterized URLs in this category often signals that the site architecture is generating infinite URL spaces faster than the search engine is willing to crawl them.
Click into either status report and apply a URL filter above the data table. Set the filter to URLs containing and input a question mark (?). This broad filter isolates every URL in that status group containing a query string.
For more specific diagnostics, filter the report using known parameter keys. Switching the filter to Custom regex allows you to target multiple suspected passive parameters simultaneously by separating the keys with a pipe character, such as utm_|sort|session. Exporting these filtered lists provides a concrete sample of the exact URL combinations Google is discovering.
Evaluating request volume with crawl stats
While the Page Indexing report shows which URLs Google has recorded over time, the Crawl Stats report reveals the actual frequency of Googlebot network requests. This report is located under the Settings menu.
Use the Crawl Stats report to evaluate the proportion of Googlebot request volume hitting parameter-heavy paths compared to clean canonical URLs. Drill down into the groupings by Crawl purpose, specifically reviewing the Discovery category, which logs requests to previously unknown URLs. Examine the sample URLs provided in the details panel for these drill-downs. If complex query strings account for a disproportionate share of the daily crawl requests compared to primary category or article URLs, it confirms that passive parameters are actively consuming crawler resources.
Measuring true crawl volume with server logs
While Google Search Console provides diagnostic samples of parameter discovery, it does not display every URL requested by search engines. The Crawl Stats report offers broad categorization, but to measure the exact scale of parameter-driven crawl waste, server access logs are required. Logs record every HTTP request made to the server, providing a complete, unfiltered ledger of crawler behavior.
To analyze this data, export your server access logs and filter the records to isolate relevant search engine traffic. Begin by filtering the User-Agent field to match search engine bots, such as Googlebot. Next, isolate the requests to parameterized URLs by filtering the request URI field for strings containing a question mark (
?
). This yields a dataset consisting entirely of parameterized paths that search engines are actively requesting.
Because dynamic URLs often stack multiple parameters, the raw list of requested URIs must be categorized by parameter key to accurately measure volume. Process the filtered URLs to extract the primary parameter keys from each query string. This step allows you to group the individual requests based on the parameters they contain, separating hits for
sort=
from hits for
utm_
or
session_id=
.
Once the keys are isolated, aggregate the log data by counting the total number of bot hits for each specific parameter group. This aggregation reveals the precise volume of server requests consumed by individual passive parameters over the logged period. By comparing the request counts of these high-volume passive parameters against the total requests made to clean canonical URLs, you can quantify exactly how much server overhead and crawl capacity is absorbed by non-indexable URL variations.
SEO structure and reciprocal link analyzer
Detect orphan pages, deep click depths, and toxic reciprocal links built by careless agencies.
Crawling the site to locate parameter discovery sources
Log analysis identifies which parameters are actively crawled, but mitigating that activity requires locating the structural pathways search engines use to discover those URLs. Search engine bots find new URLs primarily by extracting links from page HTML. To identify these entry points, configure an SEO crawler to spider the site, ensuring the tool parses the HTML precisely as a search engine would.
Once the crawl completes, filter the results for URLs containing a query string, typically identified by the
?
character. Navigate to the incoming links data for these parameterized URLs to pinpoint the exact source pages and HTML elements generating the crawl activity. When investigating these internal links, evaluate the site for four common structural triggers.
Faceted navigation links in standard HREF attributes
E-commerce filters, pagination routines, and sorting features are frequently built using standard HTML anchor tags (
<a>
) with the parameterized URL declared in the
href
attribute. Because search engines natively extract and follow
href
values, exposing passive parameters like sorting directions (
?sort=price_asc
) or layout preferences directly in these attributes guarantees crawler discovery. If the bot can parse the link from the document object model, it will queue the destination URL for crawling.
Hardcoded internal tracking parameters
Site owners sometimes append tracking parameters, such as UTM codes or custom campaign identifiers, to internal links to measure banner interactions or cross-site promotions. Hardcoding these passive parameters into persistent site architecture creates a highly visible discovery source for crawlers. Every time a bot processes a page containing these promotional links, it discovers and crawls the parameterized variant of the target page, bypassing the clean canonical version.
Improper relative linking
When internal links are constructed using relative paths without a leading slash or an absolute base URL declaration, the crawler resolves the destination link relative to the URL it is currently processing. If a bot is already crawling a parameterized path and encounters a relative link that only specifies an additional query string, the crawler may append the new parameter directly to the existing URL. This structural flaw can cause parameters to stack endlessly as the bot navigates, creating deep, invalid URL combinations that the server must process.
Incorrectly configured canonical tags
While canonical tags do not act as initial discovery links, they dictate how crawlers interpret the parameterized URLs they find. A common CMS misconfiguration occurs when the canonical tag is set to dynamically echo the exact URL currently being requested. If a crawler discovers a passive parameter URL and requests it, a self-referencing canonical tag validates that specific parameter combination as a distinct, indexable entity. Identifying these dynamic canonicals during a site crawl highlights instances where the platform is actively instructing search engines to retain parameter variants rather than consolidating them.
Detecting crawler traps in faceted navigation
Multi-select filters in faceted navigation are the most frequent cause of exponential URL generation. When users can filter a category by multiple attributes simultaneously-such as size, color, brand, and price range-the resulting URLs stack these selections into long query strings. If internal navigation exposes every possible filter combination as a standard link, bots can enter an architecture of endless permutations.
The impact of parameter order
The scale of this issue multiplies when the system lacks a fixed parameter order. If clicking a color filter then a size filter generates a URL ending in ?color=red&size=large, but clicking the size filter first generates ?size=large&color=red, a crawler treats these as two distinct addresses. This path-dependent URL generation creates redundant discovery paths for the exact same page state. If a category offers several different filter types, the permutations of varying parameter orders can quickly scale into millions of unique URLs.
JavaScript-Rendered filtering flaws
Modern faceted navigation often relies on JavaScript to update product grids without a full page reload. However, if the underlying Document Object Model uses standard href attributes on the filter elements to manage application state or provide non-JavaScript fallbacks, search engine bots will still extract and follow these links. A crawler processing a JavaScript-rendered page can discover and queue thousands of parameterized URLs if the structural HTML explicitly provides those paths during rendering.
Testing for infinite URL spaces
To confirm whether a faceted navigation setup acts as a crawler trap, test how the server handles unexpected or arbitrarily stacked parameters. This involves manually manipulating the query string of a valid category URL and observing the HTTP response and output.
- Stack duplicate parameters by appending the same key multiple times, such as ?size=large&size=large&size=large.
- Reverse the sequence of two valid parameters to see if the system forces a standardized parameter order.
- Append a fabricated parameter key and value to the end of a valid query string.
If the server responds to these manipulated URLs with a 200 OK status code instead of returning a 404 error or a 301 redirect to a consolidated URL string, the site operates an open URL space. To evaluate if the server is processing these requests as distinct content, compare the raw HTML file size and the internal product item count between the manipulated request and the standard request. A 200 OK response that returns identical HTML for varying parameter stacks confirms that the server is validating endless combinations without altering the core presentation.
Bulk Google and Yandex index checker
Verify agency reports and track live SERP status in Google and Yandex to protect your SEO ROI.
Triaging parameters for crawl control
With server logs and crawl data detailing which parameters exist and how they are discovered, the next step is assigning a control mechanism to each query string. Not all parameters require the same restriction. The goal is to categorize the identified parameters into three distinct groups based on whether the resulting URL requires indexing, requires signal consolidation, or represents pure crawl waste. This triage process bridges the gap between identifying the source of the waste and implementing the correct server or structural fix.
Parameters requiring indexing
Certain active parameters fundamentally alter the page content and represent distinct pages that search engines should index. Common examples include core category filters that define a unique product set, standard pagination paths (such as
?page=2
), and distinct product variants that rely on query strings instead of static URL paths.
These URLs should remain fully accessible. Do not apply robots.txt disallow rules or point canonical tags to a different root URL. The focus for this group is ensuring that internal structural links consistently point to these exact paths without appending unnecessary secondary parameters.
Parameters requiring signal consolidation
The second category includes parameters that alter the presentation or sort order of the content without creating a uniquely indexable document. Examples include sorting modifiers (
?sort=price-low
), view preferences (
?view=grid
), or minor item configurations where a single master product page is preferred for the index.
These URLs should generally be crawled, but their indexing must be consolidated. Apply a
rel="canonical"
tag on these pages pointing back to the clean, non-parameterized version of the URL. Because search engines must access the HTML to read the canonical tag, these parameters cannot be blocked by robots.txt. Leaving them accessible allows search engines to process the canonical instruction and consolidate any external links or internal signals pointing to the parameterized variation.
If server log analysis reveals that a specific canonicalized parameter is generating extreme request volume that degrades server performance, it may need to be escalated to a robots.txt block. This requires trading the benefit of signal consolidation for immediate crawl control.
High-Volume passive parameters
The final category encompasses parameters that do not change the core content, provide no indexable value, and generate vast numbers of distinct URLs. This group includes external marketing tags (such as UTMs or affiliate IDs), internal session identifiers, and the arbitrarily stacked multi-select faceted filters identified during crawler trap testing.
Because these URLs offer no unique content and rarely attract valuable external links that require consolidation, allowing search engines to crawl them merely to process a canonical tag is an inefficient use of resources. These parameters should be blocked outright using robots.txt disallow rules.
Implementing targeted pattern matches, such as
Disallow: /*?utm_
or
Disallow: /*&sessionid=
, halts the crawler at the edge. By preventing search engines from requesting the HTML entirely, the server immediately recovers crawl capacity and severs the infinite discovery loop created by dynamic tracking or filtering systems.