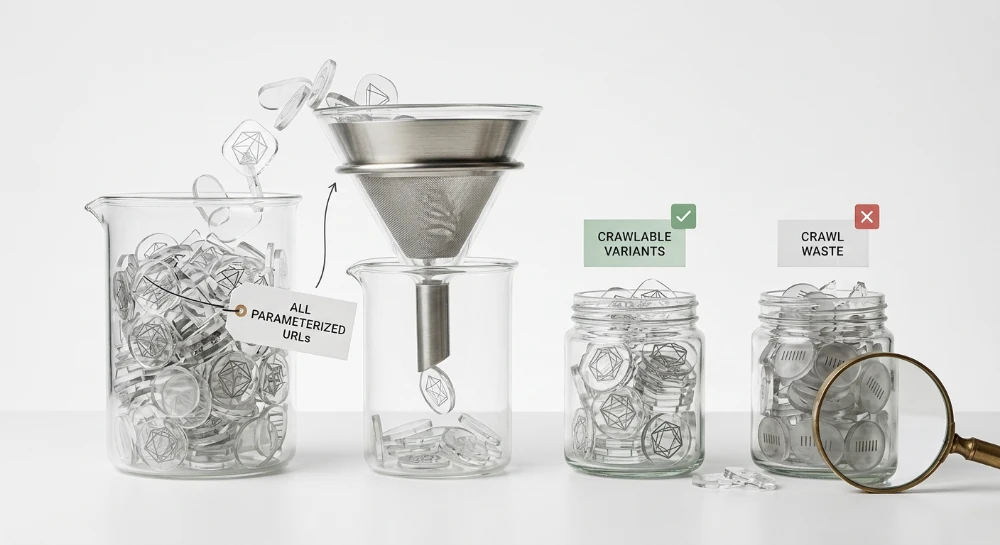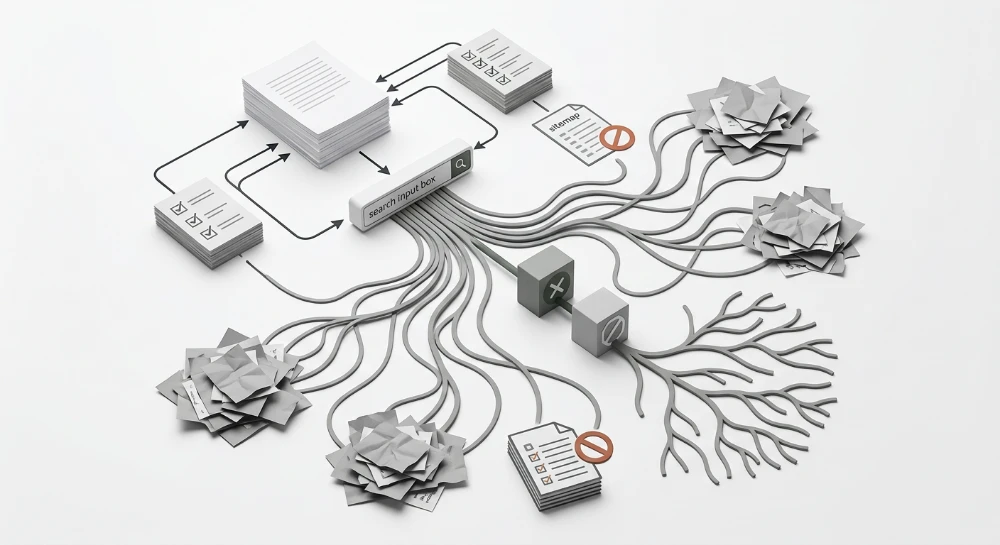
Internal site search provides essential functionality for users, but it introduces a significant technical SEO challenge: search parameters can generate an infinite crawl surface. Every unique query, category filter, or sorting option requested by a visitor creates a new dynamic URL. For search engine crawlers, this dynamic generation acts as an endless directory of auto-generated pages that offer little to no unique value for organic search.
If left uncontrolled, search engine bots may spend considerable time discovering and requesting these internal search URLs. This behavior consumes crawl capacity that would be better spent discovering core content, product pages, or critical site updates. Furthermore, when crawlers can access unprotected internal search paths, the site becomes vulnerable to index bloat. In these cases, thousands of low-quality query pages-sometimes exacerbated by automated search spam-can populate search engine indices and dilute the site's overall quality signals.
Preventing this crawl space expansion requires precise configuration of bot directives, starting with a clear distinction between crawling and indexing. Recognizing how dynamic search URLs behave, and identifying whether bots are currently crawling or indexing these paths, determines the appropriate technical response for controlling crawler access and preserving server resources.
Why internal search creates infinite crawl spaces
Internal site search functionality relies on dynamic URL parameters to parse queries and retrieve relevant database records. When a user or bot submits a query, the system appends the requested string to a base path, generating a unique URL. Because these parameters can accept any combination of characters, the number of potential URLs is functionally limitless.
The scale of this issue multiplies rapidly when faceted navigation or sorting parameters are introduced to the search results. A single root query can splinter into thousands of distinct URLs through a combinatorial explosion of appended parameters.
/search?q=boots
/search?q=boots&size=10
/search?q=boots&size=10&sort=price_asc
/search?q=boots&size=10&sort=price_asc&color=black
To a search engine crawler, each permutation appears as a distinct, crawlable path. Without technical boundaries, bots can become trapped in an endless loop of discovering and requesting these auto-generated permutations, consuming crawl capacity that would otherwise be allocated to static, high-value product or content pages.
Server resource strain and 5xx errors
Unlike retrieving static HTML files, rendering an internal search page typically requires the server to execute a database query. When search engine bots discover an unprotected search directory, they can rapidly request hundreds or thousands of query permutations.
This automated, high-volume requesting forces the server to continuously process complex database lookups. If the bot's request rate exceeds the server's processing capacity, it can lead to resource exhaustion. Under severe load, the server may fail to fulfill the requests, responding with 500 (Internal Server Error) or 503 (Service Unavailable) HTTP status codes. Frequent 5xx errors degrade the site's overall crawl reliability and can interrupt access for actual users trying to navigate the site.
Vulnerability to search spam injection
An open, uncrawled search directory also exposes a site to targeted search spam campaigns. Automated spam networks actively hunt for unprotected internal search endpoints to generate irrelevant, indexable content on authoritative domains.
The mechanism relies on the fact that search result pages typically reflect the user's query in the page heading or title tag. Attackers generate automated external links pointing to the target site, embedding spam keywords directly into the query string parameters. If a crawler follows these external links, the server processes the request and returns a valid 200 OK HTTP status code for a page that now displays the injected spam terms.
When these pages are indexed, the result is index bloat. The search engine's index of the domain becomes cluttered with thousands of low-quality, auto-generated spam URLs, creating an inaccurate representation of the site's primary content and purpose.
Run a deep technical crawl to identify 4xx errors, missing meta tags, and indexation blockers.
Identifying search crawl issues in GSC and server logs
Server log files record every HTTP request processed by the server, providing an exact record of crawler activity. To detect if search engine crawlers are trapped in a search directory, extract the server access logs and filter the data by search engine user agents, such as Googlebot, alongside the specific path or query string used for internal search, such as
/search?q=
or
?keyword=
.
Review the filtered log data for abnormal request volumes directed at these paths. If the logs show thousands of hits to unique search query combinations, the crawler has likely entered an unprotected search endpoint. Pay attention to the HTTP status codes returned for these requests. A high frequency of 200 OK responses to dynamic search URLs confirms the server is actively generating pages for the crawler, while an escalating pattern of 500 or 503 status codes indicates the request volume is exceeding server capacity.
Diagnosing load with the crawl stats report
Google Search Console provides visibility into Googlebot's request volume through the Crawl Stats report. This report is useful for diagnosing excessive server request rates without requiring raw log processing. A sudden, sustained spike in total crawl requests often signals that Googlebot has discovered a dynamically generated crawl space.
Within the Crawl Stats report, examine the "By crawl response" breakdown. If the internal search directory is causing resource exhaustion, the "5xx (Server error)" category will typically show an increase in volume that mirrors the spikes in total crawl requests. You can select the 5xx row to view specific URL examples, which will confirm if the failing requests are isolated to the site's search paths.
Detecting crawl waste and index bloat in the page indexing report
The Page Indexing report reveals how Google evaluates search URLs after they are discovered. By applying a table filter for the site's search parameter, administrators can isolate internal search URLs and check their exact processing status across several specific groupings.
- Discovered - currently not indexed: A large volume of search URLs in this category indicates that Google has found the paths but deferred crawling them, often as a mechanism to prevent overloading the host server.
- Crawled - currently not indexed: Search URLs listed here represent realized crawl capacity usage. Googlebot requested, downloaded, and processed these dynamic pages, but ultimately evaluated them as unsuitable for the index.
- Indexed, not submitted in sitemap: If search URLs appear in this group, the site is actively experiencing index bloat. Googlebot has successfully processed the internal search endpoints and added the auto-generated result pages to the public search index.
Robots.txt vs. noindex: Choosing the right control method
Controlling dynamic search directories requires a clear understanding of the difference between crawl directives and indexing directives. While they are often discussed together, they operate at different stages of search engine processing and serve distinct technical purposes.
The
robots.txt
file uses the
Disallow
directive to instruct compliant search engine crawlers not to request specific URL paths. Applying this to a search parameter prevents crawlers from fetching the auto-generated pages, effectively preserving crawl capacity and reducing server load. However, a
robots.txt
disallow rule is not an indexing control. If search engines discover a blocked search URL through external links or historical crawl data, they can still index the URL reference without crawling the page content. This scenario typically surfaces in Google Search Console under the "Indexed, though blocked by robots.txt" status.
Conversely, the
noindex
directive explicitly instructs search engines not to include the URL in their search results. This method ensures that the dynamic search pages will not appear in the index, removing existing indexed URLs. The technical trade-off is that search engine crawlers must successfully request, download, and parse the document or its HTTP headers to read the
noindex
instruction. Because the crawler must access the page to verify the directive, this method continues to consume server resources and crawl capacity.
| Control Method | Primary Function | Crawl Capacity Impact | Indexing Outcome |
|---|---|---|---|
robots.txt
Disallow
|
Prevents crawling and fetching of page content | Saves capacity by stopping requests before they occur | Does not guarantee deindexing; URLs can be indexed via external links |
noindex
directive
|
Prevents indexing and display in search results | Consumes capacity because crawlers must fetch the URL to read the directive | Guarantees removal from the search index once processed |
These two mechanisms present a strict operational conflict: they cannot be executed simultaneously to achieve both benefits. If a search path is blocked by a
robots.txt
rule, crawlers are forbidden from accessing the page and therefore will never read a
noindex
tag. Selecting the appropriate control method depends on the current state of the site's search URLs. If the primary issue is server resource consumption and the search pages are not currently indexed, blocking via
robots.txt
is the standard choice. If the site has already accumulated indexed search pages, the
noindex
directive is required to initiate removal, meaning the search paths must remain accessible to crawlers until the index clears.
Bulk Google and Yandex index checker
Verify agency reports and track live SERP status in Google and Yandex to protect your SEO ROI.
Blocking search crawlers with robots.txt
When internal search pages are not yet indexed or when server load reduction is the immediate priority, the robots.txt file provides the most direct control mechanism. By applying a Disallow directive, site administrators can instruct compliant search engine crawlers to ignore specific URL patterns associated with the search function. This prevents crawlers from requesting the infinite combinations of search queries, thereby preserving server resources and crawl capacity.
Targeting search URL patterns
The precise Disallow rule depends on how the site architecture generates search URLs. These URLs typically follow one of two formats: a dedicated search directory path or a dynamic query parameter appended to various site directories.
If the internal search function routes all queries through a specific directory path, such as example.com/search?q=shoes, blocking the entire directory is straightforward.
User-agent: *
Disallow: /search/
Disallow: /catalogsearch/
This rule prevents crawlers from accessing any URL that begins with the specified directory prefix, regardless of the query parameters appended afterward. It cleanly severs access to the entire search function without requiring complex pattern matching.
Utilizing wildcards for query parameters
Many content management systems do not use a dedicated search directory. Instead, they append a search parameter directly to the root domain or category pages, such as example.com/?s=shoes or example.com/products/?keyword=boots. In these configurations, wildcards are necessary to isolate the search parameter without blocking the underlying structural pages.
The asterisk wildcard matches any sequence of characters. To block a specific search parameter, the rule must account for the parameter appearing anywhere in the URL string, as well as the possibility that it might not be the first parameter in the sequence.
User-agent: *
Disallow: /*?s=
Disallow: /*&s=
In this configuration, the asterisk matches any directory path leading up to the parameter. The first rule targets the search key when it initiates the query string, while the second rule targets the key when it follows another parameter. This ensures that a URL like example.com/category/?sort=price&s=shirts is blocked, but the base category page example.com/category/ remains accessible for crawling.
Mitigating accidental blocking
Applying wildcards carries the risk of inadvertently blocking essential site assets, structural pages, or beneficial parameters. A common error when attempting to manage crawl capacity is using an overly broad rule to target all dynamic URLs.
User-agent: *
Disallow: /*?*
While this global wildcard rule successfully blocks internal search queries, it also severely over-blocks the site. It prevents crawlers from accessing pagination parameters, faceted navigation, campaign tracking tags, and dynamically generated media files that rely on query strings.
To prevent over-blocking, the Disallow directive must remain as specific as possible. If a search parameter shares a key with a necessary function, the rule must incorporate the specific path prefix associated with the search function rather than relying solely on the parameter key. For example, if a site uses the letter "q" for both internal search and an essential product API endpoint, the rule must specify the exact path where the search query originates.
Before deploying new robots.txt directives to a production environment, test the rules against a representative sample of URLs using a robots.txt validation tool. A robust test suite must include known internal search URLs, standard content pages, paginated category pages, and essential static assets. This validation confirms that the wildcard syntax successfully restricts the infinite search crawl space without severing access to primary site content.
Applying noindex and X-Robots-Tag for index bloat
If internal search URLs are already indexed-often due to existing search spam or historical crawl configuration issues-a robots.txt Disallow directive will not remove them from the index. To resolve index bloat, search engines require an explicit instruction to drop the URLs.
A search engine crawler cannot read a deindexing directive on a page it is forbidden to crawl. If a robots.txt rule currently blocks the internal search directories or parameters, that rule must be removed. Crawlers must be allowed to access the indexed search URLs to discover the deindexing instructions. Once the URLs are successfully dropped from the index, the robots.txt block can be reinstated to conserve crawl capacity.
Using the noindex meta tag
The standard method for deindexing HTML pages is the robots meta tag. This tag must be placed within the document head of all internal search result pages.
<meta name="robots" content="noindex">When implementing this via a content management system or application framework, ensure the logic applies exclusively to search result templates or routes handling specific query parameters. Applying the tag too broadly risks deindexing structural category pages or primary content that shares the same underlying page template.
Implementing the X-Robots-Tag HTTP header
The X-Robots-Tag achieves the exact same deindexing result but is delivered via the HTTP response header rather than the HTML document. This approach is useful when managing directives at the server configuration level is more efficient than modifying application code, or when the dynamically generated search assets include non-HTML files like PDFs or raw API endpoints.
X-Robots-Tag: noindexServer configuration files can be updated to append this header conditionally based on the URL path or the presence of a search query string. Because the directive is processed before the browser or crawler parses the document body, it provides a highly reliable method for enforcing deindexing rules across diverse file types.
Whether using the HTML meta tag or the HTTP header, the deindexing process requires time. Search engines must recrawl the affected URLs to process the new directives. Progress is reflected in the Google Search Console Page Indexing report as search URLs transition into the "Excluded by ‘noindex’ tag" status.
SEO structure and reciprocal link analyzer
Detect orphan pages, deep click depths, and toxic reciprocal links built by careless agencies.
Managing internal links to search results
Crawlers discover new pages primarily by extracting URLs from internal links and HTML elements. Even if dynamic search parameters are excluded from XML sitemaps, placing links to internal search pages anywhere within the site structure provides a direct pathway for search engines to queue and request those URLs.
Developers and SEOs should audit global navigation, footer menus, and inline content blocks to ensure they do not link to search result paths. It is common for content editors to link to a site search query as a quick way to group related items, but this practice unnecessarily exposes parameter-based URLs to crawlers. Instead, structural links should direct crawlers and users to canonical category or tag pages built on static routing.
When an internal link to a search result is functionally required, such as a user-interface button that expands a list of matches, the rel="nofollow" attribute can be applied. This attribute signals to search engine crawlers that the destination URL should not be followed, helping contain crawl paths without breaking the user experience.
<a href="/search?q=blue+widgets" rel="nofollow">See all widgets</a>This prevention mechanism also applies to the HTML forms that power the site search. Because internal search functions typically use the GET method, they automatically append queries to the URL string. Adding the rel="nofollow" attribute directly to the form tag discourages crawlers from parsing the form action or attempting to follow the dynamically generated paths.
<form action="/search" method="GET" rel="nofollow">While managing internal links does not replace server-level crawl directives, it eliminates the internal discovery mechanisms that introduce search URLs to the crawl queue in the first place.