Search engines are highly capable of discovering standard media elements natively during the normal crawling process. When an image or video is embedded directly in server-rendered HTML using standard tags, crawlers generally do not require additional configuration to find it. However, implementing image and video sitemaps-or adding media namespace extensions to existing XML sitemaps-becomes highly useful when assets exist in technical environments that obscure standard crawler pathways.
Dedicated media sitemaps serve as a direct data feed, bypassing discovery hurdles created by client-side JavaScript rendering, aggressive lazy-loading, or media hosted on separate Content Delivery Networks (CDNs). By providing explicit file locations and contextual data upfront, these XML extensions ensure media assets are queued for processing even if they are not immediately visible in the initial HTML document.
The effectiveness of this approach depends entirely on strict data alignment. Search engines use the accompanying XML metadata, such as thumbnail URLs, video duration, or licensing attributes, to parse the media context before fully rendering the page. If the details provided in a media sitemap conflict with on-page structured data or the actual file properties, the mismatch can trigger validation errors and prevent successful indexing.
When media sitemaps support discovery
For websites relying on traditional server-side rendering, standard media tags embedded directly in the initial HTML payload rarely require dedicated sitemap extensions for basic discovery. When a search engine crawler processes a page and encounters a standard image or video source attribute within the raw source code, it extracts the URL and queues the file for processing automatically.
Media sitemaps provide a tangible advantage when the website architecture separates the media asset from the initial page load. In these environments, providing explicit file locations prevents search engines from missing assets that require complex rendering or user interaction to appear in the Document Object Model.
Lazy-Loaded content
Implementing lazy-loading improves page performance by deferring the loading of off-screen images and videos until a user scrolls near them. If the lazy-loading implementation relies on scroll events or specific user interactions that search engine crawlers do not perform, the media may never load during a standard crawl. Supplying the media URLs via an XML extension ensures the crawler receives the asset locations upfront, sidestepping the need to trigger the deferred loading mechanism.
Client-Side rendering and AJAX
When media elements are injected into the page via client-side JavaScript or fetched asynchronously using AJAX after the initial page load, search engines must execute the JavaScript to discover the content. Because JavaScript rendering is computationally expensive, search engines often delay this process, placing the URL in a separate render queue. A media sitemap bypasses this delay by feeding the media URLs directly to the crawler, initiating asset discovery before the page is fully rendered.
External content delivery networks
Hosting images and videos on a separate Content Delivery Network domain often complicates the relationship between the media asset and the host page. Without clear signals, a crawler might treat the CDN URL as an isolated file rather than an integrated component of the primary domain. Including CDN-hosted media in the host domain's sitemap explicitly maps the external file to the canonical page URL, confirming the association for the search engine.
Run a deep technical crawl to identify 4xx errors, missing meta tags, and indexation blockers.
Integrated vs. standalone media sitemaps
When implementing media sitemaps, publishers can choose between two structural models. The media XML extensions can be integrated directly into an existing primary page sitemap, or they can be deployed as a separate, dedicated sitemap file. Both methods use the same XML namespace protocols and fulfill the identical technical function of mapping media assets to a specific host page. The decision between the two depends on site architecture, media update frequency, and monitoring requirements.
Integrated media sitemaps
An integrated sitemap embeds the media namespace blocks directly within the standard URL entry for the host page. When a crawler processes the sitemap to discover the page, it receives the associated image or video metadata simultaneously.
This implementation model firmly couples the media asset to the host page lifecycle. If a product page is removed from an e-commerce site, the corresponding entry drops from the primary sitemap, automatically removing the associated product images from the submitted URLs list. Because of this synchronized lifecycle, most conventional content management systems and standard SEO plugins default to the integrated approach.
Integrated sitemaps are highly practical for standard websites, blogs, and e-commerce platforms where media is static and serves strictly as an accompaniment to the main page content.
Standalone media sitemaps
A standalone media sitemap isolates pages containing media into a separate XML file, such as a dedicated video sitemap. A standalone media sitemap still uses the host page URL as the primary location indicator; it simply filters the file contents to only include URLs that feature media assets, appended with the necessary media namespace extensions.
This separation offers distinct administrative and technical advantages for sites with extensive media libraries. If a platform frequently updates, adds, or cycles videos on a page without altering the underlying text content, updating a targeted media sitemap is more efficient. The system can ping search engines to fetch the updated media sitemap without requiring a full re-generation and re-processing of a massive primary page sitemap.
Additionally, isolating media into a standalone file provides a cleaner diagnostic view in search engine reporting tools. By submitting a dedicated file, webmasters can monitor the exact number of media-rich URLs submitted and compare it directly to indexing reports, avoiding the data dilution that occurs when media pages are mixed with text-only URLs in a general sitemap.
Decision criteria
Selecting the appropriate implementation model requires evaluating the scale and infrastructure of the website.
- Use integrated sitemaps when the CMS natively handles media and page generation as a single event, and the site does not require isolated monitoring for media-specific indexing.
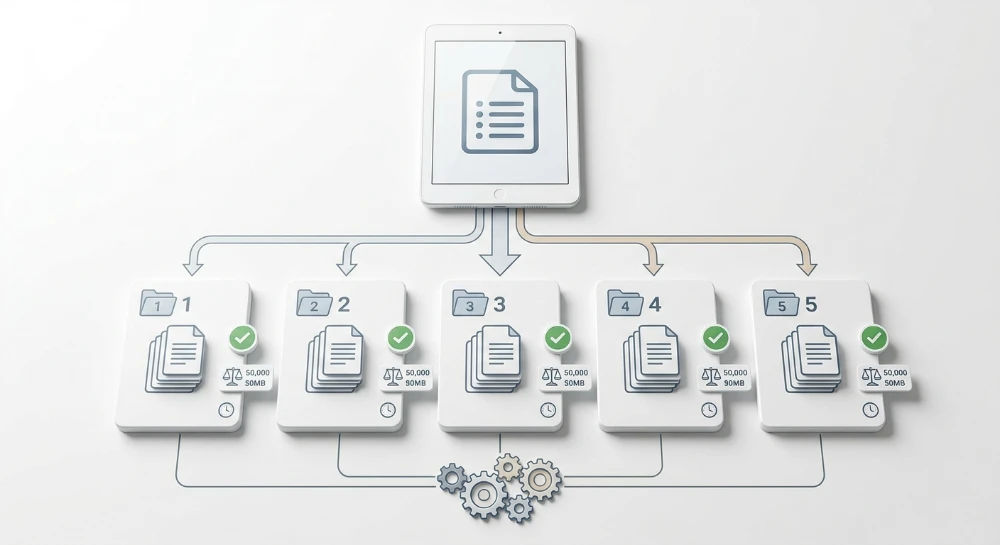
- Use standalone sitemaps for media-centric sites, such as stock photography platforms or video streaming hubs, where the total volume of media URLs is vast enough to require careful file management to stay under sitemap size limits.
- Use standalone sitemaps if the media library is managed by a separate headless system or external media server that can automatically generate its own XML feeds independently of the primary web server.
- Use standalone sitemaps when frequent media rotation on static host pages requires rapid sitemap updates to prompt crawler discovery of the new assets without rebuilding the site index.
Configuring the image sitemaps namespace
To include image-specific data within an XML sitemap, the file must first declare the image namespace in the root element. This namespace declaration defines the schema, allowing the crawler to process the extended tags correctly alongside standard sitemap URLs.
Images in a sitemap are directly associated with their parent page URLs. The parent page is defined using the standard locator tag, and the image namespace extensions are nested within that page's URL block.
Required elements
The image sitemap schema relies on two mandatory tags for each declared image:
- The <image:image> tag functions as a wrapper for a single media asset associated with the parent URL. A single page block can contain multiple image wrappers, up to a limit of 1,000 images per page.
- The <image:loc> tag must be nested directly inside the wrapper. It specifies the absolute URL of the actual image file.
A basic structural implementation relies solely on the locator tags for the page and the image asset.
<url>
  <loc>https://example.com/photography-portfolio/</loc>
  <image:image>
    <image:loc>https://example.com/media/sunset-hdr.jpg</image:loc>
  </image:image>
</url>
Contextual metadata tags
While the location tag ensures search engines can discover the file path, the namespace supports optional child elements that supply textual context. These optional tags are particularly useful when the on-page HTML lacks adjacent descriptive text, or when the media files are hosted on a separate domain that lacks intrinsic page context.
- The <image:title> tag provides a concise name for the asset. This serves a function similar to an image title attribute, summarizing the subject of the photograph or graphic independently of the raw filename.
- The <image:caption> tag supplies a longer description of the image. This typically reflects the visible caption text displayed alongside the media on the rendered page, helping indexers associate the image with specific entities or events.
- The <image:license> tag specifies the URL of a document detailing the usage rights for the image. Submitting accurate licensing metadata supports distinct search engine features, such as displaying a "Licensable" badge directly in image search results. This interface treatment helps users identify copyright terms and navigate to purchase or usage details.
When implementing optional metadata tags, the supplied data should remain consistent with the context served to users on the actual web page. Providing a caption or title in the XML namespace that fundamentally contradicts the visible on-page context can result in the metadata being ignored during processing.
Bulk Google and Yandex index checker
Verify agency reports and track live SERP status in Google and Yandex to protect your SEO ROI.
Configuring the video sitemaps namespace
The video sitemaps namespace allows search engines to parse a video file or its player context before fully rendering the host page. Providing this data directly in the XML file is useful when video elements rely on complex JavaScript to load or require user interaction to initialize the player.
Within a standard sitemap
<url>
entry, each video requires a
<video:video>
parent tag. This element groups the specific metadata for a single video asset. If a single page hosts multiple distinct videos, multiple
<video:video>
blocks can be nested under the same
<loc>
tag.
A valid video entry must include several specific child tags to be processed successfully:
-
<video:title>: The title of the video. -
<video:description>: A text description summarizing the video content. -
<video:thumbnail_loc>: A direct URL to an image file that serves as the video thumbnail. Search engines require a valid, crawlable thumbnail image to generate a video snippet in search results.
In addition to descriptive text and a thumbnail, the namespace requires at least one location tag to identify where the video content resides. An implementation must provide either
<video:content_loc>
or
<video:player_loc>
.
-
<video:content_loc>specifies the direct URL of the raw media file, such as an .mp4 or .webm file. This is the preferred method when videos are self-hosted or served directly from a content delivery network where the exact file path is known. -
<video:player_loc>provides a URL pointing to a standalone video player. This tag is commonly used when embedding videos via iframes from third-party platforms that obscure the raw media file path behind a player interface.
While only one location tag is strictly required, providing both is acceptable if both URLs are accessible. Supplying accurate location and textual data ensures that indexers can reliably associate the media asset with the page URL without waiting for full client-side execution.
Preventing the mismatched metadata failure mode
When a website implements both a Video Sitemap and on-page JSON-LD
VideoObject
structured data, search engines cross-reference the two data sources during the crawl. Because both mechanisms describe the exact same media asset, their metadata must align. Discrepancies between the XML namespace and the on-page schema create a conflicted signal, which frequently results in media indexing failures.
A mismatch occurs when the values provided in the sitemap contradict the values found in the HTML markup. When indexers detect these contradictions, they may lose confidence in the accuracy of the provided data. This can lead to XML validation warnings, the loss of rich result eligibility, or the complete exclusion of the video from media-specific search features.
Common points of metadata conflict
Metadata synchronization issues most often arise in complex content management systems when page templates and sitemap generators rely on different database queries or caching layers. The following table illustrates the required alignment between XML sitemap tags and their JSON-LD equivalents.
| Sitemap Element | JSON-LD Property | Synchronization Requirement |
|---|---|---|
<video:title>
|
name
|
Must contain the exact same text string. Discrepancies often occur if one output truncates the title for length while the other does not. |
<video:duration>
|
duration
|
Must represent the same total length. The XML tag requires an integer representing total seconds, whereas JSON-LD uses the ISO 8601 format (e.g., PT2M30S). The underlying time value must match perfectly. |
<video:publication_date>
|
uploadDate
|
Must resolve to the exact same date and time. Mismatches frequently stem from one system outputting a local timezone while the other outputs UTC. |
<video:thumbnail_loc>
|
thumbnailUrl
|
Must use identical URL strings. Variations in the protocol (HTTP vs. HTTPS), trailing slashes, or tracking parameters will be treated as conflicting declarations. |
Steps to synchronize media metadata
Preventing these conflicts requires aligning the data pipelines that generate the sitemap and the page-level markup. Implement the following practices to maintain synchronization:
- Establish a single source of truth: Configure both the sitemap generation script and the frontend template rendering engine to pull from the exact same media database fields. Avoid hardcoding default values in one location while pulling dynamic values in another.
- Standardize URL output: Normalize all media URLs before writing them to the XML or JSON-LD outputs. Ensure that image optimization parameters, CDN subdomains, and file extensions match character for character across both environments.
- Centralize format conversion: When converting a single duration integer from the database into the required XML and JSON-LD formats, handle the conversion in a shared utility function. This prevents rounding errors that can occur when the sitemap and the schema calculate the time differently.
-
Audit rendering pipelines: When pages rely on client-side JavaScript to inject the
VideoObjectschema, ensure the injected values still match the static XML sitemap data. Delays or modifications introduced by the client-side execution can inadvertently alter the schema, creating a mismatch once the page is fully rendered.
SEO structure and reciprocal link analyzer
Detect orphan pages, deep click depths, and toxic reciprocal links built by careless agencies.
Validating media indexing in search console
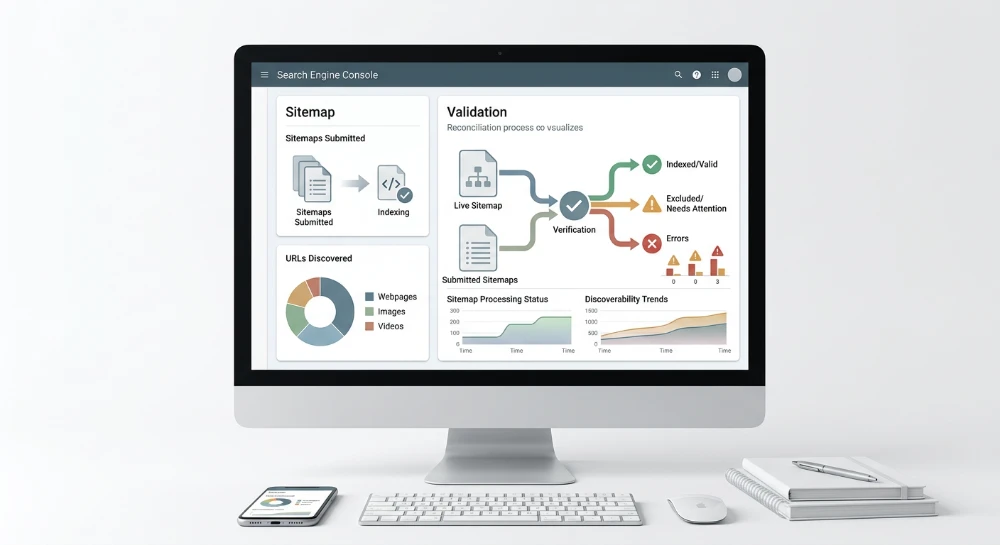
After deploying media sitemaps, validation shifts to Google Search Console. This process involves two distinct stages: confirming that the XML syntax is correct and verifying that search engines can successfully process the media assets found on the submitted pages.
Reviewing namespace validation in the sitemaps report
The Sitemaps report provides immediate feedback on XML parsing. When an image or video sitemap is submitted, the initial status indicates whether the file adheres to the required namespace schema. If a required tag is omitted-such as a missing
<video:thumbnail_loc>
or an improperly nested
<image:loc>
-the report will flag the specific line causing the parsing failure.
A "Success" status in the Sitemaps report only confirms that the file structure is valid and the URLs have been queued for crawling. It does not indicate that the media elements themselves have been successfully indexed.
Monitoring the video indexing report
For video content, the Video Indexing report tracks pages where a video was detected. This report categorizes URLs into "Video indexed" and "No video indexed" statuses. A page moves into the "No video indexed" category when a crawler detects the presence of a video-either through on-page HTML, schema markup, or a video sitemap-but encounters a technical barrier preventing extraction.
When investigating URLs in the "No video indexed" category, review the specific error reasons provided. Two frequent failure modes directly relate to metadata access and configuration:
-
Thumbnail missing or invalid:
Search engines require a valid thumbnail image to index a video. If the URL provided in the
<video:thumbnail_loc>tag returns a 404, is blocked by a robots.txt rule, or requires authentication, the video cannot be indexed. Verify that the thumbnail URL is publicly accessible, responds with a 200 HTTP status, and uses a supported image format. -
Unsupported video format or missing player:
This error occurs when the crawler cannot access the actual video file or the player context. If relying on
<video:player_loc>, verify that the URL points directly to a standalone player instance (such as an embed URL) rather than a standard webpage containing the player. If using<video:content_loc>, ensure the file extension represents a supported media format and that the host server is not blocking the crawler.
When resolving these errors, cross-reference the failed URL with the Live Test feature in the URL Inspection tool. The rendered HTML output can help determine whether client-side elements necessary for loading the player or thumbnail are successfully executing during the crawl, or if rendering timeouts are causing the media to appear missing to the indexer.