A News Sitemap is a specialized XML file designed to isolate time-sensitive articles for rapid discovery by Googlebot-news. Unlike a standard sitemap that catalogs the entirety of a website, a news-specific sitemap acts as a dedicated feed for freshly published content. This isolation helps search engines process breaking news and current events as quickly as possible.
The utility of a News Sitemap is strictly limited to publishers actively reporting on current events. It is not intended for standard corporate blogs, static reference pages, or evergreen content. Including non-news URLs or older articles in a news feed can generate validation errors and interfere with the reliable indexing of actual news coverage.
Because news indexing relies on immediate crawling, the technical requirements for these files are narrower than those of a standard XML sitemap. Proper implementation requires strict adherence to news-specific schema formats, precise publication timestamps, and restricted URL inclusion criteria to ensure that live reporting is eligible for news-specific search features without delay.
URL inclusion criteria and file limits
The defining characteristic of a News Sitemap is its restricted inclusion window. Only URLs for articles published within the last 48 hours belong in the file. Once an article passes this 48-hour threshold, it must be automatically removed from the News Sitemap. The article remains indexed via standard crawling and regular XML sitemaps, but its eligibility window for rapid news discovery has closed. Content management systems should be configured to maintain this rolling 48-hour window continuously to prevent older URLs from accumulating.
Strict adherence to this timeframe requires the complete exclusion of evergreen content. Static reference pages, standard blog posts, and older reporting must not populate the news feed. Attempting to force evergreen content into a News Sitemap-such as by artificially updating an older article's publication date without adding significant new reporting-can trigger validation errors and degrade the reliability of a publisher's news indexing.
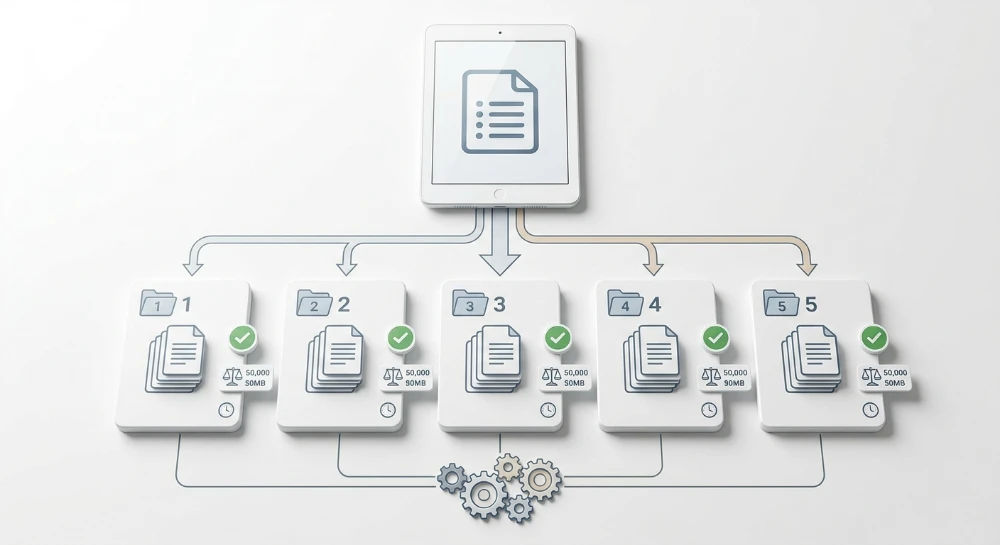
In addition to time constraints, News Sitemaps enforce a much smaller URL capacity limit than standard sitemaps. While a regular XML sitemap can hold up to 50,000 URLs, a single News Sitemap is strictly capped at 1,000 URLs. This restricted limit is intentional, minimizing file size and parsing overhead so search engine crawlers can ingest and process live reporting immediately.
High-volume publishers that generate more than 1,000 news articles within a 48-hour period must divide their coverage across multiple files. This is handled by creating several distinct News Sitemaps and grouping them together using a standard sitemap index file. Each individual sitemap referenced in the index must still adhere to the maximum limit of 1,000 URLs and only contain content published within the preceding two days.
Run a deep technical crawl to identify 4xx errors, missing meta tags, and indexation blockers.
Structuring the news sitemap schema
A News Sitemap functions by extending the standard XML sitemap protocol with a specialized namespace. To validate the news-specific tags, the file must declare the sitemap-news schema at the document root. The architecture relies on the standard
<urlset>
and
<url>
containers to encapsulate each article, with the base
<loc>
element providing the destination address.
The specialized metadata is introduced by nesting a
<news:news>
element directly inside each
<url>
block. This element serves as the wrapper for all news-related directives applied to that specific URL. If the
<news:news>
container is placed outside the
<url>
tag, or if the document fails to declare the news namespace, search engine parsers will process the file as a standard sitemap, ignoring the time-sensitive news directives entirely.
Configuring the publication container
Within the
<news:news>
wrapper, the first required element is the
<news:publication>
container. This block houses the publisher's core identifying details and mandates two child elements:
<news:name>
and
<news:language>
.
The
<news:name>
tag must exactly match the publication name registered in the Google Publisher Center. Mismatches in this specific field are a frequent cause of validation failure and rejected indexing. If the registered publication name is "Global Daily", submitting variations such as "The Global Daily", "Global Daily Inc", or "GlobalDaily.com" will generate a schema error. Capitalization, spacing, and punctuation within the
<news:name>
tag must align perfectly with the platform's configuration.
The
<news:language>
tag defines the primary language of the target article and requires a valid ISO 639 language code. Standard two-letter codes, such as
en
for English or
es
for Spanish, satisfy this requirement. For languages requiring regional specificity, supported regional variants are accepted, such as
zh-tw
for Traditional Chinese or
pt-br
for Brazilian Portuguese. The language code provided in the schema must correspond to the actual body text of the linked article.
Formatting publication dates and titles
The
<news:publication_date>
element specifies the exact time an article was published. This field requires the W3C Datetime format, which must include the year, month, day, and a specific time zone designator. Providing a full timestamp rather than just a date is standard practice for time-sensitive news content. A valid entry is formatted as
2023-11-15T14:30:00-05:00
for a specific offset, or
2023-11-15T19:30:00Z
for Coordinated Universal Time (UTC). Omitting the time zone designator or using an unsupported date string format will result in a schema validation error.
The timestamp in the News Sitemap must perfectly align with the date signals on the live article page. Timezone mismatches between the sitemap and the article page can invalidate the date entirely. If a content management system outputs the sitemap date in UTC but displays the visible page date or on-page structured data in a local time zone without a clear offset, the discrepancy can cause search engines to reject the provided publication time. Ensure that the timezone offset in the sitemap precisely matches the calculated time of the visible page timestamp.
The
<news:title>
element defines the headline of the submitted article. The text provided in this tag must contain the exact article page title as it appears on the live URL. Discrepancies between the sitemap title, the HTML title tag, and the visible on-page headline can confuse extraction systems and interfere with proper indexing.
When populating the
<news:title>
tag, supply only the pure headline. Do not append author names, publication branding, category names, or static boilerplate text. If the visible headline on the article page is "City Council Approves New Transit Budget", the sitemap title must mirror this string exactly. Submitting modified variations such as "City Council Approves New Transit Budget - Global Daily" violates the requirement for exact matching and can trigger a validation failure in the Publisher Center or Search Console.
Parse live Google SERPs, extract LSI entities, and write highly relevant articles.
Handling paywalls and content types with optional tags
Beyond the mandatory publication, date, and title elements, the news sitemap schema includes optional tags to classify gated access, article formats, and specific topics. These elements provide explicit context to crawlers regarding content boundaries and specialized reporting structures.
Defining content access boundaries
When an article requires users to sign up or pay before reading the full text, the
<news:access>
element clarifies this boundary. This tag accepts exactly two predefined values:
-
Registrationindicates that the content requires a free user account to view. -
Subscriptionindicates that the content requires a paid membership or metered paywall access.
Including the
<news:access>
tag accurately sets expectations for the crawler encountering gated text. It operates alongside on-page structured data to ensure paywalled articles are correctly understood as restricted access rather than flagged for cloaking.
Classifying content formats with genres
The
<news:genres>
element categorizes the structural format or nature of the article. It relies on a strict list of accepted string values. Common classifications include
OpEd
for opinion and editorial pieces,
PressRelease
for syndicated corporate announcements,
Blog
for informal publication entries, and
UserGenerated
for community-submitted content.
If an article fits multiple categories, the tag accepts a comma-separated list of exact-match values, such as
OpEd, Blog
. If a piece of content operates as standard news reporting and does not fit any of the predefined genre classifications, omit the
<news:genres>
tag entirely. Submitting unrecognized or custom genre strings will result in schema validation errors.
Topical categorization and financial entities
For niche reporting and specific topical categorization, the schema supports keyword and stock ticker elements. The
<news:keywords>
tag accepts a comma-separated list of terms detailing the primary subjects of the article, providing optional context for the topics covered.
For financial journalism, the
<news:stock_tickers>
element links an article directly to publicly traded companies mentioned prominently in the text. This tag requires a specific format combining the exchange prefix and the ticker symbol, separated by a colon. Valid implementations look like
NASDAQ:GOOG
or
NYSE:F
. Multiple tickers can be included using a comma-separated list. To maintain accurate categorization, restrict this tag to a small number of primary entities rather than listing every company incidentally mentioned in the reporting.
XML formatting and character encoding rules
News Sitemaps are evaluated against strict XML 1.0 parsing rules. The file must be generated using UTF-8 character encoding. A missing or mismatched encoding declaration can cause crawlers to reject the document entirely. The standard implementation requires the file to begin with an exact XML declaration specifying this encoding:
<?xml version="1.0" encoding="UTF-8"?>
.
The
<loc>
element requires a fully-qualified absolute URL. Relative paths or protocol-relative URLs (strings beginning with
//
) are invalid in sitemap schemas. The protocol, typically HTTPS, and the exact domain name must be explicitly declared, and the resulting string must match the canonical location of the published article.
Entity escaping for XML validation
The most common trigger for broken News Sitemap validation is the inclusion of unescaped characters within text nodes, particularly inside the
<news:title>
element. Article headlines routinely use ampersands, quotation marks, and other punctuation that conflict with reserved XML markup.
If a raw ampersand appears in a title string, such as "Finance & Trade", the XML parser interprets the character as the beginning of a markup entity. When it fails to find a valid closing semicolon, the parser throws a fatal error. Once a parsing error occurs, crawlers typically abandon the file, meaning any article URLs listed after the syntax error remain undiscovered during that crawl.
To ensure proper decoding, all reserved characters must be converted into their corresponding XML entity escape codes before the sitemap file is generated.
| Reserved Character | Name | XML Entity Escape Code |
|---|---|---|
&
|
Ampersand |
&
|
'
|
Single Quote / Apostrophe |
'
|
"
|
Double Quote |
"
|
>
|
Greater Than |
>
|
<
|
Less Than |
<
|
To prevent validation failures, a content management system's sitemap generation script must apply a strict entity-encoding function to all text outputs. Alternatively, text strings containing unescaped punctuation can be wrapped in
<![CDATA[ ... ]]>
sections. A CDATA section instructs the XML parser to treat the enclosed content strictly as character data, bypassing standard markup evaluation for that specific string.
Detect stealthy content rewrites, relevance drops, and injected spam links.
Submission, validation, and troubleshooting
Before submitting a news sitemap to a search engine, validate the file using an XML sitemap validator that supports the Google News extension namespace. Testing the file against the specific news schema catches underlying formatting errors, such as missing mandatory elements or invalid namespace declarations, before Googlebot attempts to parse a broken file.
Once the XML structure passes validation, submit the sitemap URL through the Sitemaps report in Google Search Console. Google Search Console evaluates news sitemaps using criteria distinct from standard sitemaps and provides diagnostic feedback specifically tailored to news schema requirements.
Common diagnostic scenarios
When monitoring the sitemap status in Google Search Console, administrators may encounter specific failure modes related to the news extension tags or the inclusion timeline.
Mismatched publication name
Google Search Console will return an immediate validation error if the text within the
<news:name>
element does not exactly match the publication name registered in the Google Publisher Center. This validation is strictly enforced. The string must account for exact capitalization, spacing, and punctuation. If the Publisher Center lists the publication as Example Daily News, submitting ExampleDailyNews or Example News in the sitemap will cause the URLs to be rejected.
Empty sitemap warnings
An Empty Sitemap status occurs when Googlebot crawls the file and finds zero valid URL entries. Because news sitemaps operate on a strict 48-hour inclusion window, the file can naturally become empty if a publisher does not release any new articles over a weekend or holiday.
However, a persistent empty warning during an active publishing cycle typically indicates a content management system failure. This usually happens when server-side caching prevents the sitemap from updating dynamically, or when the CMS database query fails to output recently published URLs into the XML file before the 48-hour threshold expires. To resolve this, configure the CMS or caching layer to bypass the news sitemap URL, ensuring the file generates a fresh list of recent articles upon every request.
Date and time errors
If the sitemap is successfully parsed but specific articles are flagged, the cause is often a formatting error in the timestamp. Google Search Console will report an error if the
<news:publication_date>
element lacks a valid time zone designator or if the timestamp format does not comply with the W3C standard. Verifying the server time configuration and the specific CMS time zone output can help isolate the root cause of these date validation failures.