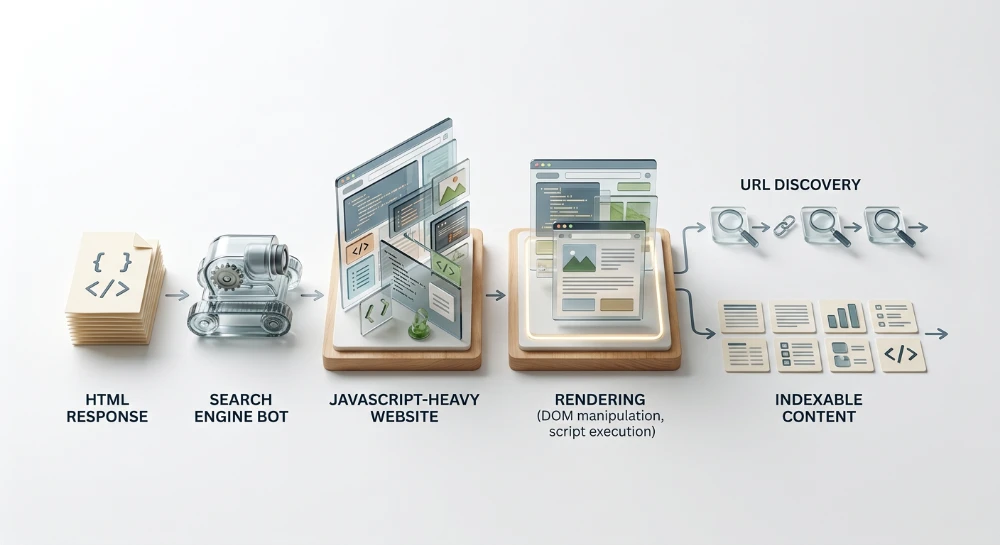
Server-side rendering (SSR) and static site generation (SSG) allow React applications to deliver complete HTML payloads directly to search engine crawlers. Once that markup reaches the browser, React performs hydration-using APIs like
hydrateRoot
to attach event listeners and component state to the existing server-rendered DOM nodes rather than building the document from scratch. However, React hydration problems can undermine the SEO benefits of server rendering when the initial client-side render pass produces a virtual DOM tree that does not match the server HTML.
When a hydration mismatch or unhandled runtime exception occurs during this handoff, React may discard portions of the server-rendered DOM and fall back to client-side re-rendering. For search engines that evaluate both the initial HTML response and the final rendered DOM, this fallback can result in missing body content, stripped internal links, or altered metadata if client-side execution fails or overwrites the server output. Even when hydration succeeds without structural errors, executing large JavaScript bundles to hydrate the entire page at once can block the main thread, contributing to layout shifts and degraded responsiveness metrics.
Maintaining search visibility in a server-rendered React architecture requires ensuring that the initial client render is deterministic and matches the server payload. Resolving these rendering issues involves auditing the differences between raw server HTML and the post-hydration DOM, isolating code patterns that rely on browser-only APIs or invalid HTML nesting, and applying rendering strategies that keep primary content and navigation intact for crawlers while deferring client-specific logic.
How hydration mechanics affect search engine crawling and rendering
When a browser or search crawler requests a server-side rendered (SSR) or statically generated (SSG) React page, it receives a complete HTML document before any client-side JavaScript executes. Once the JavaScript bundles download and execute, React initiates hydration reconciliation. During this pass, React constructs a virtual DOM tree in memory by running the component code on the client and compares that tree node-by-node against the existing server-rendered DOM.
React expects the initial client-side virtual DOM to be identical to the server HTML. When the trees match, React attaches event listeners and internal state references to the existing DOM nodes without altering the document structure. However, if the client-side render pass produces different element types, missing nodes, or conflicting attributes, a hydration mismatch occurs. When React detects a structural mismatch, it logs a runtime error, discards the affected server-rendered DOM subtree up to the nearest Suspense boundary or root container, and falls back to client-side rendering to rebuild that section from scratch.
Two-Stage search engine processing
Search engines that execute JavaScript, such as Googlebot via its Web Rendering Service (WRS), process SSR and SSG React pages in two distinct stages:
-
Initial HTML parsing: The crawler fetches the HTTP response and parses the raw server-rendered HTML payload. At this stage, the search engine extracts metadata from the
<head>, discovers crawlable<a href>links for the crawl queue, and processes the initial body text. - Headless browser rendering: The page is queued for rendering in a headless Chromium environment. Once the rendering service executes the page's JavaScript, React runs its hydration pass. The search engine then captures the final post-hydration DOM and evaluates it alongside the initial HTML.
Other search crawlers, automated bots, and social media link preview generators may not execute JavaScript at all, relying exclusively on the initial HTML payload. Because different crawlers-and different pipeline stages within the same search engine-inspect the document before and after JavaScript execution, discrepancies introduced during hydration create operational risks for indexing consistency and page experience metrics.
Content and link discrepancies
When a hydration mismatch forces React to tear down the server DOM and re-render on the client, the final rendered DOM remains intact only if the client-side fallback succeeds. If the client-side re-render encounters an unhandled JavaScript exception, a failed network dependency, or an API timeout within the headless browser, React may unmount the component tree entirely or render an error boundary fallback.
In this scenario, primary body copy, structured data scripts, or internal
<a href>
navigation links that were present in the initial server HTML are stripped from the final rendered DOM. For search engines that prioritize the rendered DOM for indexing, an unhandled failure during hydration recovery can cause the page to be evaluated as empty or incomplete, even though the server delivered valid markup.
Conversely, if developers bypass hydration mismatches by withholding primary content or navigation links from the server render and injecting them only after the component mounts on the client, those elements are absent during initial HTML parsing. While a headless renderer may eventually discover them, deferring crawlable links or core text to the client delays discovery and leaves non-JavaScript crawlers with an incomplete document.
Metadata inconsistencies
Hydration state changes can also alter document metadata inside the
<head>
. When client-side routing libraries or state managers initialize during hydration, poorly configured head-management logic may overwrite server-rendered
<title>
,
<meta name="robots">
, or
<link rel="canonical">
tags with default values or empty strings.
If the server HTML specifies an indexable canonical URL, but a client-side hydration pass injects a conflicting canonical target or a
noindex
directive while waiting for an asynchronous client state to resolve, the search engine receives contradictory signals between the initial crawl and the rendered snapshot. Search engines generally honor the most restrictive directive or may select an unintended canonical URL if the post-hydration DOM overrides the server configuration.
Main-Thread blocking and core web vitals
Even when hydration completes without mismatches, the reconciliation process carries a computational cost that affects page experience metrics. Hydrating a large application requires parsing, compiling, and executing the JavaScript for the entire component tree on the browser's main thread. This creates a period where the server-rendered HTML is visible on screen, but the page cannot respond to user input because event listeners are not yet attached and the main thread is occupied.
| Hydration Behavior | Browser Execution Impact | Affected Performance Metric |
|---|---|---|
| Monolithic hydration of a large component tree | Long tasks occupy the main thread during startup, delaying event handler execution when a user attempts to click or tap | Interaction to Next Paint (INP) in field data and Total Blocking Time (TBT) in lab diagnostics |
| DOM teardown and client-side re-render after a mismatch | The browser destroys visible server nodes and recalculates layout as replacement client nodes mount asynchronously | Cumulative Layout Shift (CLS) if replacement nodes alter document dimensions without reserved space |
| Hero element replaced during mismatch recovery | The largest visible text block or image in the server HTML is removed and repainted after JavaScript execution | Largest Contentful Paint (LCP), as the browser resets the LCP candidate timing to the later client-rendered node |
These performance degradations do not trigger automatic ranking penalties on their own, nor does a minor text mismatch in a non-critical UI widget prevent a page from being indexed. The operational priority is to determine whether hydration behavior alters the indexable content, strips navigational links, mutates indexing directives in the rendered DOM, or pushes Core Web Vitals metrics past the thresholds evaluated in real-user field data.
Run a deep technical crawl to identify 4xx errors, missing meta tags, and indexation blockers.
Common causes of react hydration mismatches and missing content
A hydration mismatch occurs whenever a component's initial execution in the browser produces a virtual DOM tree that differs from the HTML string generated on the server. React expects the first client render pass to be identical to the server render pass. When evaluating these failures for SEO, it is necessary to distinguish between minor text content mismatches and structural DOM mismatches.
A text content or single-attribute mismatch-such as a timestamp shifting by a few seconds-typically causes React to log a warning and patch the text node or attribute in place without destroying the surrounding markup. A structural DOM mismatch-where element types, tag nesting, or child node counts diverge-is much more disruptive. It forces React to abandon the server-rendered DOM subtree and re-render that portion of the tree on the client. If an unhandled exception occurs during this client fallback, or if the client logic intentionally omits markup that was present on the server, indexable text and crawlable links can disappear from the rendered DOM.
Browser-Only APIs executed during the initial render pass
The most frequent cause of structural mismatches is branching render logic based on browser globals such as
window
,
document
,
navigator
, or
localStorage
directly inside the component body. Because these APIs do not exist in a Node.js server environment, developers often guard them with a type check during render.
function NavigationMenu() {
  // Anti-pattern: branching return markup during the initial render pass
  if (typeof window !== 'undefined' && window.innerWidth < 768) {
    return <MobileDrawer />;
  }
  return <DesktopNavLinks />;
}
On the server,
typeof window !== 'undefined'
evaluates to
false
, so the server HTML always contains the markup for
DesktopNavLinks
. When the page loads in a mobile browser or a mobile-configured search crawler such as Googlebot Smartphone,
window.innerWidth
is evaluated during the initial client render pass, causing the component to return
MobileDrawer
. React expects the desktop markup from the server HTML, encounters the mobile component tree instead, and triggers a structural hydration mismatch.
The reverse anti-pattern is equally problematic for search visibility: returning
null
when
typeof window === 'undefined'
. While returning
null
on the server and also returning
null
before a client state update avoids a console warning, doing a direct environment check in the return statement sends an empty container in the initial HTTP response and forces a mismatch as soon as the browser attempts to hydrate the populated component.
Non-Deterministic values and environment discrepancies
Components that generate values on the fly or rely on system environment settings will produce different outputs on the server and the client even when executing the exact same code path. Common triggers include:
-
Calling
Math.random()or generating non-deterministic UUIDs for elementidorkeyattributes during render. -
Rendering current timestamps via
Date.now()ornew Date(), which advance during the network transit time between server execution and client script execution. -
Formatting dates, currencies, or numbers using
toLocaleDateString()orIntl.DateTimeFormatwithout explicitly passing both a locale string and atimeZoneoption.
function ArticlePublishDate({ isoDateString }) {
  // Mismatch risk: relies on the execution environment's default timezone and locale
  const formatted = new Date(isoDateString).toLocaleDateString();
  return <span>Published on {formatted}</span>;
}
A Node.js server usually runs in UTC, whereas a user's browser or a headless rendering instance may operate in a local timezone such as
America/Los_Angeles
. An evening timestamp in UTC can resolve to the previous calendar day on the client. While date formatting differences inside a text node usually result in a minor text mismatch, using non-deterministic values to conditionally render elements (such as showing a promotional banner based on local client hours) escalates the discrepancy into a structural DOM mismatch.
Invalid HTML nesting and browser parser corrections
Hydration mismatches can happen even when the server and client React code are completely deterministic. JSX compiles to JavaScript function calls that do not enforce HTML5 content model rules on the server. When the server serializes invalid HTML nesting into a response string, the browser's native HTML parser automatically mutates the markup to make it spec-compliant as it constructs the initial DOM tree-before React's
hydrateRoot
ever executes.
function ProductDescription() {
  // Invalid HTML: a block-level <div> inside a <p> element
  return (
    <p>
      Product specifications:
      <div>Weight: 1.2 kg</div>
    </p>
  );
}
According to the HTML specification, a
<p>
element cannot contain block-level elements like
<div>
,
<ul>
, or
<h3>
. When the browser parses the server string
<p>Product specifications:<div>Weight: 1.2 kg</div></p>
, it implicitly closes the first paragraph tag before opening the division, turning the actual DOM into:
<p>Product specifications:</p>
<div>Weight: 1.2 kg</div>
<p></p>
When React initializes on the client, its virtual DOM still expects the
<div>
to be a child of the
<p>
tag, whereas the browser DOM now has them as siblings. Other common parser-corrected structures include placing a
<tr>
directly inside a
<table>
without an intermediate
<tbody>
(which the browser automatically inserts) and nesting an interactive
<a>
tag inside another
<a>
tag. In each case, the browser's silent repair breaks React's node traversal during hydration.
External DOM mutations before hydration completes
Because hydration relies on the server HTML remaining untouched until the JavaScript bundle downloads, parses, and executes, any external system that alters the DOM or HTML payload in transit can cause reconciliation failures.
| External Mutation Source | Mechanism of DOM Alteration | Hydration Impact |
|---|---|---|
| CDN HTML Minifiers and Optimizers | Edge features that strip HTML comments or collapse whitespace between inline elements |
React relies on specific comment nodes (such as
<!--$-->
) to mark Suspense boundaries and separated text nodes; removing them breaks internal node pointers during hydration
|
| Synchronous Third-Party Scripts and Tag Managers |
Scripts in the
<head>
executing before the React bundle and injecting banners, A/B testing variants, or tracking pixels directly into the React root container
|
React encounters unexpected child nodes when walking the root tree, triggering a structural mismatch and potentially wiping out the injected or server-rendered nodes |
| CDN Email Obfuscation or Security Rewriters | Edge proxies replacing plain-text email addresses inside components with custom script tags and encoded links | The client virtual DOM expects a standard text node or anchor tag, colliding with the proxy-injected script element |
Unlike browser extensions-which often inject DOM nodes that trigger hydration errors in a developer's local browser or real-user monitoring logs without affecting search engines-mutations caused by CDN optimisers, edge workers, and synchronous third-party scripts execute during every page load. These infrastructure-level mutations alter the exact DOM inspected by search engine rendering services.
Diagnostic workflow: Auditing hydration errors and DOM discrepancies
Because React often recovers from hydration mismatches by discarding the server-rendered DOM subtree and re-rendering on the client, a page can look visually complete in a browser while still presenting inconsistent markup or degraded performance to search engines. Auditing a React application requires verifying the initial server payload, tracing component-level warnings in the browser, and confirming how search engine crawlers process the final output.
Step 1: Compare initial server HTML against the hydrated DOM
The first diagnostic check determines whether SEO-critical elements remain consistent before and after JavaScript execution. Fetch the raw HTTP response using
curl
or the browser's View Page Source feature, and compare that markup against the live DOM tree in the Chrome DevTools Elements panel (Inspect Element) after the page finishes hydrating.
Audit the following elements across both states:
-
<head>metadata: Verify that the<title>,<meta name="description">,<meta name="robots">, and<link rel="canonical">tags match. A common failure mode occurs when client-side state management or routing libraries overwrite server-rendered canonical tags or inject conflictingnoindexdirectives during hydration. -
Primary body copy and headings: Confirm that the main text and heading hierarchy (
<h1>through<h6>) present in the raw HTML are not wiped out or replaced with loading skeletons during a client-side fallback render. -
Crawlable links: Check that navigation menus, pagination, and internal links exist as standard
<a href="...">elements in both the raw HTML and the hydrated DOM, rather than being replaced by non-anchor elements relying on JavaScript click handlers. - Structured data: Ensure JSON-LD scripts present in the server response remain intact and are not duplicated or stripped when client components mount.
To isolate whether a component is failing during hydration, disable JavaScript in Chrome DevTools, reload the page to observe the exact server-rendered baseline, and then re-enable JavaScript. If content flashes, shifts, or disappears as the bundle executes, a hydration mismatch or destructive client-side state update is occurring.
Step 2: Inspect console logs and component stack traces
When the server HTML and client virtual DOM diverge, React logs warnings in the browser console. Open the Chrome DevTools Console and reload the target URL while preserving logs.
In production builds, React minimizes error messages to reduce bundle size, typically outputting condensed error codes (such as Minified React error #418, #422, or #425). While these codes confirm that a hydration mismatch occurred, they do not directly reveal which DOM node or component caused the failure. To pinpoint the offending code, run the audit against a local or staging development build, or configure Chrome DevTools to load production source maps.
In a development environment, React outputs a detailed diff showing the expected server HTML alongside the client-rendered markup, accompanied by a component stack trace. Use the React Developer Tools browser extension (Components tab) to inspect the component tree at the bottom of that stack trace. Look for components that read browser APIs during render, format dates without explicit locales, or render invalid HTML nesting. If the stack trace points to the root container rather than a specific child component, inspect the Network and Elements panels for third-party scripts or CDN features injecting nodes directly into the document before React initializes.
Step 3: Verify search engine rendering and performance impact
Local browser checks do not always reflect how a headless search crawler experiences the page, particularly when mismatches depend on user-agent strings, geographic IP locations, or network timing. Use Google Search Console's URL Inspection tool to verify how Googlebot processes the page.
- Enter the target URL into the URL Inspection tool and run a live test (Test Live URL) or inspect the currently indexed version (View Crawled Page).
- Open the HTML tab in the inspection results to view the rendered DOM captured after Google's rendering service executed JavaScript. Search this markup for primary content, internal links, and canonical tags to confirm that hydration recovery did not leave the page in an incomplete or errored state.
-
Check the More Info tab and review the Page resources and JavaScript console messages panels. Unhandled exceptions or hydration errors logged here indicate that the mismatch is actively occurring during Googlebot's rendering pass. If critical API calls or client-side fallback bundles are blocked by
robots.txtor fail to load before the renderer times out, a component that failed hydration may remain completely absent from the rendered HTML.
Finally, run a Lighthouse audit in Chrome DevTools with CPU throttling enabled (such as 4x slowdown) to measure the performance cost of the hydration pass. Inspect Total Blocking Time (TBT) and the Performance panel's Main thread flame chart. Long tasks during script evaluation and hydration reconciliation indicate heavy main-thread blocking that can degrade Interaction to Next Paint (INP) in field data. Simultaneously, check the Cumulative Layout Shift (CLS) metric and filmstrip view; if React tears down a mismatched server DOM subtree and re-renders it on the client, the resulting visual jump will register as a layout shift if the replacement nodes alter the page geometry.
Detect stealthy content rewrites, relevance drops, and injected spam links.
Implementation patterns for fixing hydration mismatches without hurting SEO
Resolving a hydration mismatch requires choosing between making the output deterministic on the server or deferring the divergent logic to the client. To protect search visibility during this process, apply a strict architectural decision rule: elements that crawlers rely on to understand and discover pages-primary body copy, headings, structured data, metadata, and internal navigation links-must render deterministically in the initial server HTML. User-specific states, browser-dependent widgets, and personalized UI should be deferred until after hydration completes so they do not corrupt or force a teardown of the surrounding server-rendered DOM.
Two-Pass rendering with useeffect and usestate
When a component relies on browser-only APIs like
localStorage
or
navigator
, two-pass rendering ensures the initial client render matches the server HTML before applying client-specific updates. During the server render and the first client render pass (hydration), the component returns a deterministic default state. Once hydration succeeds, a
useEffect
hook executes exclusively on the client, updates the state, and triggers a second, conventional client-side render.
import { useState, useEffect } from 'react';

export function UserLocationBanner({ defaultRegion }) {
  const [region, setRegion] = useState(defaultRegion);

  useEffect(() => {
    const savedRegion = window.localStorage.getItem('user_region');
    if (savedRegion && savedRegion !== defaultRegion) {
      setRegion(savedRegion);
    }
  }, [defaultRegion]);

  return (
    <div>
      <p>Showing availability for: {region}</p>
    </div>
  );
}
This pattern prevents React from discarding the server DOM tree, preserving any indexable fallback text provided by the server (such as
defaultRegion
above). However, it carries two specific trade-offs:
- Anything rendered exclusively during the second pass is absent from the initial HTTP response and will only be seen by search engines after JavaScript execution in the rendering queue.
-
If the component renders
nullon the first pass and injects a large DOM subtree insideuseEffect, the sudden expansion of the page geometry can cause a Cumulative Layout Shift (CLS). When deferring visual widgets, return a fixed-dimension skeleton or placeholder shell during the initial render pass to reserve the layout space.
Disabling Server-Side rendering for Client-Only components
When a third-party library or complex UI widget directly accesses
window
or
document
upon module import or initialization, two-pass rendering inside a wrapper may not prevent errors. Frameworks like Next.js allow developers to bypass server rendering entirely for specific components using dynamic imports with the
ssr: false
configuration.
import dynamic from 'next/dynamic';

const InteractiveMap = dynamic(() => import('./InteractiveMap'), {
  ssr: false,
  loading: () => <div>Loading map interface...</div>,
});
While disabling SSR eliminates hydration mismatches for that subtree, it completely removes the component's markup from the initial server HTML payload. Do not apply
ssr: false
to components containing primary article text, product descriptions, or internal linking structures (such as mega-menus or pagination). Reserve this pattern for non-indexable interactive utilities like map canvases, account dashboards, or client-side chart visualizers, and always provide a sized
loading
placeholder to prevent layout shifts when the chunk downloads and mounts.
Replacing JavaScript viewport checks with CSS media queries
Conditional rendering based on
window.innerWidth
or
window.matchMedia
is a common source of structural hydration failures, especially when a server assumes a desktop layout by default while mobile-first crawlers (like Googlebot smartphone) evaluate the page with a mobile viewport. Instead of branching JSX return statements in JavaScript, render a single, unified DOM structure on the server and control visual layout or element visibility through CSS media queries.
If mobile and desktop views require separate interactive containers, output both in the server HTML and toggle their display via CSS classes (for example,
display: none
and
display: block
across breakpoints). This guarantees that the initial client virtual DOM matches the server nodes regardless of the crawler's viewport dimensions, while keeping all text and links present in the static HTML source.
Scoping suppressHydrationWarning to text nodes
React provides the
suppressHydrationWarning={true}
prop for situations where a server-to-client discrepancy is unavoidable, such as rendering a localized relative timestamp or a dynamic counter that increments between the server build and client load.
<time dateTime={isoString} suppressHydrationWarning>
  {new Date(isoString).toLocaleTimeString()}
</time>
This attribute only suppresses warnings a single level deep and is designed exclusively for minor text or attribute differences that do not affect page semantics. It does not instruct React to patch or ignore structural DOM mismatches. If a component renders a
<div>
on the server and a
<span>
on the client,
suppressHydrationWarning
will not prevent a hydration failure or the subsequent client-side teardown. Never use it to silence console errors caused by broken HTML nesting or missing content blocks.
Preserving crawlable anchor tags during routing hydration
When refactoring navigation components to resolve hydration warnings-such as when nesting interactive elements causes invalid HTML errors like
<a>
inside
<a>
-developers sometimes replace anchor tags with
<div>
or
<button>
elements that trigger programmatic navigation via
onClick
handlers (e.g.,
router.push('/category')
).
Search engine crawlers discover internal URLs primarily by parsing standard
<a>
elements containing resolvable
href
attributes in the DOM; they generally do not synthesize click events on generic elements to discover navigation targets. Ensure that router link components always output a valid
<a href="...">
tag in the server HTML, and let React hydrate its client-side routing interceptors onto that existing anchor node rather than substituting non-semantic elements.
| Resolution Pattern | Initial Server HTML Output | Recommended Use Case | Primary SEO and UX Considerations |
|---|---|---|---|
Two-pass rendering (
useEffect
)
|
Renders deterministic default state or placeholder shell | User-specific UI, local storage preferences, localized formatting | Second-pass content requires JS execution to be seen; requires sized placeholders to avoid CLS. |
Dynamic import with
ssr: false
|
Omits component markup (renders optional loading fallback) | Browser-dependent third-party widgets, maps, authenticated tools | Markup is absent from initial HTML; unsuitable for primary copy, headings, or crawlable links. |
| CSS media queries | Renders complete markup for all viewports | Responsive navigation menus, viewport-dependent layouts | Avoids structural mismatches entirely; slightly increases initial HTML payload size if duplicating complex nodes. |
suppressHydrationWarning
|
Renders server text value | Unavoidable single-level text differences (e.g., local timestamps) | Works only one level deep; does not fix or prevent teardowns from structural DOM mismatches. |
Reducing hydration overhead with selective hydration and server components
Fixing individual component mismatches resolves immediate rendering errors, but complex pages still face the performance cost of hydrating large DOM trees all at once. In a standard server-side rendering setup, React must download the component code for the entire page and execute a single, synchronous hydration pass across the full virtual DOM tree before the interface becomes interactive. Modern React architectures reduce this main-thread burden through two complementary mechanisms: Selective Hydration via Suspense and React Server Components (RSC).
Incremental execution with suspense and selective hydration
Wrapping distinct, non-critical, or heavy page sections in
<Suspense>
boundaries changes how React schedules hydration on the client. Instead of treating the document as a single monolithic tree that must hydrate in one continuous task, React breaks hydration into smaller, independent work units aligned with each boundary.
import { Suspense } from 'react';
import PrimaryArticleContent from './PrimaryArticleContent';
import InteractiveProductFilter from './InteractiveProductFilter';
import RelatedDiscussions from './RelatedDiscussions';

export default function ProductGuidePage() {
  return (
    <main>
      {/* Hydrates immediately with the initial page shell */}
      <PrimaryArticleContent />

      {/* Hydrates independently without blocking the main article */}
      <Suspense fallback={<div>Loading filters...</div>}>
        <InteractiveProductFilter />
      </Suspense>

      <Suspense fallback={<div>Loading discussions...</div>}>
        <RelatedDiscussions />
      </Suspense>
    </main>
  );
}
When components are segmented this way, React can yield to the main thread between boundaries and prioritize execution based on user input. If a user clicks or taps inside
<RelatedDiscussions />
while
<InteractiveProductFilter />
is still hydrating, React interrupts the lower-priority hydration pass, hydrates the targeted component boundary first, and replays the captured interaction event. By preventing long, uninterrupted tasks on the main thread, selective hydration helps reduce input delay during page startup and supports healthier Interaction to Next Paint (INP) scores.
From an SEO perspective, placing a component inside a
<Suspense>
boundary does not mean hiding its content from search engines, provided the server-side rendering pipeline is configured accurately. When using streaming SSR, the server can still resolve the data and emit the complete HTML for the suspended component within the initial HTTP response stream. However, if a component is configured to fetch data exclusively on the client after mounting, the initial HTML response will contain only the
fallback
node. For sections containing primary copy or internal crawlable links, ensure the server resolves the boundary before closing the stream, using
<Suspense>
strictly to break up client-side JavaScript execution rather than deferring HTML generation to the browser.
Eliminating hydration for static content with react server components
While Selective Hydration schedules client-side work more efficiently, React Server Components remove non-interactive components from the hydration lifecycle entirely. Traditional SSR and RSC often operate together in modern frameworks, but they serve different architectural roles:
- Traditional SSR executes components on the server to generate initial HTML, then sends the JavaScript for those same components to the browser so they can run again during hydration.
- React Server Components execute exclusively on the server, serialize their rendered output, and send zero component JavaScript to the client bundle. Because their code never ships to the browser, Server Components never hydrate.
This architecture directly addresses both main-thread congestion and hydration mismatches on content-heavy templates. Static elements-such as long-form article bodies, product specification tables, footer link directories, and JSON-LD structured data scripts-do not require event listeners or client-side state. Rendering these sections as Server Components means React does not run a client-side reconciliation pass over their DOM nodes. Consequently, timezone discrepancies, locale formatting differences, or third-party browser extensions that modify text inside a Server Component's rendered HTML will not trigger React hydration warnings or force a client-side DOM teardown.
Structuring client boundaries around interactive islands
In an RSC architecture, hydration is opt-in and controlled via the
'use client'
directive. When a file declares
'use client'
at the top, that component and all modules imported into it become part of the client bundle and undergo standard SSR and hydration.
To keep the hydration surface area minimal, place
'use client'
boundaries at the leaves of the component tree rather than near the page root:
- Keep the page layout, primary headings, body text, and navigation links inside Server Components so their HTML is delivered with zero hydration overhead.
- Extract stateful UI elements-such as an "Add to Cart" button, an image carousel toggle, or a search input with autocomplete-into dedicated Client Components.
-
When a Client Component needs to wrap static, SEO-relevant content (for example, an interactive collapsible drawer or tab container that holds crawlable text), pass the Server Component through the Client Component using the
childrenprop rather than importing the static content directly into the client file.
// Server Component (Page.jsx) - Zero client JS, no hydration
import ExpandablePanel from './ExpandablePanel'; // Client Component
import ProductSpecifications from './ProductSpecifications'; // Server Component

export default function ProductPage({ data }) {
  return (
    <article>
      <h1>{data.title}</h1>
      <ExpandablePanel title="Technical Specifications">
        <ProductSpecifications specs={data.specs} />
      </ExpandablePanel>
    </article>
  );
}
By passing
<ProductSpecifications />
as
children
, React evaluates the specification table on the server and passes only the serialized result to the client boundary. The browser hydrates only the wrapper's toggle state in
<ExpandablePanel />
, leaving the inner specification markup untouched in the DOM and immune to client-side hydration failures.