Migrating a website from HTTP to HTTPS fundamentally alters every URL in its architecture. Because search engines treat different protocols as entirely distinct web addresses, a protocol change carries the immediate risk of fragmenting historical indexing signals or causing pages to temporarily drop from search results. Protecting legacy URL indexation during protocol changes requires a deliberate technical transition to shift crawling and indexing strictly to the secure channel.
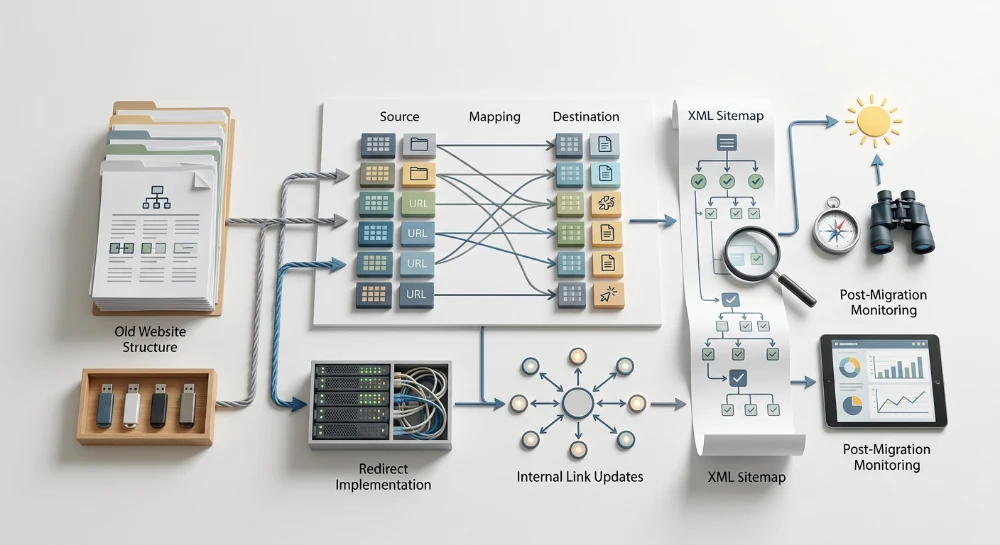
Preserving these legacy signals depends on maintaining an exact 1-to-1 relationship between the old HTTP pages and their new HTTPS counterparts. Search engines rely on explicit server-side directives to understand that the content has moved permanently. Without precise mapping, crawlers may fail to transfer the historical context of the legacy URLs, or they may temporarily misinterpret the newly discovered secure URLs as duplicate content.
A successful protocol migration aligns technical signals to guide crawlers through the shift without ambiguity. By pairing permanent server-side redirects with updated canonical tags and secure internal links, technical teams can consolidate indexation on the new URLs and prevent search engines from dividing their evaluation across two parallel protocol versions.
Implementing 1-to-1 Server-Side redirects
Transitioning search indexation from an insecure protocol to a secure one requires explicit server-side instructions. Permanent redirects, utilizing either the HTTP 301 or HTTP 308 status codes, signal to web crawlers that a resource has moved permanently to a new address. For a protocol migration to succeed without indexation gaps, every legacy HTTP URL must redirect directly to its exact HTTPS equivalent. This strict 1-to-1 mapping preserves the context, site hierarchy, and historical relevance of individual pages.
While HTTP 301 is the traditional standard for permanent redirection, HTTP 308 performs the exact same function for search engine crawlers while strictly preserving the original HTTP request method, preventing a POST request from automatically converting into a GET request. Both status codes successfully transfer indexing signals when implemented accurately.
Site-Wide protocol enforcement
Implementing individual redirects for thousands of URLs is highly inefficient and prone to human error. Instead, web servers handle protocol redirection globally using rewrite rules that dynamically replace the scheme while preserving the exact URL path and query string. This method guarantees that a request for an old resource resolves to the corresponding secure URL without requiring a manual mapping table.
In Apache server environments, administrators typically enforce this global rule within the .htaccess file or the virtual host configuration using the rewrite module. A standard configuration intercepts all traffic occurring over port 80 and appends the requested path to the secure host name.
RewriteEngine On
RewriteCond %{HTTPS} off
RewriteRule ^(.*)$ https://%{HTTP_HOST}%{REQUEST_URI} [L,R=301]
For servers running Nginx, protocol redirection is established by configuring a separate server block that listens specifically for HTTP traffic. This block issues a permanent redirect instruction using the Nginx return directive, capturing the requested URI and appending it to the secure scheme.
server {
    listen 80;
    server_name example.com www.example.com;
    return 301 https://$host$request_uri;
}
Avoiding soft 404s from blanket redirects
A common architectural failure during protocol migrations is routing all legacy HTTP traffic to the secure homepage rather than maintaining specific URL paths. This approach destroys the 1-to-1 relationship between legacy and secure pages. When search engines encounter hundreds of disparate URLs resolving to a single, unrelated destination, they do not transfer the indexing signals to the homepage.
Instead, crawlers classify these mismatched redirects as soft 404 errors. The search engine determines that the original specific content is no longer present at the destination, and it discards the historical signals associated with the legacy HTTP URLs. To maintain indexation continuity, the redirect destination must always serve the exact content that previously existed on the HTTP URL.
This requirement extends to the precise handling of trailing slashes and query parameters. If a legacy HTTP URL included query strings used for pagination, faceted navigation, or specific content rendering, the global redirect rule must append those exact parameters to the new HTTPS URL. Stripping query parameters during the redirect sequence creates the same signal fragmentation as routing deep pages to the site root, preventing search engines from recognizing the secure page as the definitive replacement.
Run a deep technical crawl to identify 4xx errors, missing meta tags, and indexation blockers.
Consolidating signals with canonical tags and internal links
While server-side redirects handle traffic routing, on-page signals must also align with the new protocol. The
rel="canonical"
link element on every page must be updated to reference the new HTTPS URL. During a protocol migration, search engines often discover both the legacy HTTP and the new HTTPS versions of a page before the redirect logic is fully processed across the crawl queue. Updating the canonical tag to the secure URL consolidates indexing signals and prevents the search engine from treating the two protocols as competing duplicate content.
Beyond canonical tags, the site architecture requires comprehensive updates to its absolute internal links. Any hardcoded HTTP URLs used in anchor tags and embedded resource references across navigation menus, body content, and footers must be rewritten to point directly to their HTTPS counterparts.
Updating these absolute URLs addresses three specific operational requirements during a migration:
- Avoiding internal redirect chains: Relying on the global server-side rule to fix legacy HTTP links forces crawlers through an unnecessary redirect hop for every internal page view, creating latency and reducing crawl efficiency.
- Preventing mixed content: If internal protocol references for page assets remain on HTTP while the main document loads over HTTPS, browsers trigger mixed content warnings. This blocks insecure resources from rendering and strips the browser's secure padlock icon, compromising secure channel trust.
- Reinforcing the primary signal: A uniform internal linking structure using HTTPS provides consistent context to search engines, confirming that the new secure protocol is the definitive, integrated replacement rather than a temporary alias.
Updating XML sitemaps and crawl directives
Because search engines treat HTTP and HTTPS as separate site properties, crawl directives and sitemap configurations must be explicitly updated for the new protocol. The transition relies on search engine crawlers accessing the legacy URLs to observe redirects and the new URLs to index the secure content.
Validating crawl access
The new HTTPS environment operates with its own robots.txt file. A frequent deployment failure occurs when a staging environment's robots.txt, which typically contains a global disallow directive, is inadvertently copied to the live secure host. The HTTPS robots.txt must be validated to ensure it permits crawling of the new URLs.
The robots.txt file on the legacy HTTP property must also remain accessible and permissive. If the HTTP robots.txt blocks crawling, search engines cannot access the legacy URLs to read the 301 redirects, preventing the transfer of indexing signals.
Configuring primary and legacy XML sitemaps
The primary XML Sitemap must be updated so it contains only the new HTTPS URLs. Including both protocols in the main sitemap provides conflicting instructions to search engines about which version of a page to index. All URL declarations within the sitemap files should use the secure protocol, and the sitemap directive in the robots.txt file must be updated to point to the secure sitemap path.
While the primary sitemap manages the new URLs, a secondary sitemap strategy can accelerate the migration process:
- Create a temporary, separate XML Sitemap containing only the legacy HTTP URLs.
- Submit this legacy sitemap to search engines through their respective webmaster portals alongside the new primary sitemap.
- Monitor the server logs or crawl reporting to verify search engines are processing the files.
Submitting the legacy HTTP sitemap explicitly queues those older paths for a recrawl. When the crawler fetches the legacy URLs from this temporary sitemap, it encounters the 301 redirects. This prompts the search engine to process the redirect mapping faster than it would by relying solely on standard, organic recrawl scheduling.
Once reporting confirms that the search engines have processed the redirects and the HTTP URLs have largely dropped from the index, the temporary legacy sitemap can be removed.
Bulk Google and Yandex index checker
Verify agency reports and track live SERP status in Google and Yandex to protect your SEO ROI.
Verifying re-indexing in Google search console
Tracking the transition from HTTP to HTTPS requires visibility into both protocol prefixes. Utilizing a Domain property in Google Search Console provides a unified view, aggregating reporting for all subdomains and protocols. If a Domain property is not configured, monitoring the migration requires manually comparing data between separate URL-prefix properties for the HTTP and HTTPS versions.
Validating redirects with the URL inspection tool
The URL Inspection Tool provides immediate diagnostic feedback on how Googlebot processes the redirect mapping for specific pages. Testing a sample of individual legacy URLs and their new secure counterparts confirms that the routing strategy is functioning at the crawler level.
When inspecting a legacy HTTP URL, request data from the live index. The tool should indicate that the URL is not indexed due to a redirect. Reviewing the detailed indexing card provides specific verification signals:
- Page fetch: This should indicate a successful crawl event where the crawler encountered the redirect status.
- Indexing status: The status should classify the old protocol page specifically as a Page with redirect.
- Google-selected canonical: The reporting interface should display the new HTTPS counterpart as the selected canonical URL, confirming that indexing signals are successfully consolidating to the secure channel.
Subsequently, inspecting the corresponding new HTTPS URL should show a successful fetch returning a 200 HTTP status code, confirming the secure page is indexed and eligible to serve in search results.
Tracking migration trends in the page indexing report
While the URL Inspection Tool validates individual mappings, the Page Indexing report tracks the macro-level progress of the protocol migration across the entire site architecture. During a successful transition, this report will reflect a gradual indexation swap as search engines schedule and process the redirected URLs over time.
In a Domain property view, evaluate the indexing trends for two distinct patterns:
- A steady, continuous decline in indexed legacy HTTP URLs. These URLs will move out of the Indexed category and populate the Not indexed category, specifically accumulating under the Page with redirect status.
- A corresponding, proportional increase in indexed HTTPS URLs moving into the Indexed status.
The timeframe required to complete this indexation swap depends on the total URL count, the site architecture, and the natural crawl frequency allocated to the domain. Pages positioned higher in the site hierarchy or updated frequently typically transition within days, while deeply nested historical pages may require weeks before the crawler fetches the legacy URL and processes the redirect mapping.
Troubleshooting redirect errors and TLS configurations
When executing a protocol migration, specific technical failures can stall the indexation transfer. If crawlers encounter friction when requesting legacy URLs or attempting to resolve the secure destination, the indexation swap remains incomplete.
Resolving redirect chains and loops
During a protocol update, overlapping server rules can unintentionally create redirect chains or infinite loops. A common chain occurs when a crawler requests a legacy URL and passes through multiple intermediate hops before reaching the secure destination, such as routing from HTTP non-www, to HTTP www, and finally to HTTPS. Each redirect hop introduces latency and reduces crawl efficiency.
If a chain is too long or loops infinitely, search engines will abandon the request before reaching the final destination. When a crawler drops the redirect path, the indexing signals from the legacy URL fail to transfer. Server-side redirect rules must be audited to ensure they route all legacy variations directly to the final secure URL in a single HTTP 301 response.
Preventing HTTP 404 mapping errors
Redirect mapping errors that terminate in an HTTP 404 (Not Found) response present another critical failure point. This typically happens when a legacy URL points to an HTTPS URL that was omitted from the new site architecture, or when a regex rule generates a malformed destination path.
When the crawler follows the redirect and encounters a 404 status, it determines the destination is invalid and drops it from the indexing pipeline. This failure severs the historical authority link established by the legacy URL, as the incoming signals have no valid active page to consolidate into.
Validating TLS certificate configuration
The successful indexation of the new protocol URLs relies entirely on a functional and trusted TLS configuration at the destination server. If the TLS certificate is expired, self-signed, missing intermediate certificates in its chain, or registered to a mismatched domain name, search engines may refuse to establish the secure connection.
When a crawler cannot validate the TLS certificate, it treats the new HTTPS URLs as inaccessible. This blocks crawling entirely on the secure channel. If the destination cannot be crawled, the search engine cannot verify the content or process the redirect, preventing the completion of the protocol migration until the certificate environment is corrected.