Planning redirects for a site migration is a required technical process whenever a website changes its domain, content management system, or URL structure. Without a deliberate routing strategy, legacy URLs will return 404 errors, breaking existing inbound links and disrupting search engine crawling. A precise redirect plan ensures that both users and automated crawlers are seamlessly forwarded from outdated paths to the correct destinations on the new site.
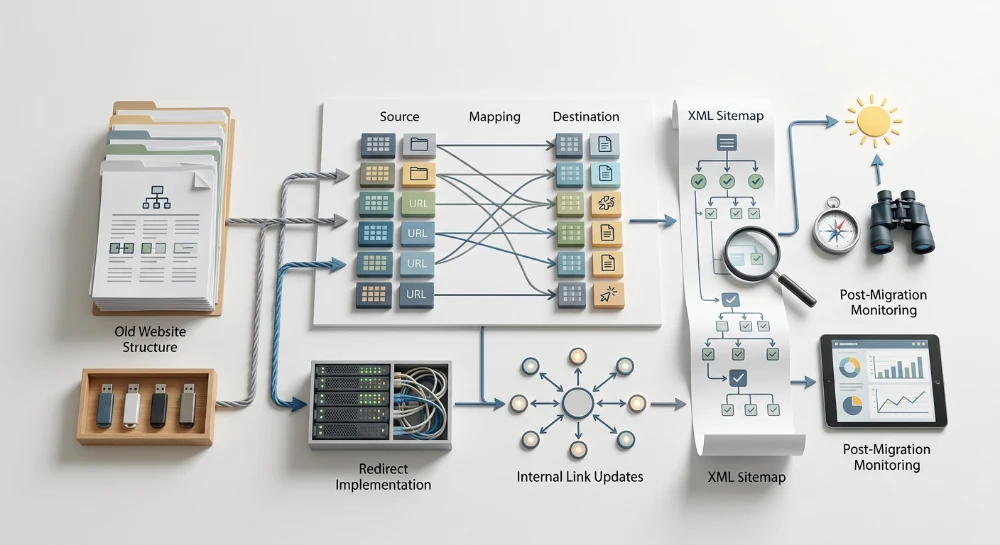
The foundation of this process is a comprehensive URL map that connects every legacy page to its closest equivalent on the production environment. While pattern-based rules can handle predictable structural shifts, many migrations require granular, one-to-one mapping to maintain content relevance. If legacy pages are redirected in bulk to generic destinations, such as the new homepage, search engines may treat these endpoints as soft 404 errors rather than valid indexing signals.
Beyond the mapping phase, a migration redirect strategy must account for the execution environment, prioritizing edge network or server-level permanent redirects over client-side alternatives. It is also necessary to distinguish between external URL resolution and internal site architecture. While migration redirects process incoming external requests, internal links must be explicitly updated to target the new indexable URLs, preventing unnecessary server load and reducing crawl delays across the updated domain.
URL inventory and redirect mapping
A successful migration redirect plan begins with a complete inventory of the legacy website's URLs. Because no single data source provides a comprehensive view of a site's footprint, an accurate audit requires aggregating data from multiple locations. Relying solely on a site crawler can leave orphaned pages undetected, while extracting URLs only from a CMS database may miss dynamically generated paths, query parameters, or legacy files still active on the server.
To capture all active and indexed paths, compile and deduplicate URL exports from the following sources:
- Current XML sitemaps and CMS page databases.
- Full-site crawl data to identify all internally linked paths.
- Landing page reports from web analytics platforms, utilizing an extended date range to capture seasonal or low-volume traffic.
- Google Search Console Page Indexing reports to identify all URLs currently known to the search engine.
- Server log files to uncover paths actively requested by external user agents, bots, or legacy system integrations.
Once aggregated and deduplicated, filter out URLs that currently return 404 or 410 status codes, unless a backlink analysis indicates they possess valuable external inbound links that should be reclaimed through the migration.
URL mapping strategies
After establishing the legacy URL inventory, every active path requires a destination URL on the production site. This mapping process generally follows two approaches depending on how the content architecture changes during the migration.
One-to-one mapping is the standard approach for pages that have a direct equivalent on the new site. If a product page, article, or category is moving to a new URL structure but retaining its core content and intent, the legacy URL maps directly to its newly structured counterpart. This granular approach provides the clearest signal to search engine crawlers that a specific document has permanently changed its location.
Many-to-one mapping applies when content is being consolidated or pruned. If multiple legacy pages are merged into a single comprehensive page, or if several highly specific category pages are collapsed into a broader parent category, their legacy URLs map to the unified destination. When employing many-to-one mapping, the destination page must adequately serve the intent of all the original legacy pages.
Destination relevance and soft 404s
The defining factor of a successful URL map is the contextual relevance of the destination URL. Search engines evaluate the relationship between the legacy content and the redirect target to determine how to process the redirect signal.
A common failure mode in migration planning is redirecting deprecated pages in bulk to the new homepage or a generic top-level category simply to avoid 404 errors. When a crawler encounters a redirect where the destination content differs significantly from the original page, it may classify the endpoint as a soft 404. Under this classification, the search engine treats the legacy URL as if it returns a standard 404 Not Found error, discarding the legacy indexing signals rather than transferring them to the mapped destination.
If a legacy page has no relevant equivalent on the new site and its content is not being consolidated, mapping it to an irrelevant destination provides no utility to users or search engines. In these cases, the technically correct procedure is to allow the legacy URL to return a 404 or 410 status code intentionally. Reserving redirects exclusively for relevant destinations ensures crawlers correctly process the URL updates and recognize the new structural relationships.
Run a deep technical crawl to identify 4xx errors, missing meta tags, and indexation blockers.
Implementing migration redirect rules
Permanent URL changes require permanent redirect signals. The standard response for a moved resource is the 301 Moved Permanently status code. A more recent alternative, the 308 Permanent Redirect, functions similarly for indexing purposes but handles client requests differently. When a client submits a POST request to a legacy URL, a 301 redirect may cause the client to convert the follow-up request to a GET method, potentially dropping form data or application payloads. A 308 redirect explicitly instructs the client to repeat the exact same request method at the new destination.
For standard page crawling where search engines rely entirely on GET requests, both codes successfully forward users and indexing signals. When a migration includes transactional endpoints, API routes, or form submissions, using 308 redirects preserves application state during the transition.
Exact-Match versus Pattern-Based rules
Redirect configurations scale through a combination of exact-match maps and pattern-based rules. The chosen method depends on how predictably the legacy URL structure aligns with the new architecture.
Exact-match rules explicitly state a single legacy path and its exact destination. This provides granular control and is necessary when URL structures change unpredictably or when multiple distinct pages consolidate into one. Because every URL requires its own distinct line in the server or network configuration, exact-match files can grow to tens of thousands of lines. Depending on the execution environment, parsing an excessively large exact-match list on every request can delay server response times.
Pattern-based rules utilize Regular Expressions (Regex) to intercept incoming requests that match a defined structural pattern, rewriting them dynamically using capturing groups. When an entire directory structure changes systematically, a single regex rule can handle thousands of URLs simultaneously.
While pattern-based rules reduce configuration size and overhead, they require strict syntax validation. An improperly scoped regex pattern can inadvertently capture unintended paths, causing false matches and broad site access issues. Migrations typically use pattern-based rules for structural directory changes and exact-match rules for the remaining individual URL updates.
Evaluating execution environments
The layer at which a redirect executes dictates its performance, scalability, and resource consumption. Implementing rules as close to the user as possible reduces latency and protects origin server resources.
Edge network redirects
Deploying redirects at the Content Delivery Network (CDN) or edge computing layer is the most efficient configuration for site migrations. When edge rules are active, the CDN intercepts the incoming request and returns the 301 or 308 status code before the request ever reaches the origin server.
This approach minimizes Time to First Byte (TTFB), completely isolates the origin server from legacy traffic load, and easily accommodates massive exact-match lists using edge key-value storage databases. When a migration involves millions of URLs or high traffic volume, edge execution prevents the legacy traffic from degrading the performance of the new production application.
Server-Level redirects
When edge execution is unavailable or cost-prohibitive, server-level rules are the standard implementation layer. These rules process at the origin server but execute before the application layer or CMS initializes, keeping them relatively fast.
In an Apache environment, pattern-based rules are typically deployed in the .htaccess file or the virtual host configuration.
RewriteEngine On
RewriteRule ^legacy-directory/(.*)$ /new-directory/$1 [R=301,L]
In an Nginx environment, redirect directives operate directly within the server block configuration.
rewrite ^/legacy-directory/(.*)$ /new-directory/$1 permanent;Processing complex regex or extremely long exact-match files at the server level requires the server to read and evaluate the rules against every incoming request. Under heavy load, this CPU consumption can impact the server's ability to process standard requests for the active site.
Client-Side redirects
Client-side methods, such as HTML meta refresh tags or JavaScript window location updates, execute entirely within the user's browser. A meta refresh requires the origin server to generate and send an HTML document containing the legacy page structure, after which the browser parses the meta tag and initiates a second request for the destination URL. JavaScript redirects require the browser to download, parse, and execute the script before transitioning.
These methods introduce severe latency, create a poor user experience, and force search engines to render the page to discover the destination. Because client-side execution depends on crawler rendering queues and browser behavior rather than direct HTTP headers, these methods are unreliable for passing indexing signals. Client-side redirects should be avoided during site migrations in favor of HTTP status codes executed at the edge or server level.
Managing query strings, chains, and loops
Standard URL paths map predictably, but dynamic parameters, trailing slashes, and overlapping rules require explicit configuration to prevent unintended routing behavior. Complex rule sets can introduce inefficiencies or complete resolution failures if not ordered and tested systematically.
Handling query string parameters
In many web server environments, such as Apache and Nginx, query strings appended to a requested URL are automatically appended to the redirect destination unless explicitly stripped. When migrating URLs, query strings often need to be matched to dictate the destination, or discarded if the new architecture no longer relies on them.
Matching query strings
Standard redirect directives typically match only the URL path, ignoring the query string. To redirect a specific dynamic URL to a static equivalent, the server must evaluate the query string independently. In Apache, this requires a condition directive prior to the rule.
RewriteCond %{QUERY_STRING} ^category=shoes$
RewriteRule ^products\.php$ /footwear/? [R=301,L]
Dropping query strings
When legacy parameters are no longer functional on the new site, allowing them to append to the destination creates duplicate URLs in the index and analytics platforms. To prevent the server from passing the existing query string to the destination, an explicit termination character must be used. In Apache, appending a question mark to the destination path instructs the server to drop the legacy parameters.
RewriteRule ^old-directory/$ /new-directory/? [R=301,L]If specific tracking parameters, such as UTM codes, must be preserved while other legacy application parameters are dropped, more complex regex capture groups and query string manipulation functions within the server configuration are required.
Trailing-Slash behavior
Search engine crawlers and web servers treat URLs with and without a trailing slash (e.g., /about and /about/) as distinct paths. Inconsistent handling during a migration can spawn duplicate paths and dilute indexing signals across two versions of every page.
Before implementing specific migration mapping rules, establish a global trailing-slash convention. If the production environment enforces a trailing slash, implement a global rewrite rule to append the slash to any incoming request lacking one, followed by a permanent redirect.
When configuring global trailing-slash rules, apply exceptions for files with explicit extensions to prevent breaking media or document URLs. A common method is using server conditions to check if the request maps to an existing file or directory before applying the trailing-slash redirect.
RewriteCond %{REQUEST_FILENAME} !-f
RewriteRule ^(.*[^/])$ /$1/ [R=301,L]
Placing global standardization rules before individual URL migration rules ensures that incoming requests are normalized before being evaluated against the specific redirect map.
Identifying and resolving redirect chains
A redirect chain occurs when a requested URL undergoes one or more intermediate redirects before arriving at the final HTTP 200 destination. This often happens when new migration redirects are stacked on top of rules from previous site updates.
Intermediate hops introduce unnecessary latency, degrading user experience and increasing the time required for search engines to process the URL transition. If a crawler encounters too many sequential hops, it may abandon the request before reaching the final destination.
To resolve chains, map all legacy URLs directly to the final production URL, regardless of their historical intermediate steps. If URL A previously redirected to URL B, and URL B is now migrating to URL C, update the rule for URL A to point directly to URL C.
Use bulk crawling tools configured to follow and report on redirect paths to audit the staging and production environments. Review the crawl export to identify any URL sequence exceeding a single hop. Command-line tools can also verify individual URL paths by requesting the HTTP headers.
curl -I -L https://example.com/legacy-urlThe output will display the full sequence of HTTP status codes and location headers, exposing any intermediate steps.
Detecting and fixing redirect loops
A redirect loop is a circular routing failure where a URL redirects to itself, or two URLs redirect to each other (e.g., URL A points to URL B, and URL B points back to URL A). Browsers and crawlers have maximum hop limits and will terminate the request, typically returning an ERR_TOO_MANY_REDIRECTS message.
Loops are commonly caused by:
- Overlapping regex patterns where the destination URL inadvertently matches the condition designed to catch the legacy URL.
- Conflicts between server-level directives and edge network (CDN) rules, such as a CDN enforcing HTTPS while the origin server enforces HTTP.
- Conflicting trailing-slash configurations where the web application strips the slash but the server configuration appends it.
To diagnose loops, disable the redirect rules in batches to isolate the conflicting directives. When using regex for bulk redirects, ensure the pattern explicitly excludes the destination directory to prevent the rule from triggering recursively. Evaluating the exact order of operations across all layers-CDN, load balancer, web server, and application logic-is necessary to identify where the routing logic contradicts itself.
SEO structure and reciprocal link analyzer
Detect orphan pages, deep click depths, and toxic reciprocal links built by careless agencies.
Updating internal links to target URLs
Server-side redirect rules are designed to handle external requests, processing inbound links, bookmarks, and search engine crawlers accessing legacy paths. While these rules ensure visitors reach the correct destination, relying on them for internal site navigation introduces architectural inefficiencies. Internal links must be explicitly updated to point directly to the new, indexable URLs.
Leaving legacy URLs in a site's navigation or body content forces browsers and crawlers to process an intermediate step for every internal click. When a user clicks an outdated link, the server or edge network must evaluate the request against the redirect rules, return a 301 or 308 HTTP status code, and wait for the client to request the new target URL. This sequence adds unnecessary network latency, increases server load during high-traffic periods, and requires search engine crawlers to expend request allocations on redirects rather than evaluating actual page content.
The process of updating internal links generally falls into two categories: template links and in-content links.
Template links reside in global elements such as headers, footers, sidebars, and primary navigation menus. Because these elements propagate across the entire site, a single outdated link in a footer can generate thousands of internal redirects. Updating the underlying theme files or CMS menu configurations resolves these site-wide redirect hops immediately.
In-content links are embedded within individual pages, articles, or product descriptions. Updating these requires modifying the database records. This is typically executed through a database search-and-replace operation or specialized command-line tools that can safely parse serialized data within the CMS. The operation targets the exact legacy URL strings and replaces them with the new production paths.
To verify the internal link update process, run a site crawler against the staging environment or the live site immediately after deployment. Configure the crawler to report on internal URLs and filter the results for links returning 3xx status codes. The output will map the specific source pages that still contain outdated references, allowing developers to isolate and update the remaining legacy links directly at the source.
Sitemap strategy for migrations
A standard XML sitemap practice is to include only canonical URLs that return a 200 OK status code. During a site or URL migration, this rule is temporarily modified to accommodate a dual-sitemap strategy. Managing both legacy and production sitemaps concurrently accelerates the rate at which search engine crawlers process the redirect directives and update the search index.
Retaining legacy sitemaps
Removing the legacy XML sitemap immediately upon launch forces crawlers to rely on standard recrawl schedules or external link profiles to discover the newly implemented redirect rules. For extensive URL transitions, this can significantly delay the processing of the migration.
To expedite crawler discovery, keep the legacy XML sitemap active and submitted in search engine portals. The legacy sitemap must contain the old URLs exactly as they existed before the migration. When crawlers process this file, they systematically request the legacy URLs, encounter the new 301 or 308 redirect status codes, and follow the network path to the new production URLs. This deliberate signaling prioritizes the legacy URLs for recrawling.
If the migration involves a domain name change, host the legacy sitemap on the old domain. Because the old domain typically operates under a global redirect rule routing all traffic to the new domain, developers must add an exclusion rule to the server configuration or edge network. This exclusion ensures the specific path to the legacy XML sitemap bypasses the global redirect and serves a 200 OK status, allowing crawlers to successfully retrieve the file.
Deploying production sitemaps
Concurrently with the legacy sitemap, generate and submit a new XML sitemap containing the final production URLs. This sitemap acts as the definitive map of the new site architecture and establishes the target destination URLs as the new canonical endpoints.
Submitting the production sitemap alongside the legacy version provides search engines with a direct crawl path to the new content, independent of the redirect hops originating from the old URLs. The production sitemap must be strictly validated to ensure it contains no legacy URLs, broken links, or internal redirects.
Managing the transition period
The dual-sitemap configuration operates as a temporary transitional mechanism. The duration for keeping the legacy sitemap active depends on the total volume of URLs and the crawl capacity allocated to the domain by search engines.
The legacy sitemap remains submitted until crawlers have successfully requested the old URLs, processed the destination URLs, and updated the index to reflect the new architecture. Once the URL transition stabilizes, the legacy sitemap is safely deleted from the server and unsubmitted from search engine portals, leaving the production sitemap as the sole active map for the domain.
Detect stealthy removals, nofollow tag injections, and altered anchors instantly.
Post-Migration validation and monitoring
Validation begins immediately after the redirect rules are deployed to the production environment. The objective is to confirm that server responses align with the redirect map and to identify unhandled URLs before they result in prolonged crawl errors.
Validating rules via bulk crawler checks
The first diagnostic step requires testing the complete inventory of legacy URLs. Using a desktop or cloud-based site crawler in list mode, crawl the entire set of old URLs to verify their HTTP response codes and destination targets.
A successful validation run will show that all legacy URLs return either a 301 or 308 permanent redirect status code and resolve directly to their mapped production URLs, which must return a 200 OK status. This automated check helps identify misconfigurations such as unescaped regex characters causing broken paths, rules that fail to trigger, or unintended redirect chains introduced during deployment.
The change of address tool
If the migration involves a complete domain name change or moving from a subdomain to a root domain, use the Change of Address tool within Google Search Console. This tool is specifically designed for cross-domain migrations and cannot be used for protocol changes (HTTP to HTTPS) or path-level site restructuring.
The tool requires owner-level verification for both the legacy and production domain properties. Submitting the change of address request acts as a supplemental domain-level signal, helping Google process the transition of indexing and signals alongside the URL-level 301 redirects.
Monitoring server log files
While bulk crawling verifies known URLs, it cannot detect requests for legacy URLs that were omitted from the initial mapping phase. Server access logs provide a record of how users and search engine crawlers are interacting with the server in real time.
In the days immediately following the migration, extract and analyze the server logs, filtering for requests that return a 404 Not Found HTTP status. By isolating these requests, you can identify patterns of unmapped URLs. Common sources of unexpected post-migration 404s include:
- Historical URLs from older iterations of the legacy site that were still receiving crawl requests.
- Dynamically generated URLs with unrecognized query parameters.
- Hardcoded application links that request assets from deprecated directories.
When high-frequency 404 paths are identified in the logs, create and deploy supplemental redirect rules to route these requests to the appropriate production URLs.
Tracking index transitions in Google search console
Monitoring the Page Indexing reports for both the legacy and production web properties provides visibility into how search engines are processing the migration over time. The transition of indexed URLs from the old architecture to the new architecture is typically visible through specific status changes.
In the legacy domain property, monitor for the following conditions:
- An increase in the Page with redirect status indicates that crawlers are successfully encountering the newly deployed rules and updating their understanding of the URL locations.
- Spikes in Not found (404) or Soft 404 errors indicate that redirects are either missing, misconfigured, or pointing to irrelevant destination pages that the search engine refuses to treat as equivalent.
In the production domain property, monitor for the corresponding uptake:
- Pages should move from Discovered - currently not indexed to active indexed statuses as the redirects pass signals to the new endpoints.
- An accumulation of URLs flagged as Duplicate without user-selected canonical can occur if redirects from the legacy site are failing. Without the redirect to explicitly link the old and new URLs, search engines may temporarily view the newly published production pages as duplicates of the still-indexed legacy pages.
Continuous monitoring of these reports allows for the ongoing adjustment of redirect rules until the legacy URLs are fully deindexed and the production URLs are firmly established in the search engine index.