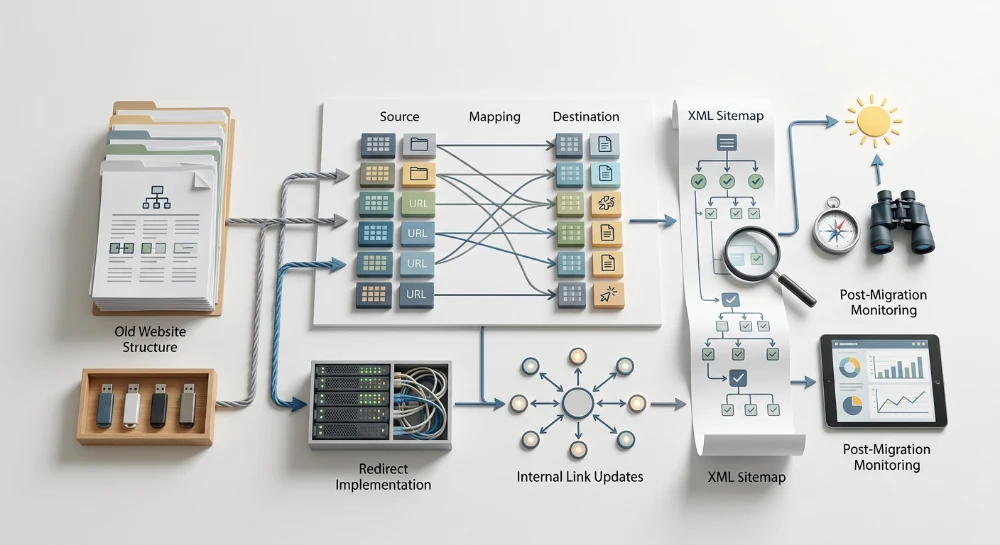
Auditing HTTP to HTTPS redirects is a core requirement for confirming that unsecured URLs resolve cleanly to their secure counterparts following a protocol migration. While installing an SSL/TLS certificate establishes a secure server connection, a complete transition requires verifying that legacy HTTP requests are routed efficiently across the entire site architecture. If left unmanaged, incomplete protocol shifts can cause overlapping indexation signals, redirect chains, or mixed content warnings that complicate crawler evaluation.
A thorough audit evaluates three distinct layers of the implementation. First, it involves verifying server-side configurations to confirm that every HTTP request triggers a direct 301 redirect to the exact HTTPS URL without passing through intermediate hops. Second, it requires inspecting on-page references to secure internal links and media, preventing browsers from loading unsecured resources on otherwise secure pages. Finally, the process addresses technical indexing signals-including canonical tags, XML sitemaps, and hreflang annotations-so that search engines receive consistent instructions to process the secure protocol exclusively.
Relying purely on catch-all server rules without auditing internal references often introduces unnecessary network latency and server overhead. By systematically identifying legacy HTTP links, active mixed content, and conflicting canonical directives, webmasters can eliminate inefficient URL routing and finalize the site's transition to a fully secure architecture.
Verifying Server-Side 301 redirect behavior
The foundation of a protocol migration is the server-side redirect rule. Every request for a legacy HTTP URL must return a 301 Moved Permanently response code that points directly to its exact HTTPS equivalent. This status code instructs search engines to consolidate indexing signals at the new secure location and ensures browsers route requests to the secure protocol.
Testing headers with cURL
Browser testing can be unreliable for redirect auditing due to local caching of previous routing directives. For accurate validation of individual URLs, the command line curl utility allows direct inspection of server response headers. Executing a header-only request reveals exactly how the server handles the HTTP connection.
curl -I http://example.com/pathThe resulting output should display an initial HTTP 301 status, followed immediately by a Location header specifying the secure destination:
HTTP/1.1 301 Moved Permanently
Location: https://example.com/path
If the response returns a 302 Found status, the redirect is temporary, which delays the transfer of indexing signals. If it returns a 200 OK, the server is serving the page over unsecured HTTP rather than redirecting the request.
Scaling verification with site crawlers
While curl is useful for spot-checking configuration rules, SEO site crawlers are necessary to validate redirect behavior across an entire domain. Configuring a crawler to process a list of known HTTP URLs will map the exact redirect path for every page. The resulting crawl data helps isolate systemic routing errors that manual testing might miss.
When analyzing the crawler export, focus on identifying three specific failure modes:
- Intermediate hops: A redirect chain occurs when a request passes through multiple URLs before reaching the final destination. A common example is an HTTP non-www URL redirecting to an HTTP www URL, which then redirects to the HTTPS www version. Each additional hop adds network latency and complicates crawler processing.
- Redirect loops: Conflicting rules can cause an infinite loop, often occurring when an HTTP-to-HTTPS rule clashes with an older HTTPS-to-HTTP fallback rule. The server will repeatedly bounce the request between protocols until the client terminates the connection.
- Parameter drops: A poorly configured redirect might strip query parameters during the protocol switch, causing tracking codes, pagination, or dynamic page variables to fail upon reaching the HTTPS destination.
Resolving configuration anomalies
When redirect chains, loops, or incorrect destination variables are detected, the root cause typically resides in the web server's configuration files. Resolving these issues requires reviewing how the server captures and rewrites incoming request variables.
On Apache servers, this involves inspecting the .htaccess file or the virtual host configuration. The redirect directive must use the correct rewrite conditions to target port 80 (HTTP) and apply the appropriate flags to ensure a permanent redirect that stops processing further rules. If intermediate hops are present, it often indicates that separate rules for hostname resolution and protocol resolution are executing sequentially rather than as a single combined rule.
In Nginx environments, administrators should examine the server block directives. A standard implementation uses a dedicated server block listening on port 80 that issues a return 301 statement. Troubleshooting Nginx anomalies usually involves checking that the host and request URI variables are correctly appended to the HTTPS destination, ensuring the exact path and parameters are preserved during the redirect without triggering overlapping location blocks.
Run a deep technical crawl to identify 4xx errors, missing meta tags, and indexation blockers.
Auditing internal links for protocol consistency
Server-side redirects ensure that incoming requests reach the secure version of a page, but they are not a permanent substitute for correct internal navigation. When a site's internal links still point to legacy HTTP URLs, every user click forces the browser to wait for a 301 response before requesting the target page. Relying purely on redirects for internal navigation introduces unnecessary server overhead and latency, creating an inefficient link architecture.
Identifying legacy HTTP references
Finding outdated internal links requires a site-wide crawl to map the current link architecture. Using a site crawler, extract all internal outgoing links and filter the destination URLs by the HTTP protocol. This report isolates every anchor tag where the href attribute explicitly requests the unencrypted protocol.
Legacy links typically cluster into two main categories, each requiring a different update method:
- Navigational links: Links in headers, footers, sidebars, and menus are often hardcoded into content management system templates or theme files. Updating the specific template file usually resolves these protocol inconsistencies across the entire site.
- In-content links: Hyperlinks embedded within article bodies or specific page copy reside in the database. Resolving these requires a database search-and-replace operation to rewrite the legacy HTTP strings within the content tables.
Selecting the correct link format
When rewriting internal links, administrators must choose between absolute HTTPS URLs and root-relative paths.
Absolute URLs include the full protocol and domain name, such as https://example.com/category/page/. This format explicitly enforces the secure protocol and is recommended when content might be syndicated, shared across different subdomains, or used in RSS feeds.
Root-relative paths include only the path from the root directory, such as /category/page/. Because relative paths automatically inherit the protocol of the document loading them, an HTTPS page will naturally request the HTTPS destination. This approach simplifies link management, as the protocol is not hardcoded into the HTML. However, developers should avoid protocol-relative URLs (paths starting with //), as modern web development standards require explicitly defining the secure protocol when an absolute URL is necessary.
Identifying and resolving mixed content warnings
A protocol migration requires more than updating standard hyperlinks. Mixed content occurs when an initial HTML document loads securely over HTTPS, but fetches subresources over legacy HTTP connections. This configuration violates the secure context of the page, triggering browser warnings and potentially breaking functionality.
Active vs. passive mixed content
The W3C Mixed Content specification defines two categories of insecure resources based on the risk they pose to the page. Browsers handle these categories differently based on their potential to alter page behavior.
- Passive mixed content: This includes resources that cannot intercept or modify the page's document object model, such as images, audio files, and video elements. Modern browsers generally load passive content but downgrade the visual security indicator, typically replacing the secure lock icon with a warning symbol.
- Active mixed content: This includes scripts, stylesheets, iframes, and external font files. Because these resources can execute code, modify page data, or completely alter the layout, they present a significant security vulnerability. Browsers block active mixed content by default. Unresolved active mixed content will often result in broken styling, malfunctioning form submissions, or entirely inoperable page features.
Detecting mixed content manually
For individual page inspections, browser developer tools provide immediate diagnostic feedback. The DevTools Security tab reveals the overall security state of the origin and explicitly flags mixed content violations. Moving to the DevTools Console tab provides granular details, logging the exact HTTP resource URLs and specifying whether the browser blocked the request or merely issued a warning.
Scaling detection with site crawlers
Manual inspection is inefficient for a site-wide protocol audit. SEO site crawlers automate detection by parsing the HTML of every URL and extracting all subresource requests.
When configuring a crawl for a migration audit, ensure the tool is set to evaluate both internal and external resource dependencies. The resulting reports aggregate pages hosting insecure elements. Reviewing this output allows administrators to isolate patterns, such as a legacy HTTP script hardcoded into a global footer template versus isolated HTTP image URLs embedded within older database entries.
Resolution methods
Resolving mixed content requires updating the source references to request the HTTPS variant. For internal resources, this involves executing database search-and-replace operations or modifying content management system templates.
For external third-party dependencies, such as tracking scripts or external media libraries, verify that the external host supports HTTPS. If the third-party provider does not support secure connections, the resource must be downloaded and hosted locally or replaced with a secure alternative. Attempting to force an HTTPS request to a server that lacks a valid TLS certificate will result in connection errors and resource failure.
Detect stealthy removals, nofollow tag injections, and altered anchors instantly.
Validating canonicals, sitemaps, and hreflang tags
Server-side redirects handle incoming requests, but on-page and architectural signals dictate how search engines interpret the final URLs. If a site migrates to HTTPS but retains HTTP references in its technical signals, it generates conflicting directives. These mixed signals can cause crawling and indexing inefficiencies, as search engine bots must expend resources resolving the discrepancies between the redirect destination and the declared canonical or sitemap URL.
Self-Referencing HTTPS canonicals
The rel="canonical" link element specifies the preferred version of a web page and must use an absolute URL. Following a protocol migration, verify that the canonical tag on every secure page points to its exact HTTPS equivalent.
An audit should detect two common configuration errors. First, if a content management system generates the canonical URL based on an outdated global variable, an HTTPS page might output a hardcoded HTTP canonical. Second, if the template relies on legacy plugins for protocol resolution, it may fail to enforce the secure scheme. Extract the canonical tag from all URLs during a site crawl and compare the declared canonical protocol against the actual page protocol to isolate mismatches.
XML sitemap URL verification
XML sitemaps serve as a direct indexation guide for search engines. Post-migration, the active sitemap files must contain exclusively secure HTTPS URLs. Submitting HTTP URLs in a primary sitemap instructs crawlers to fetch the legacy addresses, triggering unnecessary 301 redirects and delaying the processing of the new secure architecture.
Extract all URLs from the active sitemap index and its associated child sitemaps. Validate the extracted list to ensure every entry begins with the https:// scheme and resolves directly to a 200 OK status. If the migration strategy utilized a separate, temporary sitemap containing legacy HTTP URLs to accelerate redirect discovery, verify that this legacy sitemap is isolated from the primary index and scheduled for removal once search engines have fully processed the transition.
Validating hreflang annotations
For multilingual or multi-regional sites, hreflang attributes map the relationships between localized page variants. Every URL specified in an hreflang cluster, whether deployed via the HTML head, HTTP headers, or an XML sitemap, must update to the HTTPS variant.
Hreflang validation requires bidirectional confirmation between equivalent pages. If an HTTPS page declares an HTTP alternate, the relationship map becomes fragmented. Search engines encountering the HTTP URL in the annotation will follow the redirect to the HTTPS version, complicating the cluster evaluation and frequently resulting in return-tag errors. Audit the site-wide hreflang extraction data to confirm that all localized alternate URLs and the x-default declaration exclusively reference secure connections.
Checking SSL/TLS certificates and HSTS configuration
A successful protocol migration relies on a valid and correctly configured SSL/TLS certificate. If a 301 redirect points to an HTTPS URL with an invalid, expired, or improperly scoped certificate, browsers will intercept the connection with a security warning. This prevents users from reaching the destination and causes search engines to drop the URL from crawling queues. Verify that the certificate covers the specific hostname handling the request, utilizing Subject Alternative Names (SANs) to encompass the root domain and all active subdomains.
Validating the secure connection requires confirming that the SSL/TLS handshake completes without protocol errors. Use a command-line tool such as
curl -vI https://example.com
or a dedicated diagnostic service to inspect the handshake process. The server must provide a complete certificate chain, including all intermediate certificates, so that client devices can verify the path to a trusted root authority. During this check, ensure the server supports modern security protocols, specifically TLS 1.2 or TLS 1.3, while rejecting connections using deprecated versions like TLS 1.0 or TLS 1.1.
Enforcing secure connections with HSTS
While server-side 301 redirects map legacy URLs to their secure counterparts, the initial HTTP request still adds network latency and allows a brief window for connection interception. HTTP Strict Transport Security (HSTS) prevents this by instructing browsers to automatically convert any HTTP request to HTTPS internally before transmitting it over the network. Once a browser receives the HSTS instruction, it strictly enforces secure connections for that domain, preventing fallback to HTTP.
HSTS is implemented by returning the
Strict-Transport-Security
HTTP header in the server response. According to the specification, browsers only process this header when it is served over a secure HTTPS connection. A standard implementation requires the
max-age
directive, which dictates the number of seconds the browser should cache and enforce the policy. The optional
includeSubDomains
directive applies the same enforcement to all subdomains under the primary host.
To verify the configuration, inspect the response headers of the secure URLs using browser developer tools or a site crawler capable of capturing custom headers. Because HSTS caches the strict enforcement behavior in the user's browser, applying a long
max-age
before confirming that all assets and subdomains are securely accessible can cause connection failures for unmigrated legacy content. Implement the header with a short duration during the initial validation phase, monitor server logs for connection errors, and increase the duration only after verifying network-wide HTTPS stability.
SEO structure and reciprocal link analyzer
Detect orphan pages, deep click depths, and toxic reciprocal links built by careless agencies.
Monitoring indexing and error reports in search console
After configuring server-side redirects and updating site-wide technical signals, monitoring Google Search Console serves as the final validation phase. Tracking indexing behavior confirms that search engine crawlers are successfully processing the old-to-new URL map and transferring indexation from the legacy HTTP URLs to their secure HTTPS counterparts.
Evaluating the indexing transition
To accurately monitor the migration, evaluate the Page Indexing reports for both the HTTP and HTTPS URL-prefix properties, or use the protocol filter within a Domain property. A successful migration displays a predictable pattern: the number of valid, indexed URLs in the HTTP property will steadily decrease, while the indexed URL count in the HTTPS property will simultaneously increase. The HTTP URLs should naturally transition into the "Page with redirect" status category as crawlers process the 301 directives.
Detecting redirect errors
Anomalies in the URL transition process often surface as specific indexing exceptions. Review the "Not indexed" categories to identify failed redirects. The "Redirect error" classification indicates that Googlebot encountered an issue while attempting to follow the HTTP to HTTPS directive. This typically results from redirect loops, excessively long redirect chains, or server timeouts during the request. Inspecting individual URLs flagged with this error using the URL Inspection tool allows you to view the exact response Google received, isolating which rules in the server configuration are failing under live crawling conditions.
Identifying unintended soft 404s
During a protocol migration, misconfigured redirect mapping can trigger Soft 404 errors. This condition frequently occurs if a broad server rule redirects specific legacy HTTP pages to the secure homepage or an unrelated parent category, rather than executing a strict one-to-one redirect to the exact HTTPS equivalent. When crawlers detect that the destination page lacks the specific content of the original URL, they classify the redirect as a Soft 404. Reviewing the "Soft 404" report category helps pinpoint mapping failures where the redirect technically reaches a live page, but the content relevance has been broken.
Investigating persistent HTTP crawling
If legacy HTTP URLs remain in the "Indexed" status or shift to "Duplicate, Google chose different canonical than user" long after the redirect implementation, it indicates that crawlers are struggling to finalize the protocol shift. This often points to conflicting signals that bypassed earlier audits, such as an isolated XML sitemap still submitting HTTP URLs, or server-side redirects occasionally failing due to intermittent latency. Exporting the list of persistently indexed HTTP URLs from Search Console allows you to run a targeted diagnostic check against those specific paths, verifying whether server timeouts or lingering legacy references are preventing the final transition.