The question of how to handle multiple H1 headings correctly is a frequent source of friction during technical site audits. For years, standard SEO advice dictated a strict limit of one H1 tag per URL, leading webmasters to flag any duplicate tags as structural errors. This rule was rooted in older HTML specifications and early search engine limitations, creating a lingering assumption that additional top-level headings will automatically confuse crawlers or trigger a ranking penalty.
Both modern HTML specifications and Google’s rendering systems are fully capable of processing documents with more than one H1 element. Search engine crawlers use heading tags to establish context and parse topical hierarchy, and encountering multiple top-level headings does not inherently harm indexation. In certain architectural formats, such as blog category index pages or single-page applications containing independent sectioning elements, utilizing multiple H1 tags is technically valid and semantically accurate.
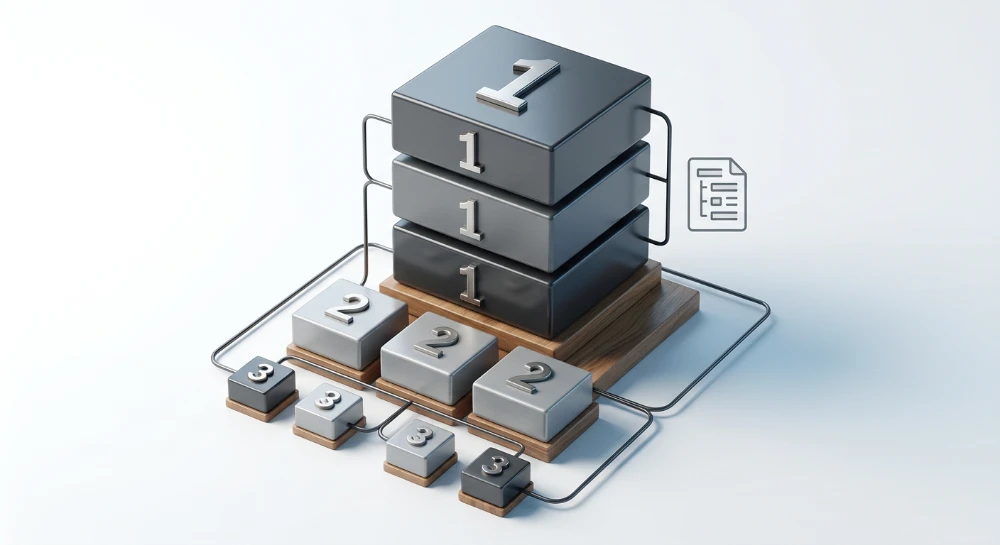
However, technical tolerance does not override the value of a clear, unified document outline. While search algorithms can evaluate multiple H1 tags without failing, maintaining a traditional structure-a single primary H1 followed by properly nested H2 and H3 subheadings-remains the most reliable baseline practice. A strict heading hierarchy eliminates ambiguity about the page's core topic and ensures a predictable navigation path for users relying on screen readers and other assistive technologies.
HTML5 document outlining and the single h1 rule
Before HTML5, web specifications treated a webpage as a single unified document. Under HTML4 and XHTML, the document outline was determined entirely by heading ranks. The H1 tag represented the document's singular title, and subsequent H2 through H6 tags created nested subsections. Using multiple H1 tags in this era broke the hierarchical tree, creating flat, disconnected outlines. This structural requirement formed the basis of the traditional rule dictating a strict limit of one H1 per URL.
The introduction of HTML5 attempted to solve the limitations of this rigid structure by introducing a new document outline algorithm. The specification added semantic sectioning elements, including
<article>
,
<section>
,
<aside>
, and
<nav>
. Under this model, each sectioning element acts as an independent container with its own outline. Theoretically, web developers can start each discrete
<section>
or
<article>
with an H1 tag. The HTML5 algorithm was designed to automatically calculate the structural hierarchy based on the nesting of these sectioning containers, rather than relying solely on the numerical rank of the heading tags.
While using multiple H1 tags inside distinct sectioning elements is technically valid semantic HTML, the theoretical outline algorithm faces significant real-world limitations. Major web browsers and assistive technologies never fully adopted the HTML5 outline algorithm. When parsing a page, these user agents typically do not compute the hierarchy based on sectioning containers.
Because the intended HTML5 outlining behavior is inconsistently supported, user agents fall back to interpreting heading tags exactly as they appear in the Document Object Model. If a document uses multiple H1 tags across various
<section>
elements, technologies like screen readers will often present them as multiple top-level headings, flattening the perceived hierarchy and complicating navigation. Due to this lack of widespread implementation, relying on a strict hierarchical order-using a single H1 for the page title and correctly nesting H2 through H6 tags for subsections-remains the practically safer and more universally understood approach.
Run a deep technical crawl to identify 4xx errors, missing meta tags, and indexation blockers.
How Google interprets pages with multiple h1s
Google's rendering and indexing systems are fully equipped to process documents containing multiple H1 elements. According to documentation like the Google SEO Starter Guide and repeated clarifications from Google Search advocates such as John Mueller, the presence of more than one H1 tag is not a webspam violation and does not trigger an algorithmic penalty. Googlebot parses the HTML exactly as provided, reading multiple top-level headings without automatically harming a page's indexation or ranking potential.
Instead of applying a rigid single-heading rule, Google evaluates heading tags to understand the structure of the content and to identify primary topics. When a crawler encounters multiple H1 tags, it attempts to use all of them, alongside the
<title>
element and the body text, to construct a topical map of the page. The algorithm relies on these tags to determine what the page is broadly about and how distinct blocks of text relate to the overall document.
However, the absence of a penalty does not mean document structures are exempt from best practices regarding clarity. While search engines can process multiple H1 tags, the primary topic of the document must still remain obvious. If a page uses several H1 tags that introduce competing or unrelated concepts, or if site templates wrap boilerplate elements in H1 tags purely for styling, the core context of the page can become diluted. Under these conditions, Google's systems must weigh conflicting top-level signals to extract the main entity, which introduces unnecessary ambiguity.
The functional distinction for SEO lies in semantic clarity rather than strict tag limits. When multiple H1 tags are used logically, Google can typically extract the hierarchy accurately. When multiple H1 tags create a fragmented outline, it represents a structural inefficiency. The technical objective is to ensure that the document's structure guides the crawler directly to the most important contextual signals, minimizing the effort required by the algorithm to determine the page's primary focus.
Why logical hierarchy matters for accessibility
While search algorithms have adapted to process varied heading structures, assistive technologies rely heavily on strict semantic HTML to interpret a document. Under the Web Content Accessibility Guidelines (WCAG), headings serve as the primary mechanism for conveying page architecture to users who cannot visually scan a layout.
Screen reader software, such as NVDA, JAWS, or VoiceOver, provides functionality that allows users to pull up a consolidated list of all headings on a page or to jump sequentially from one heading to the next using keyboard shortcuts. This creates a functional audio table of contents. When a user navigates this way, the heading level explicitly communicates the structural relationship between different blocks of text.
Deploying multiple H1 tags can severely disrupt this navigation pattern if the tags are not strictly nested within appropriate HTML5 sectioning elements, such as
<article>
or
<section>
. Without these distinct containers defining scope, the document's outline flattens. If a page uses multiple H1 tags to introduce standard sub-sections, a screen reader user encounters a series of top-level announcements. This lack of subordination forces the user to manually determine whether a new H1 represents a completely independent piece of content or merely a poorly coded subtopic.
A traditional heading structure-featuring a single primary H1 tag followed sequentially by H2 tags for major sections and H3 tags for localized subtopics-remains the most predictable pattern for accessibility. This linear, descending hierarchy ensures that screen readers can accurately communicate parent-child relationships in the content without relying on complex HTML5 outlining rules that browser and assistive technology vendors support inconsistently.
SEO structure and reciprocal link analyzer
Detect orphan pages, deep click depths, and toxic reciprocal links built by careless agencies.
Valid use cases for multiple h1 headings
While a linear, descending heading hierarchy is the most predictable pattern for document structure, specific architectural designs and content models justify the use of multiple H1 tags. In these scenarios, the H1 tags do not represent subtopics of a single primary theme. Instead, they serve as the top-level titles for distinct, independent entities that share a single URL or DOM instance.
Content aggregators and syndication pages
Pages designed to display multiple complete documents often require independent heading structures for each item. Common examples include continuous-scroll blog interfaces, news syndication feeds, and forum index pages that render the full text of user posts rather than truncated summary cards.
When an aggregator page displays full documents, each document requires its own internal hierarchy. This pattern is implemented by wrapping each distinct piece of content in an
<article>
element. Because the HTML5 specification defines
<article>
as a self-contained sectioning root, an H1 placed inside it does not compete with the H1 of the parent page or neighboring articles. The semantic scope of the heading is restricted to the container, shifting its meaning from the main topic of the page to the specific title of that isolated article.
Single-Page applications
Single-page applications built on JavaScript frameworks load functional views into a central DOM container without triggering a standard browser refresh. As a user navigates from a main dashboard to a reporting interface, the application dynamically swaps the relevant components.
Because each view functions as a discrete page for the user, dynamically injected components routinely contain their own H1 tags. During transitions, multiple H1 nodes might exist in the application's source code or hidden DOM states, even if only one is visibly rendered. The presence of multiple H1s in the component logic is standard practice for this architecture. Developers manage this pattern by pairing the semantic H1 with programmatic focus management, ensuring that assistive technologies recognize the context shift and announce the new H1 when a view changes.
The structural containment requirement
The technical validity of these exceptions depends entirely on strict semantic containment. Deploying multiple H1 tags across a page without explicit sectioning boundaries flattens the document outline and creates ambiguity.
To preserve semantic clarity, an additional H1 must only appear inside an element explicitly designed to enclose independent content. Using an H1 inside a generic
<div>
container fails to create a new sectioning context. When a parser encounters an H1 inside a
<div>
, it interprets the heading as a top-level peer to the page's primary H1, disrupting the logical subordination of the content. Valid implementation requires aligning the multiple headings with strict semantic HTML5 tags to ensure the relationships between the independent content blocks remain clear.
Common h1 mistakes that dilute semantic clarity
While modern browsers and search engine crawlers can parse multiple H1 tags, sloppy implementation creates a fragmented document outline. When heading tags are deployed for visual formatting or as byproducts of CMS configurations rather than structural indicators, the semantic clarity of the page deteriorates.
Using h1 tags for visual styling
One of the most frequent errors is using an H1 tag simply because a design requires large, bold text. This commonly occurs in sidebar widgets, footer call-to-actions, or promotional banners. When a developer wraps a newsletter signup prompt or a related-posts widget in an H1 tag to trigger a specific CSS font size, the text is elevated to the same structural level as the page's primary title.
This flattens the hierarchy. It forces HTML parsers and screen readers to evaluate a minor interface element as a core topic of the document, misaligning the underlying code with the visual layout.
Accidental duplication in responsive layouts
Responsive web design frequently introduces duplicate H1 tags through isolated mobile and desktop components. A common pattern involves rendering the main page title in the desktop content area while duplicating the exact same H1 tag inside a mobile off-canvas menu or a fixed mobile header.
Even when CSS rules like
display: none
hide the mobile variant from desktop users, both tags remain present in the DOM. This redundancy clutters the document outline, creates unnecessary repetition for assistive technologies reading the source code, and introduces multiple identical nodes into the accessibility tree.
Global logo wrappers and missing headings
Another structural failure involves wrapping the site logo in an H1 tag globally across all pages. While historically used as a homepage convention, carrying this template logic to interior pages introduces a persistent, site-wide H1 that competes with the actual page content.
Conversely, some CMS themes omit the H1 entirely on specific templates, often when a featured image or hero banner replaces the text-based title. A missing H1 removes the primary entry point for the document outline. Without this anchor, search engines and screen readers must infer the main topic entirely from lower-level headings or standard paragraph text.
Impact on document logic and keyword relevance
These poor hygiene practices obscure the structural logic of the main content. Search engines rely on heading tags to verify the primary subject matter of a page and map the relationships between different text blocks.
When multiple competing H1 tags exist for styling purposes, or a global logo tag supersedes the article title, the content relevance signals are diluted. The parser must weigh the text of a sidebar widget equally against the actual article title. While search algorithms use advanced heuristics to identify the true main content area, providing conflicting structural signals forces the parser to resolve unnecessary ambiguity.
Parse live Google SERPs, extract LSI entities, and write highly relevant articles.
How to audit your heading structure
Identifying heading issues requires a two-step approach: crawling the site to extract heading data at scale, followed by manual inspection to determine if the implementation is semantically valid or an accidental template error.
Finding multiple h1 tags at scale
Use an SEO crawler like Screaming Frog SEO Spider to evaluate heading usage across the entire website. After running a standard crawl, review the H1 reports to filter for URLs containing multiple H1 tags, missing H1 tags, or exact duplicate H1 text.
Reviewing the crawl export helps isolate whether multiple H1s are an isolated content issue or a global template flaw. If thousands of pages share the exact same secondary H1 string, the tag is likely hardcoded into a site-wide element, such as a desktop navigation menu, a hidden mobile menu wrapper, or a footer widget.
Manual source code inspection
For URLs flagged by the crawler, manual inspection verifies the context of the additional heading tags. Visual rendering in the browser is unreliable for this step, as CSS can hide heading tags entirely or style standard text to look like a primary heading.
Open the page source code and search for the H1 element to locate its exact position. Alternatively, use an SEO browser extension to extract the page's heading tree. Reviewing the sequential outline reveals whether the extra H1 tags disrupt the document logic. An H1 appearing before the main article title, or interrupting a nested sequence of H2 and H3 subheadings, typically indicates a structural flaw.
Evaluating semantic justification
When an audit reveals multiple H1 tags, run the URL through the W3C Markup Validation Service to check technical compliance. The validator evaluates whether the HTML follows structural specifications.
Use the validation results and the extracted document outline to apply a clear decision rule:
- If the extra H1 tags define completely independent content blocks contained within their own sectioning elements, such as distinct posts on a blog index page, the implementation is structurally justified.
- If the extra H1 tags are used for global site navigation, applied to empty wrapper elements, or used solely to enlarge text in a sidebar, they are implementation errors.
For unjustified H1 tags, the standard remediation is to change the HTML element to a more appropriate semantic tag, such as an H2 or a standard paragraph, and apply CSS classes to maintain the intended visual presentation.