Auditing a robots.txt file ensures that search engine crawlers process a website's access rules exactly as intended, adhering to the RFC 9309 standard. The primary purpose of this evaluation is to verify correct directive syntax and manage crawler access effectively, preventing accidental blocks on critical site architecture while securing restricted paths.
A technical audit begins by confirming precise file placement and server response codes. The HTTP status code returned for the robots.txt file dictates fundamental crawler behavior; for example, specific server errors can force search engines to halt site access entirely. Once basic accessibility is verified, the process requires validating user-agent grouping and evaluating the specific pattern matching logic, such as wildcards and longest-path rules, used in Allow and Disallow directives.
Beyond structural formatting, the audit must identify mechanical conflicts between crawling directives and indexing requirements. This includes detecting rules that block the CSS, JavaScript, or API endpoints necessary for search engines to render page content. It also involves resolving indexing contradictions, such as lifting crawl restrictions on specific URLs so that search engines can successfully access and process meta noindex tags.
Verifying file placement and server responses
To function correctly, a robots.txt file must reside exactly at the top-level root directory of the specific host and protocol. For example, a crawler evaluating
https://www.example.com
will only request
https://www.example.com/robots.txt
. If the file is placed in a subdirectory or remains on an HTTP protocol while the site enforces HTTPS, search engines will not discover the access rules. The server must deliver the file using a
text/plain
content type encoded in UTF-8. Serving the file as HTML or returning it with an incorrect MIME type can cause parsers to reject or ignore the directives entirely.
The HTTP status code returned for the robots.txt URL strictly dictates how crawlers handle the entire domain. Evaluating this response is a primary diagnostic step in any technical audit:
-
200 OK: The file is fully accessible, prompting the search engine to read and process the specified pattern matching logic. -
4xx Client Error: A status code such as 404 Not Found tells crawlers that no robots.txt file exists. Under this condition, the crawler assumes there are no restrictions, and a full crawl of the host is permitted. -
5xx Server Error: A status code such as 500 Internal Server Error or 503 Service Unavailable forces search engines to halt site access entirely. Crawlers suspend their activity to avoid overloading a server that appears to be struggling or offline.
Auditors must carefully check server logs and live HTTP headers for accidental 5xx errors or unintended redirects. Transient backend issues, misconfigured web application firewalls, or content delivery network (CDN) anomalies can sporadically return 5xx errors specifically for the robots.txt path, resulting in severe, unintended crawl restrictions across the entire site.
Additionally, verify that the URL does not trigger a 3xx redirect chain. Global rewrite rules often inadvertently redirect
.txt
requests to a homepage or a custom error page, which can confuse crawler logic. While some search engines will follow a limited number of redirects to locate the file, standard practice requires the robots.txt URL to return a direct
200 OK
response without relying on intermediate routing hops.
Run a deep technical crawl to identify 4xx errors, missing meta tags, and indexation blockers.
Validating syntax, User-Agents, and sitemaps
The robots.txt file operates on a line-based syntax where each directive takes the format
Directive: Value
. An audit must verify that declarations are correctly grouped. A standard record begins with one or more
User-agent
lines specifying the target crawler, immediately followed by the associated
Allow
or
Disallow
instructions. Blank lines or unrecognized text separating a user-agent declaration from its rules can disrupt parser logic and lead to ignored directives.
User-Agent specificity and fallback logic
Crawlers process only the group of rules that most specifically matches their name. The
User-agent: *
declaration acts as a global fallback for any crawler that does not have a designated section.
If a file contains a specific group for a crawler such as
User-agent: Googlebot
or
User-agent: GPTBot
, alongside a separate fallback group under
User-agent: *
, the named crawler will only obey the directives in its specific section. It entirely ignores the fallback rules. A common configuration error assumes that a specific user-agent inherits the global directives. Because rules do not merge across groups, any restriction intended for all crawlers must be explicitly duplicated in a specific user-agent group if that agent is given its own section.
Validating sitemap declarations
The
Sitemap
directive helps search engines discover XML sitemaps independently of HTML references. Unlike access rules, this declaration is not bound to a specific user-agent group. It applies globally and can be read by all supporting crawlers regardless of where it appears in the text file.
When auditing sitemap directives, verify that the provided value is a fully qualified absolute URL. A relative path is invalid and will prevent crawlers from locating the file. An audit should confirm the syntax includes the complete protocol and host, formatted as
Sitemap: https://www.example.com/sitemap_index.xml
rather than
Sitemap: /sitemap_index.xml
.
Non-Standard directives
Auditors must also identify non-standard directives that exist outside the core RFC 9309 specification, as their execution depends entirely on the parsing crawler. For example, the
Crawl-delay
directive attempts to limit the request rate for visiting bots. While this instruction is actively parsed and enforced by Bingbot, it is ignored by Googlebot. Auditing these custom directives requires cross-referencing specific crawler documentation to ensure the intended rate-limiting or access controls function correctly on the target platform.
Evaluating URL pattern matching and wildcards
Auditing the path matching logic requires examining how specific crawler directives translate to the actual URLs on a site. A syntactically correct file can still cause severe crawling issues if the underlying matching logic is flawed.
Prefix matching and case sensitivity
By default, crawlers evaluate path rules as literal prefixes. A directive applies to any URL that begins with the exact character sequence specified. For example,
Disallow: /admin
blocks
/admin/
,
/admin/settings
, and
/admin-login.html
. To restrict only the directory and its contents without affecting similarly named files, the trailing slash must be included, as in
Disallow: /admin/
.
All path matching in robots.txt is strictly case-sensitive. A rule specifying
Disallow: /Private/
will not prevent a crawler from accessing
/private/
. An audit should verify that the casing used in the file matches the actual URL structures generated by the server.
Wildcards and suffix matching
Crawlers supporting RFC 9309 recognize specific characters for advanced pattern matching. The asterisk (
*
) functions as a wildcard, representing zero or more valid characters. This is useful for targeting parameters or file types across multiple directories. A rule like
Disallow: /*?filter=
applies to any URL containing that parameter string, regardless of the preceding path.
The dollar sign (
$
) designates an exact suffix match, anchoring the rule to the absolute end of the URL string. Using
Disallow: /*.pdf$
prevents the crawling of URLs ending exactly with
.pdf
. Without the dollar sign, the crawler would also block
/document.pdf?version=2
, as the rule would revert to a standard prefix match starting with the wildcard.
Resolving rule conflicts
When a single URL matches both an
Allow
and a
Disallow
directive within the same user-agent group, crawlers resolve the conflict using the longest matching path rule. The directive with the highest character count in its path string takes precedence because it is considered the most specific.
Consider the following configuration:
Allow: /products/shoes/sneakers/
Disallow: /products/shoes/
A crawler requesting
/products/shoes/sneakers/running
will process both rules. Because the
Allow
path contains 26 characters and the
Disallow
path contains 16 characters, the longer
Allow
rule wins, and the URL is crawled. If conflicting rules have the exact same character length, standard behavior dictates that the least restrictive rule applies. However, an audit should recommend rewriting such rules to remove structural ambiguity entirely.
Identifying logic errors
A common failure mode occurs when broad wildcard blocks inadvertently override specific allow rules due to path length calculations. For instance, a lengthy wildcard rule intended to block a complex parameter combination might contain more characters than a concise
Allow
rule designed to keep a critical directory open. If a URL happens to match both conditions, the longer wildcard rule will unexpectedly block the crawler.
Auditing requires tracing overlapping paths to ensure that intended exceptions are not negated by longer, overly aggressive wildcard disallows. A directory meant to be accessible must have an
Allow
rule that is demonstrably longer than any overlapping
Disallow
pattern.
Bulk Google and Yandex index checker
Verify agency reports and track live SERP status in Google and Yandex to protect your SEO ROI.
Identifying critical blocking and rendering errors
A robots.txt audit must prioritize the detection of rules that prevent search engines from accessing or understanding a website's core content. Diagnosing these errors requires evaluating both site-wide directives and the granular rules that govern supporting page assets.
Detecting accidental Site-Wide blocks
The most severe failure mode is the unintentional deployment of a site-wide block. A single directive containing
Disallow: /
under a broad user-agent configuration instructs compliant crawlers to halt all access to the host.
This error frequently occurs during site migrations or routine deployment cycles. Development and staging environments are routinely blocked using this method to prevent search engines from indexing unfinished or duplicate content. If the deployment pipeline fails to swap the staging configuration for the production configuration, the live website inherits the block. An audit must always verify that the root path remains unrestricted in the production environment.
Unblocking rendering resources
Modern search engine crawlers do not merely read raw HTML; they execute JavaScript, fetch API responses, and load CSS to render pages visually. This rendering phase is necessary for the crawler to parse dynamically injected content, evaluate the page layout, and determine mobile usability.
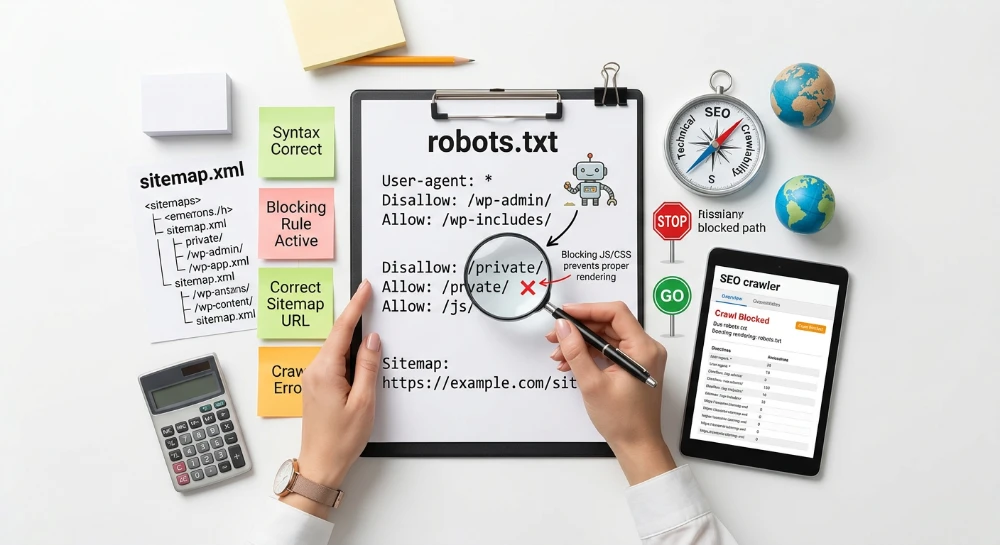
If the robots.txt file blocks access to the directories or subdomains hosting these critical assets, the crawler cannot render the page properly. A fully functional, content-rich page might appear to the search engine as a blank document or a broken layout.
An audit should specifically scan for directives that restrict access to frontend architecture. Common problematic patterns include:
-
Disallow: /assets/ -
Disallow: /js/ -
Disallow: /css/ -
Disallow: /api/
If a single-page application or JavaScript framework requires client-side API calls to populate text content or core navigation, those specific API endpoints must be accessible to crawlers. Any rule blocking these rendering resources should be removed or overridden with a specific
Allow
directive.
Clearing orphaned and legacy rules
As websites evolve, URL structures change, directories are deprecated, and legacy parameters are removed. However, the robots.txt file often accumulates the directives associated with these obsolete paths. An audit should identify these orphaned rules.
While blocking a path that already returns a 404 Not Found status code does not directly degrade search engine access to live pages, accumulating this technical debt creates secondary risks. An overgrown robots.txt file becomes difficult for administrators to read, troubleshoot, and maintain. More importantly, legacy wildcard directives can cause unintended pattern collisions. A newly launched directory might unexpectedly match a broad, forgotten block from a previous site iteration, resulting in immediate crawling failures for new content. Pruning directives that target outdated paths keeps the file concise and predictable.
Resolving the 'indexed, though blocked' conflict
Robots.txt dictates crawling permissions, whereas indexing directives dictate whether a URL appears in search results. A mechanical conflict occurs when administrators attempt to remove a page from the index by adding a noindex tag while simultaneously blocking the URL in robots.txt.
When a
Disallow
rule prevents a search engine crawler from fetching a URL, the crawler cannot read the page content or its HTTP response headers. Because the page is not crawled, the search engine never sees the HTML meta noindex tag or the
X-Robots-Tag
HTTP header. The crawler respects the robots.txt block and halts the network request, leaving the indexing directive unprocessed.
If other indexed pages link to this blocked URL, a search engine can still discover the URL and may index it based on those link signals. Because the crawler cannot access the actual page content to extract text, the URL typically appears in search results without a standard title or meta description. This scenario triggers the "Indexed, though blocked by robots.txt" warning in Google Search Console.
Implementing the explicit resolution
Removing the URL from search results requires prioritizing the indexing directive over the crawling restriction. To process the noindex command, the search engine must be able to crawl the page.
The resolution follows a specific sequence. First, verify that the target URL serves a valid noindex tag in the HTML head or an
X-Robots-Tag: noindex
HTTP header. Alternatively, ensure the page returns a 404 Not Found or 410 Gone HTTP status code.
Second, modify the robots.txt file to lift the crawling restriction on that URL. This requires removing the offending
Disallow
pattern or adding a more specific
Allow
directive that overrides the block.
Once the robots.txt block is lifted, the crawler will fetch the URL during a subsequent pass, detect the noindex signal or 4xx status code, and drop the page from the index. After the URL is successfully deindexed, the robots.txt block can be reinstated if the administrator wants to prevent future crawling of the path.
SEO structure and reciprocal link analyzer
Detect orphan pages, deep click depths, and toxic reciprocal links built by careless agencies.
Testing and validating robots.txt rules
Deploying modifications to a robots.txt file requires verification to confirm that search engines process the new directives as intended. Validation involves checking both the cached file recognized by search engines and the practical effects of the rules across the site's URL structure.
Using Google search console for verification
Googlebot does not fetch a site's robots.txt file every time it requests a page. Instead, it relies on a cached version, typically refreshing it within a 24-hour window. The robots.txt report in Google Search Console displays the exact file contents currently held in Google's cache. If recent modifications are missing, administrators can use this report to request an immediate recrawl of the file, forcing the cache to update.
Once the updated file is cached, the URL Inspection tool serves as a diagnostic instrument for individual paths. Running a live test on a specific URL reveals the current fetch status. The tool reports whether crawling is allowed and details any page resources that remain blocked. Testing representative URLs from modified directories confirms that the updated
Allow
or
Disallow
patterns function correctly in a live environment.
Simulating crawls with Third-Party SEO spiders
While Google Search Console validates individual URLs and specific Googlebot behavior, third-party SEO spiders test pattern matching at scale. These tools can simulate a crawl using a custom or modified robots.txt file, making it possible to validate changes before deploying them to a production server.
Configuring a crawler to strictly follow the proposed rules helps identify several deployment issues across the domain architecture:
- Site-wide logic errors: A simulated crawl quickly exposes unintended consequences, such as a broad wildcard configuration inadvertently restricting access to a core product category, nested directory, or subfolder.
- Resource accessibility: Spiders aggregate data on blocked page assets. Reviewing this output confirms whether CSS files, JavaScript frameworks, or required API endpoints are successfully unblocked, allowing search engines to render the page content fully.
- Pattern matching validation: Automated crawlers evaluate thousands of URLs against the file's literal strings and wildcards. This verifies that complex directive conflicts resolve correctly across the entire site without requiring manual, URL-by-URL testing.
Reviewing the crawler's blocked URL report provides a final diagnostic check. If a URL that should be accessible appears in the blocked list, or if a restricted URL is successfully crawled, the corresponding path matching rules in the file require adjustment before final deployment.