When a URL appears in the Google Search Console Page Indexing report under the "Discovered - currently not indexed" status, it indicates a specific bottleneck in the early stages of the search engine pipeline. In this documented state, Google is aware of the URL's existence-usually through an XML sitemap, an RSS feed, or internal discovery-but has deliberately postponed the initial fetch. The crawler has not yet executed a GET request to evaluate the page HTML.
This delay is rarely a reflection of the page's actual content, as Googlebot has not yet seen it. Instead, crawls are typically deferred due to crawl capacity constraints, queue prioritization, or site architecture inefficiencies. If a server responds slowly or shows signs of strain, Google will automatically reschedule fetch requests to prevent overloading the host. Additionally, structural issues like excessive parameterized URLs or unmanaged faceted navigation can bloat the discovery pipeline, diluting crawl demand and trapping valid pages in a holding pattern.
Resolving this status requires diagnosing the technical environment rather than optimizing the text on the individual page. A sustained increase in discovered but unindexed URLs usually signals that webmasters need to investigate server availability, review host load warnings in the Crawl Stats report, or aggressively manage internal link signals to help Google efficiently prioritize and process the crawl queue.
Discovered vs. crawled: Distinguishing pipeline stages
The distinction between "Discovered - currently not indexed" and "Crawled - currently not indexed" identifies the exact point where a URL stalled in the processing pipeline. While both statuses result in a page being excluded from search results, the technical failure occurs at completely different stages of Google's evaluation.
A "Discovered" status means that a GET request was never executed. The crawler added the URL to its queue but never asked the server for the page document. Conversely, a "Crawled - currently not indexed" status indicates that Googlebot successfully connected to the host, executed the GET request, and downloaded the payload. In the latter case, the exclusion happened during the evaluation phase, where the indexer reviewed the fetched HTML and rejected the page due to factors like thin content, unassigned duplication, or rendering failures.
This pipeline distinction dictates the required troubleshooting approach. Because Googlebot has not yet downloaded a "Discovered" URL, rewriting the text, adjusting title tags, or optimizing on-page media will not resolve the status. The search engine is entirely unaware of the page's current content or any recent improvements made to the HTML.
Moving a URL out of the "Discovered" state relies strictly on managing the technical environment and the crawl queue. Diagnosing the issue requires stepping away from the individual page content to address server capacity constraints, optimize crawl scheduling, and refine the internal link architecture so the crawler can efficiently reach and process the requested URLs.
Run a deep technical crawl to identify 4xx errors, missing meta tags, and indexation blockers.
Server availability and crawl capacity limits
Googlebot operates on a polite crawling principle, dynamically adjusting its request volume to avoid degrading the experience for human site visitors. It constantly evaluates how many concurrent connections a host can support, establishing a baseline crawl capacity limit. When a URL is found, it enters a priority queue, and Google attempts to fetch items from this backlog at a pace governed by the server's apparent stability.
To determine capacity limits, the crawler monitors real-time server health signals during its fetching operations. If the server responds swiftly to requests, Googlebot maintains or increases its crawl rate. However, if the infrastructure struggles to handle the traffic, the crawler detects the strain through specific HTTP indicators. Slow server response times, connection timeouts, and sporadic HTTP 5xx errors-such as 500 Internal Server Error, 502 Bad Gateway, or 503 Service Unavailable-signal that the host is overloaded.
Upon detecting these load issues, Googlebot immediately reduces its crawl demand. It throttles the number of concurrent connections and slows the frequency of new requests to prevent pushing the server offline. The GET requests that were scheduled for execution are deliberately postponed.
This automated back-off mechanism is a primary cause of a persistent discovery backlog. The crawler knows the URLs exist and has queued them for processing, but the restricted server capacity forces an indefinite delay. If the hosting environment remains consistently sluggish or prone to transient errors, the crawl rate stays depressed. As new URLs continue to enter the pipeline through sitemaps or link discovery, the queue expands faster than the crawler is willing to process it, leaving valid pages stranded in the discovered state until server performance recovers and a higher request volume can be safely sustained.
Diagnosing host load with the crawl stats report
The Crawl Stats report in Google Search Console is the primary diagnostic tool for identifying server capacity limits. Located within the Settings menu, this report provides a 90-day historical view of Googlebot's fetching behavior, average response times, and server availability. When a large volume of URLs remains pending in the discovery phase, this data helps confirm if infrastructure strain is the limiting factor.
Evaluating host status and fetch errors
Begin by reviewing the Host status section of the report, which flags severe infrastructure issues. Look for specific warnings such as a failed host status or instances where host load is marked as exceeded. This section categorizes failures into DNS resolution, server connectivity, and robots.txt fetching. A high volume of connection timeouts or server errors here indicates that the host is actively dropping connections. When these errors accumulate, Googlebot restricts new fetch attempts, leaving known URLs in the discovery queue.
Analyzing response time trends
If the overall host status does not show critical failures, examine the Average response time chart. Server strain often manifests as a gradual degradation in performance rather than an immediate outage. Look for sudden spikes or a sustained upward trend in the time required for the server to return the initial HTML payload.
While there is no strict universal threshold, response times that consistently climb into the upper hundreds of milliseconds or beyond often prompt the crawler to reduce its concurrent connection limits to preserve server stability.
Correlating crawl volume with the discovery queue
Compare the response time data against the Total crawl requests chart. A standard crawler-throttling pattern occurs when average response time increases significantly while total daily crawl requests simultaneously drop. When the system detects high latency, it scales back demand to prevent overwhelming the infrastructure.
To confirm that server load is responsible for the discovery backlog, cross-reference the timeline of these crawl anomalies with the Page indexing report. If a steep drop in total crawl requests or a sustained spike in response times aligns with a sudden increase in URLs categorized as discovered but not indexed, server capacity is the primary constraint. The crawler is registering new links through sitemaps or page extraction faster than the current server response times safely permit it to process them.
Bulk Google and Yandex index checker
Verify agency reports and track live SERP status in Google and Yandex to protect your SEO ROI.
Identifying pipeline bloat and structural inefficiencies
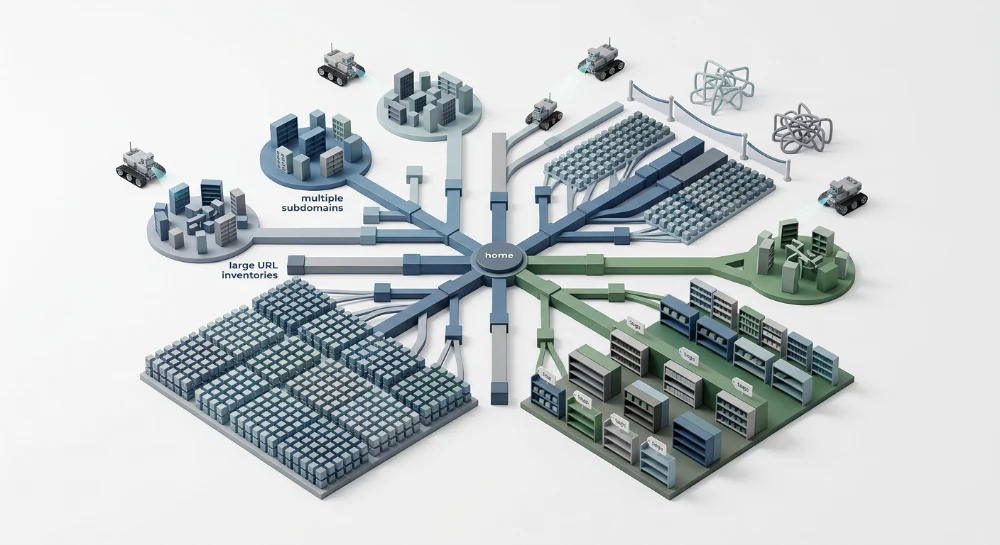
While server response times dictate how many requests a crawler can safely make, site architecture determines how many requests it needs to make. Pipeline bloat occurs when a website generates an uncontrolled volume of low-value, variant, or duplicate URLs. When Googlebot encounters these links, it adds them to the discovery queue. If the volume of these URLs exceeds the site's crawl demand, the queue becomes congested, causing valid, high-priority pages to remain indefinitely stuck in the discovered state.
Faceted navigation and parameter exponential growth
E-commerce stores and large directory sites frequently use faceted navigation to allow users to filter and sort content. When each filter selection appends a new query parameter to the URL, the number of potential URL permutations grows exponentially. A category page with multiple filters for price, color, size, and brand can generate tens of thousands of unique URL strings.
If the internal linking structure or HTML navigation allows the crawler to access every combination of these filters, the discovery pipeline fills with overlapping content. Because Googlebot treats each unique URL string as a distinct page upon initial discovery, these faceted URLs directly compete with primary category and product pages for crawl capacity. The crawler is forced to waste time evaluating massive blocks of infinite crawl space rather than fetching new, critical pages.
Unmanaged duplicate URL patterns
Beyond navigation filters, systemic duplicate URL patterns frequently overload the crawl queue. Common structural inefficiencies include:
- Session IDs or user-specific tracking parameters appended to internal links.
- Inconsistent trailing slash usage where both versions of a URL are accessible and internally linked.
- Capitalization variations in URL paths generated by inconsistent content management system routing.
- Marketing tracking parameters, such as UTM tags, improperly used on internal promotional banners instead of external campaigns.
When a site publishes a new primary page but also exposes multiple parameterized variations of that same page through its internal architecture, the crawler must queue and eventually evaluate each variant. Because the crawler must fetch a URL to read canonical tags or assess the on-page content, the discovery queue balloons before the indexing and deduplication stages even begin.
Diagnosing queue dilution
To verify if structural inefficiencies are causing a crawl backlog, examine the detailed URL table in the Discovered - currently not indexed report. Use the table filter to isolate specific URL patterns.
Filter the list using common parameter markers such as a question mark, or search for specific key-value pairs associated with site search, sorting, or session variables. If the pending URL list is dominated by faceted combinations, tracking tags, or unintended structural variants rather than canonical article or product URLs, pipeline bloat is actively diluting crawl demand. The discovery queue is functioning exactly as the site architecture instructs it to, but the architecture is feeding it an unsustainable volume of noise.
The impact of internal linking and site quality on crawl priority
The discovery queue does not process URLs in a strict first-in, first-out order. The scheduling algorithm prioritizes URLs based on their perceived importance, relying heavily on a site's internal link structure to gauge that value. When a URL enters the queue, the volume and origin of its incoming internal links directly influence how quickly the crawler initiates a fetch.
Pages that are structurally isolated frequently stall in the discovered state. Orphan pages, which are submitted via an XML sitemap but lack incoming internal HTML links, signal low priority to the crawler. Because no other pages within the site architecture point to them, the system infers they have low relative value. Similarly, deeply buried URLs that require multiple clicks from a high-traffic hub or root domain receive minimal internal link weight. The scheduler routinely places these nested URLs at the back of the queue, favoring pages with prominent, centralized internal links.
Beyond individual link paths, overall domain quality governs the underlying crawl demand. Crawl demand represents how frequently the search engine determines a site requires fetching based on its aggregate value. A broader pattern of low-value, thin, or heavily duplicated pages across a site can reduce this demand.
When a domain historically presents a high ratio of low-quality URLs, the scheduling system scales back its fetching frequency. This site-wide quality assessment impacts new content directly. Even if a newly published page features highly relevant, well-structured content, a depressed crawl demand across the broader domain can delay its initial fetch. The system allocates capacity to higher-quality domains, leaving valid new URLs on the affected site pending in the discovery queue.
Evaluating link depth and quality signals
To determine if internal linking is the limiting factor for a discovered URL, trace its click path from the homepage. If a pending URL is only accessible through deep pagination strings, secondary archive links, or exists solely in a sitemap file, its structural isolation is the likely cause of the crawl delay.
If high-priority pages are linked prominently from the homepage but still remain stuck in the discovery phase without server-side constraints, the issue is often a site-wide quality deficit. In this scenario, auditing the site for a high volume of indexed thin content, unhelpful programmatic pages, or outdated material is necessary to determine if historical site quality is suppressing current crawl demand.
SEO structure and reciprocal link analyzer
Detect orphan pages, deep click depths, and toxic reciprocal links built by careless agencies.
Remediation: Consolidating signals and managing the queue
Clearing a backlog of discovered but unindexed URLs requires actively shaping how a search engine allocates its fetching capacity. The strategy involves preserving the queue for priority pages by restricting access to infinite URL spaces, consolidating duplicate signals, and reinforcing the architectural importance of pending content.
Preserving capacity with robots.txt
The most immediate method to stop low-value URLs from entering the discovery queue is implementing Disallow directives in the robots.txt file. Faceted navigation, sort options, and unchecked search filters can generate an endless supply of unique but conceptually identical URLs. When a crawler finds these links, they bloat the scheduling system.
Blocking the specific query parameters, session identifiers, or subdirectory paths responsible for these variations prevents the crawler from requesting them entirely. This restricts the total volume of known URLs on the domain, leaving more queue capacity available for the valid pages waiting for their initial fetch.
Consolidating duplicates using canonical tags
While robots.txt prevents a crawl, strict canonical tags consolidate indexing signals for URLs that must remain accessible or have already entered the system. Implementing consistent, self-referencing canonical tags on primary pages establishes the preferred version.
For unavoidable duplicates, such as URLs with tracking parameters, affiliate tags, or alternate categorization paths, the canonical tag must explicitly point to the primary URL. Over time, this resolves signal dilution. Search engines must still fetch a URL to read its canonical tag, meaning canonicalization resolves indexation ambiguity rather than immediately saving crawl capacity. However, a highly consistent canonical implementation reduces the perceived size of the domain's unique content, which influences long-term crawl scheduling.
Realigning internal link architecture
URLs lingering in the discovery phase often suffer from structural isolation. A search engine uses the internal link graph to infer a page's relative importance. If a pending URL is located several clicks deep, lacks contextual in-links, or is only reachable through deep pagination sequences, it is assigned a lower priority.
To elevate these pages in the queue, reduce their click depth. Surface high-priority pending URLs by linking to them from the homepage, incorporating them into major category hubs, or featuring them in related-content modules on already indexed pages. Ensure all structural links use standard HTML anchor tags with href attributes, as relying on client-side routing or JavaScript event listeners can introduce unnecessary rendering delays before the link is parsed.
Reinforcing priority with XML sitemaps
An XML sitemap provides an explicit list of URLs the site owner considers valuable. To be effective in prioritizing a discovery backlog, a sitemap must be strictly curated rather than automatically generating a list of every URL on the server.
A high-quality sitemap implementation requires specific criteria:
- Include only canonical URLs returning a standard 200 HTTP status code.
- Exclude all URLs blocked by robots.txt, 3xx redirects, 4xx errors, and pages carrying a noindex directive.
- Update the lastmod attribute accurately to indicate when the core content of a page was last modified, rather than updating it dynamically on every page load.
A clean sitemap acts as a definitive reference for the scheduling system. When combined with a refined internal link structure and a queue freed from parameter bloat, an accurate sitemap clearly signals which of the discovered URLs should be prioritized for their initial fetch.
Validating fixes and requesting indexing
Once server capacity constraints are resolved and the internal link architecture is streamlined, the final step is to verify the accessibility of the affected pages and signal the search engine to re-evaluate the queue.
Confirming accessibility with the URL inspection tool
Before initiating any formal validation requests, confirm that the previously stalled pages are now fully accessible to search engine crawlers. This verification is performed using the Google Search Console URL Inspection Tool.
When you input a URL that is stuck in the discovery backlog, the initial report displays the historical index status based on the last known interaction, which will remain marked as discovered but not indexed. To assess current conditions, execute the "Test Live URL" function. This triggers a real-time fetch request, bypassing the cached status.
Review the live test results for the following criteria:
- The HTTP response returns a standard 200 status code.
- The page resources, including required scripts and stylesheets, are successfully retrieved and rendered.
- No unintentional robots.txt directives or noindex tags are present in the rendered HTML.
If the live test results in a timeout or a 5xx server error, the underlying host capacity issue or architectural bottleneck has not been fully resolved, and further queue prioritization efforts will fail.
Strategic use of manual indexing requests
If the "Test Live URL" function confirms the page is available, you can use the "Request indexing" feature. This action places the specific URL into a priority crawl queue.
The manual request tool is designed for precision, not bulk processing. It does not bypass overall host load limits or expand total crawl capacity. Submitting hundreds of URLs manually is inefficient and can dilute the priority signal. Reserve this feature for high-priority pages, such as newly launched category hubs, flagship product pages, or time-sensitive content, to accelerate their individual transition from discovered to crawled.
Initiating the bulk validation workflow
For the broader backlog of discovered URLs, the most effective approach is to use the platform's bulk monitoring feature. Navigate to the Page indexing report in Google Search Console and select the "Discovered - currently not indexed" reason to view the affected URL list.
Clicking "Validate Fix" initiates a tracking workflow. It is important to understand the mechanics of this feature: it does not force an immediate, massive recrawl of all listed URLs. Instead, it resets the reporting state for this issue from "Pending" to "Looking for an issue".
By starting the validation process, you signal to the scheduling system that the conditions causing the initial delay-such as parameter bloat or server timeouts-have been addressed. As Googlebot conducts its natural crawl cycles over the following days and weeks, it will attempt to fetch the URLs in the report. If the architectural and capacity fixes hold, the pages will successfully process, and the count of affected URLs on the validation details page will gradually decrease until the fix reaches a "Passed" state.