Fixing multi language subdomains to prevent duplicate title hits requires an exact alignment between localized metadata and the server routing architecture. When a CMS defaults to an English fallback template for French and German regional sites, search engines encounter identical title elements across separate geographic targets. This forces ranking algorithms to filter the localized pages as duplicate content. The result is a sharp drop in organic impressions.
Googlebot processes identical titles on distinct regional URLs as canonicalization errors. The indexing engine consolidates these competing pages into a single SERP entry. You lose local market visibility instantly.
Architectural localization demands strict rule sets to disambiguate regional assets. Resolving these metadata conflicts relies on executing specific technical SEO parameters:
- Deploying valid ISO 639-1 and ISO 3166-1 alpha-2 codes within the HTML structure.
- Configuring self-referencing canonical tags for every localized URL variant.
- Isolating database string translations to prevent English fallback text from bleeding into regional site titles.
- Measuring CTR degradation in Google Search Console to identify filtered international pages.
An unoptimized multi-regional network burns crawl capacity on redundant pages. Search engine crawlers waste resources comparing identical text strings instead of indexing new regional inventory. Exact geographic relevance signals keep subdomains independent in the index.
Architectural causes of metadata conflicts in localization
System failures in localized metadata originate at the database level. Incomplete database segmentation forces separate regional instances to query the same configuration tables. A CMS mapped to a unified database without strict locale isolation boundaries will leak string values across subdomains. The master language overrides regional parameters. Your localized site requests a French title string, the database returns a null value, and the server outputs the default English metadata.
Multisite network architectures compound this structural flaw. Network administrators frequently push global theme updates from a master node to all child subdomains. Hardcoded global strings residing within the core header files bypass the database entirely. The CMS reads static HTML rather than querying the localized repository.
Master node disconnects and hardcoding
Global string hardcoding strips regional context from the document structure. You deploy a customized sub-environment for the German market. The network template enforces a static site title snippet appended to every page. Every URL across the localized network inherits an exact-match suffix. Algorithmic comparison evaluates these text elements as identical.
This breakdown tracks back to specific system configuration errors:
- Translation frameworks failing to intercept core theme execution hooks.
- Empty localized custom fields triggering default fallback arrays.
- Shared configuration tables projecting unified site names across segmented network nodes.
A CMS relying on English fallback templates for empty translation strings acts as a direct catalyst for metadata conflicts. Regional content administrators upload translated body copy but leave custom metadata fields blank. The server architecture automatically defaults to the base template. Exact-match titles propagate across the entire multi-language network. System logic designed to prevent blank HTML attributes inadvertently causes catastrophic duplicate output.
Algorithmic comparison and document clustering
Search engine indexers deploy string-matching algorithms to process metadata at scale. Bots tokenize the HTML structure and measure document similarity using fingerprinting models. Identical title tags active across separate subdomains trigger immediate clustering logic. Subdomains lose their independent indexing status instantly.
The system maps a French URL and an Italian URL carrying the exact same English title. The algorithmic evaluation concludes both URLs represent the identical core entity. Duplicate content filtering isolates the anomaly. The indexer merges the competing localized assets into a single document cluster. The subordinate regional pages drop from the SERP completely.
| Architectural Flaw | System Execution | Algorithmic Outcome |
|---|---|---|
| Incomplete Database Segmentation | Queries return master language strings | Cross-domain string duplication |
| Master Node Hardcoding | Static templates overwrite dynamic requests | Metadata uniformity across subdomains |
| Fallback Template Trigger | Null translation value outputs default language | Document clustering and index filtering |
Relying on default platform routing guarantees index consolidation. Unmanaged fallback logic destroys localization frameworks at the point of crawling. Exact string matches signal redundancy. Indexing engines filter out redundant nodes.
Run a deep technical crawl to identify 4xx errors, missing meta tags, and indexation blockers.
Hreflang attribute configuration for title disambiguation
Search engines discard identical nodes unless explicit structural relationships bind them. The rel="alternate" hreflang annotation overrides default duplicate filtering by establishing a localization cluster. It forces the indexer to interpret exact-match titles across separate regional subdomains as targeted geographical variants rather than redundant content. This precise mapping stops visibility suppression instantly.
Syntax dictates system behavior. Hreflang deployment requires strict adherence to standardized codes. Parsers execute logic based on ISO 639-1 specifications for language inputs and ISO 3166-1 alpha-2 specifications for regional targeting.
The sequence remains rigid. You must declare the language code first. Geographic restrictions follow as optional parameters separated by a hyphen. Reversing this sequence or injecting unsupported formats corrupts the cluster validation process. A URL targeting French speakers in Canada requires the fr-CA value. Specifying CA-fr causes a critical parsing failure.
Deployment vectors for locational metadata
Engineering constraints dictate the chosen deployment method. You can inject these annotations through three distinct server layers. Each approach carries specific processing overhead for crawlers.
Select the deployment vector matching your infrastructure capabilities.
- HTML head block execution: Injects code directly into the document response. This method increases page weight linearly based on the number of supported regions.
- HTTP header configuration: Modifies server responses before document rendering. This acts as the sole viable solution for localizing non-HTML assets like PDF files.
- XML sitemap routing: Centralizes mapping logic away from client-side execution. It utilizes the <xhtml:link> element to define relationships in a standalone file.
Sitemap deployment scales efficiently across enterprise architectures. It eliminates code bloat from the front-end application. Crawlers process the entire language cluster during a single file fetch.
Below is the required syntax structure for declaring alternate regional nodes within a sitemap file.
<url>
  <loc>https://en.example.com/page</loc>
  <xhtml:link rel="alternate" hreflang="fr-fr" href="https://fr.example.com/page" />
  <xhtml:link rel="alternate" hreflang="en-gb" href="https://uk.example.com/page" />
</url>
Routing unmatched traffic with x-default
Clusters require a definitive fallback node. The x-default attribute governs routing logic when a visitor's browser language or IP address falls outside your specified geographic parameters. Without it, search algorithms guess the appropriate URL.
Assigning an x-default URL forces global boilerplate text and unmatched queries to a centralized domain. It absorbs unstructured traffic. You must include the x-default declaration within every node of the hreflang cluster.
The system architecture of a fully configured cluster relies on absolute reciprocity. Bidirectional referencing is non-negotiable.
Review the mandatory validation rules for constructing these relationships.
| Validation Rule | System Logic | Failure Consequence |
|---|---|---|
| Absolute URL Formatting | Parsers reject relative paths in cross-domain mappings | Cluster breakdown and index isolation |
| Self-Referencing Node | Every URL must declare its own language and region | Incomplete tag errors in search consoles |
| Bidirectional Reciprocity | Node A pointing to Node B requires Node B to point to Node A | Return tag missing errors and suppressed visibility |
Broken reciprocity destroys the architectural integrity of the cluster. If the UK subdomain points to the French subdomain, but the French subdomain fails to return the exact same signal, the search engine invalidates the entire relationship. The indexer reverts to standard duplicate content protocols. Both URLs risk SERP exclusion.
Canonicalization rules for regional differentiation
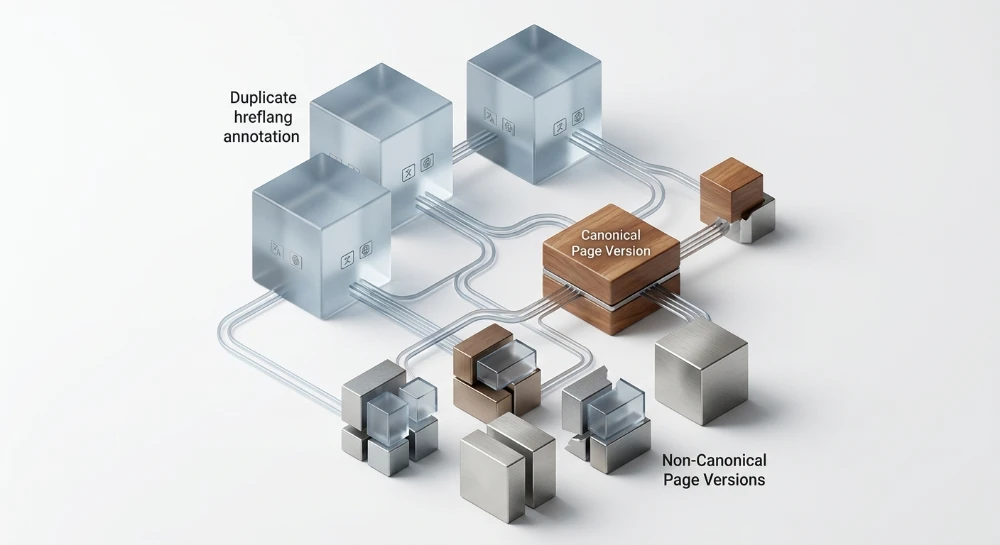
Search indexers require explicit directives to differentiate localized URLs from standard duplicate content. A common architectural flaw occurs when webmasters deploy a global canonical tag across all regional subdomains. If the Spanish subdomain sets its canonical target to the primary English root domain, the indexer obeys the directive. It drops the Spanish node from the index. Every distinct language variation demands a self-referencing canonical tag.
This localized canonical strategy tells the parser that the specific language node operates as the master version for its region. It forces the engine to evaluate the subdomain independently.
Aligning Rel="Canonical" with hreflang annotations
Canonical tags and hreflang attributes serve different database functions. Hreflang constructs a relational matrix between alternate versions. The rel="canonical" tag designates the primary HTML document for a single parameter set. These two signals must align perfectly.
A canonicalization anomaly triggers when cross-signaling occurs. If a URL claims to be the Italian variant via hreflang but sets its canonical URL to the UK variant, the system encounters a contradiction. The engine ignores the hreflang matrix entirely. It reverts to algorithmic clustering.
Review the standard mapping protocol for cross-signal alignment.
| Node Type | Hreflang Declaration | Canonical Target | Parser Action |
|---|---|---|---|
| Primary Region (US) | en-us self-reference | en-us URL | Indexes localized variant |
| Alternate Region (DE) | de-de self-reference | de-de URL | Indexes localized variant |
| Duplicate Parameter (?sort=price) | de-de self-reference | Clean de-de URL | Consolidates duplicate to clean URL |
Configuring X-Default fallbacks
The x-default URL handles unmatched geographic routing. It requires exact canonical alignment. The routing page cannot canonicalize to a specific regional node. The x-default URL must feature a self-referencing canonical.
When a bot hits the x-default document, it reads the canonical tag to verify structural independence. If the x-default redirects or canonicalizes to another localized node, the fallback logic breaks. Unmatched queries hit a dead end.
Cross-Subdomain spidering paths and SEO authority
Subdomain isolation starves localized nodes of link equity. The spidering path must allow crawlers to distribute SEO authority across the network without triggering algorithmic duplicate filtering. Reciprocal hreflang tags function as internal linking bridges. They create a crawlable matrix.
When indexers traverse these multi-directional paths, they pass fractional ranking signals between the subdomains. You consolidate domain authority without merging the URLs in the SERP.
Implement these structural requirements to secure cross-subdomain spidering.
- Assign absolute self-referencing canonical tags to every clean URL within a regional subdomain
- Point parameterized URLs back to the clean localized canonical target
- Match the self-referencing hreflang tag string exactly to the canonical tag string
- Ensure the x-default node maintains an independent self-referencing canonical directive
Misaligned spidering paths cause rapid authority decay. Bots trapped in contradictory canonical loops abandon the crawl. The engine halts indexation updates for the affected subdomains. Proper canonicalization acts as the firewall. It protects the localized content from being algorithmically consumed by the root domain.
Reverse engineer top SERP rankings and compare 50+ on-page SEO metrics to outrank competitors.
Dynamic title generation protocols and CMS fallback logic
Hardcoded template strings fail at scale. Standardizing global variables for localized inputs requires strict database segmentation. You must decouple the meta title generation from the core theme files. Implement dedicated database fields for each regional node. When the server processes a page request, the dynamic generation protocol queries the specific database row corresponding to the localized URL path. The global variable then outputs the exact regional string. No overlap occurs.
CMS platforms routinely bypass these structural controls. Localization plugins like Polylang default to automated string inheritance to prevent empty output. If a localized title field is missing data, the CMS fallback logic triggers. It pulls the string from the primary language node. This mechanism instantly generates exact-match duplicate titles across subdomains.
Audit the dynamic title generation protocols in your CMS.
- Disable global fallback logic in the localization plugin settings
- Force the database to return a null value rather than inheriting the parent node string
- Map regional custom fields directly to the header generation script
- Execute database queries that validate the presence of a localized string before rendering the HTML tag
You must configure locational meta tags to bypass exact-match titles across similar dialects. Spanish targeted at Spain and Spanish targeted at Mexico often share identical primary keywords. Programmatic generation templates relying solely on the core topic will output identical arrays. Inject geolocation modifiers directly into the string logic. Use global variables that dynamically pull the targeted region into the title string.
| CMS Generation State | Database Output | Algorithmic Consequence |
|---|---|---|
| Automated Fallback Triggered | Inherits parent string | Exact-match duplicate filtering |
| Base Keyword Generation | Identical dialect strings | Keyword collision across nodes |
| Locational Variable Injection | Region-specific string variant | Clean SERP indexing |
Automated translations exacerbate database replication. Machine translation protocols map vocabulary linearly. Linear mapping guarantees structural duplication. You must severe the API connection to automated translation services for meta elements.
Replace automated translation inputs with transcreation frameworks. Transcreation adapts the search intent and regional syntax into a distinct structural format. A transcreated title utilizes unique semantic combinations that algorithmically separate it from other language nodes. Create dedicated custom fields in the CMS for transcreated strings. Map these fields to the localized global variables. The server will render a unique HTML tag for every regional subdomain.
Crawl budget allocation and indexing bot optimization
Duplicate title tags force search engine crawlers into redundant processing loops. When multiple regional subdomains output identical meta strings, indexing bots flag the nodes as duplicate clusters. The crawler initiates algorithmic comparison checks. This verification process consumes finite crawl units.
Every HTTP request executed by Googlebot or Bingbot deducts from the allocated server crawl capacity. Serving exact-match titles across a multi-regional network drastically inflates the number of required requests. The engine fetches the primary node, identifies identical text on secondary subdomains, and immediately shifts those URLs into a low-priority crawl queue. Subsequent updates to localized pages get ignored. The bot stops fetching regional nodes entirely.
Server crawl log analysis
Server crawl logs expose the precise routing of indexing bots across your subdomains. Extract log data to identify processing bottlenecks. Look for repetitive bot hits on localized nodes that return a 200 status code but fail to index. This specific pattern indicates duplicate content filtering at the processing stage.
| Log Pattern | Bot Behavior | Diagnostic Meaning |
|---|---|---|
| High hit frequency + Low indexing rate | Stuck in clustering loop | Titles trigger exact-match duplicate filters |
| Crawl spikes on default locale only | Secondary locales ignored | Title conflict devaluing regional subdomains |
| Redundant fetches on parameterized URLs | Crawl capacity dilution | CMS generating infinite localized variants |
Stop guessing. Parse the raw server logs.
Analyze user-agent strings specifically targeting your regional subdirectories. Compare the crawl frequency of the root domain against the localized subdomains. A massive discrepancy signals that indexing bots have determined the localized nodes offer zero unique value. The identical titles act as a kill switch for regional crawl allocation.
XML sitemap architecture for Multi-Regional nodes
Bloated sitemaps sabotage crawl efficiency. Optimize XML sitemaps strictly for parsing protocols. Remove any URL from the sitemap file that generates a fallback title. If a regional node lacks a transcreated title string, exclude it from the submission queue.
- Isolate sitemap index files by specific locale parameters.
- Strip non-200 URLs to prevent bot parsing errors.
- Align location entries strictly with unique title generation fields.
- Compress large sitemap files to reduce server response overhead.
Proper sitemap segmentation controls the crawl path. Bingbot processes localized sitemaps sequentially. Googlebot evaluates priority based on internal mapping signals. Submitting thousands of localized URLs with identical title strings signals a low-quality architecture. The bot down-regulates the crawl rate for the entire domain. Clean sitemap files ensure that only nodes with distinct, localized meta elements consume server crawl capacity.
SEO structure and reciprocal link analyzer
Detect orphan pages, deep click depths, and toxic reciprocal links built by careless agencies.
Auditing workflows for Multi-Language subdomain conflicts
Identifying localized metadata overlaps requires systematic extraction at the DOM level. Manual spot-checking masks systemic architectural flaws. Desktop crawlers handle granular localized extraction. Cloud crawlers provide historical error mapping.
Configure Screaming Frog to parse the regional subdomains concurrently. Set the user-agent to Googlebot Smartphone to mimic the primary rendering path. The default Page Titles report flags exact duplicates, but custom extraction isolates the precise CMS fallback mechanisms triggering the overlap. Use XPath to extract localized title variables directly from the HTML source.
//title/text()Map this output against the main boilerplate string. If the localized node returns the root English string, the localization database failed to serve the regional variant. The node generated a hardcoded duplicate.
Sitebulb approaches the same dataset through structural clustering. Its internal engine flags missing return links and duplicate on-page elements across localized segments. Sitebulb maps the exact node paths where the regional overriding logic breaks down. The visual mapping isolates which specific subdomains trigger the architectural failure.
Scale the audit using Ahrefs Site Audit or Semrush Site Audit for continuous monitoring. Cloud platforms bypass local hardware bottlenecks when crawling enterprise sites with millions of localized URLs.
Navigate to the Semrush Site Audit interface. Access the Issues tab. Filter the error log strictly for duplicate title tags. Export this localized list. Cross-reference the affected URLs with the Ahrefs Site Audit Localization report. This intersection pinpoints whether the duplicate metadata correlates directly with missing localization attributes or a deeper CMS routing failure.
| Audit Platform | Extraction Method | Primary Diagnostic Output |
|---|---|---|
| Screaming Frog | XPath / Regex Custom Extraction | Raw DOM text output for fallback pattern matching |
| Sitebulb | Pre-configured International Rules | Visual map of broken regional node clusters |
| Ahrefs Site Audit | Cloud Server Parsing | Localization report highlighting unlinked regional pages |
| Semrush Site Audit | Scheduled Cloud Crawls | Trended historical log of duplicate title tag errors |
Validating return tags and regional clusters
Metadata disambiguation relies heavily on properly linked regional nodes. Missing return tags break the relationship completely.
Deploy Merkle's hreflang tags testing tool to validate the architecture. Input the root URL. The parser fetches the live HTML and builds the defined localization cluster. It immediately flags missing bidirectional return links. A single missing return tag invalidates the entire regional cluster for that specific document. Fixing the localized title tag accomplishes nothing if the regional grouping remains technically invalid. The tool confirms whether the declared ISO codes match the actual rendered HTML response.
Cross-Referencing Google search console diagnostics
External crawler data represents theoretical architecture. Search engine data represents actual indexing reality.
Aggregate the performance data using Google Search Console Platform Properties. This aggregates metrics across all regional subdomains into a single master property view. Export the Page Indexing report data via the API. Filter for URLs marked as Duplicate without user-selected canonical.
Match this export against your Screaming Frog custom extraction sheet.
- Identify URLs flagged by internal crawlers for duplicate titles.
- Check if Google Search Console lists those exact URLs as canonicalization anomalies.
- Isolate nodes where the International Targeting report historically flagged language mismatch errors.
- Map the isolated URLs back to the CMS database segment responsible for title generation.
The International Targeting report highlights legacy parsing errors regarding ISO code misconfigurations. Even as reporting interfaces evolve, cross-referencing extracted crawler duplicates against actual indexed anomalies dictates the priority queue for technical remediation. Resolve the database fallback causing the exact-match string, validate the bidirectional links, and push the localized URLs back into the index pipeline.
Tracking organic search performance and SERP display anomalies
System adjustments require empirical verification. Once metadata conflicts are cleared from the multisite architecture, traffic routing algorithms must stabilize. Extract pre-resolution and post-resolution CTR metrics from the API. Isolate this data down to the specific multi-language subdomain level. Compare the performance of exact-match brand queries against non-brand query spaces.
Successful disambiguation yields a sharp CTR increase for localized URLs. Users stop seeing generic fallback snippets and begin clicking on region-specific titles.
Monitoring title rewrites and keyword cannibalization
Search engine algorithms frequently override HTML title tags during the rendering phase. If the CMS generates a perfectly localized title but the SERP displays a truncated or global fallback string, an architectural flaw remains active. Monitor these display anomalies rigorously. AI-driven SEO platforms possess the capacity to detect text variations between the parsed HTML and the final rendered snippet at scale. Pull this variance data weekly.
Analyze the URL collision data to identify keyword cannibalization vectors:
- Overlapping ranking URLs within the identical geographic index.
- Erratic fluctuations between language-specific subdomains for a single target query.
- Suppressed search visibility caused by algorithmic filtering of competing regional pages.
Track keyword rankings across isolated query-spaces. A query-space represents the distinct mathematical intersection of a specific keyword, user location, and device type. Configure your tracking infrastructure to ping regional search engine endpoints directly. If a local search query executed in Paris surfaces the Canadian French URL instead of the European French URL, the routing logic has failed. Cross-reference this ranking data against server log analysis to determine if indexing bots are prioritizing the wrong geographic cluster.
Geographic targeting anomalies and search intent validation
Traffic volume metrics hold zero value if geographic targeting is misaligned. Scrutinize the regional source of incoming clicks. If an aggressive spike in organic traffic registers on a Latin American subdomain but the IP origins indicate users in Spain, a geographic targeting anomaly exists.
Deploy intent validation metrics to diagnose the severity of the misalignment.
| Metric | Optimal State | Anomaly Indicator |
|---|---|---|
| Regional Click Share | Dominant click volume from target geo-IP ranges | High session counts from off-target geographic regions |
| Query Localization | Ranking velocity for region-specific long-tail terms | Ranking strictly for generic root keywords globally |
| CTR Consistency | Stable or climbing CTR per isolated query-space | Erratic CTR drops signaling algorithmic title rewrites |
Search intent validation metrics expose the operational gap between technical configuration and user reality. Evaluate session abandonment rates segmented by geographic location. Users landing on the incorrect localized version terminate the session immediately. This behavior transmits a failed intent match signal to the ranking algorithm. A negative feedback loop initiates, actively degrading the SEO performance of the affected subdomain. Continuous extraction of ranking logs and API diagnostic data establishes the baseline required to detect these routing failures before they trigger mass index exclusion.