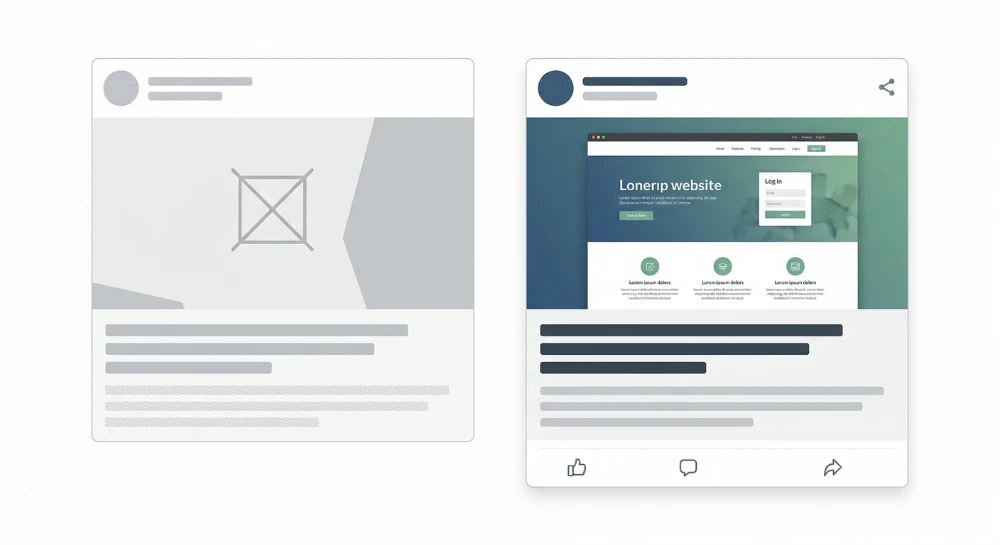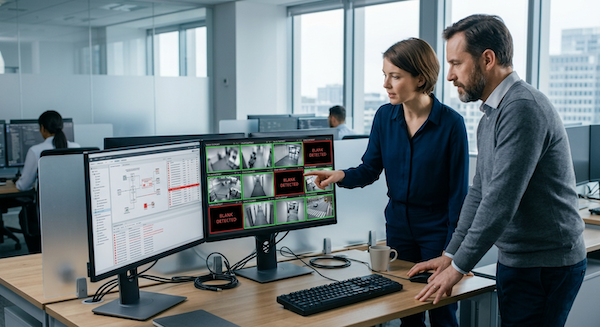
Using automated body payloads checks for blank windows detection maps rendering pipeline failures before they trigger indexing drops. Search engines process millions of URLs daily through automated headless browsers. When JavaScript execution halts prematurely, bots receive a 200 HTTP status code paired with a zero-byte payload. The interface remains blank. This forces algorithms to rank empty space instead of the intended content.
The technical audit scope demands isolation across CSR, SSR, and hybrid SPA architectures due to their distinct processing logic. A CSR setup forces the client device to build the entire view from bare HTML. If the primary bundle fails to execute within the designated timeout threshold, the system delivers an empty container to the crawler. SSR attempts to bypass this by pushing pre-rendered code directly from the server. Hydration mismatches still break the final paint.
Modern indexing relies on WRS. This specific service runs on Headless Chromium to parse dynamic elements. Network protocols directly dictate the success rate of these rendering cycles. HTTP/2 multiplexing allows concurrent script fetching to prevent render-blocking delays. Legacy HTTP/1.1 restricts requests to sequential loading queues. If network congestion interrupts the data stream during evaluation over either protocol, the engine immediately abandons the process and caches the null response.
Architectural causes of Client-Side rendering failures
Two-wave indexing splits crawl operations into distinct phases. The initial pass captures the raw source code immediately upon request completion. The rendering engine then queues the URL for processing when computing resources become available. This execution delay creates a critical vulnerability for dynamic applications. The gap between the Initial HTML Response and the fully constructed DOM content load often triggers processing failures. Bots drop the session if the deferred execution phase exceeds timing thresholds. The system indexes an empty shell.
Modern component frameworks rely heavily on client-side state generation. React and Vue ship empty structural containers by default. The crawler downloads a bare file containing a root div and large bundled scripts. DOM content load stalls until the engine parses, compiles, and executes these instructions. Bots evaluate page readiness during this exact interval. A blank window manifests because the engine finalizes the snapshot before the virtual DOM mounts physical elements to the UI tree.
Component architecture and fetch failures
Component-based architecture bottlenecks indexing pipelines through nested dependencies. Parent containers block child rendering until their own lifecycle methods complete. Asynchronous data fetching failures multiply this risk exponentially.
Applications frequently dispatch multiple fetch requests to headless CMS endpoints during the mount phase. If an API endpoint responds slowly, the crawler assumes the blank state is the intended final render. Data races occur. Components load without necessary payload fragments.
- Unresolved Promises block the main thread and halt downstream execution.
- Deep component trees trigger sequential waterfall requests instead of parallel loads.
- Third-party script injection interrupts core bundle parsing operations.
- State management libraries lock the UI during asynchronous updates.
Hydration attempts to bridge the gap between static markup and interactive states. Errors here are destructive. A hydration mismatch happens when the pre-rendered HTML structure conflicts with the client expectations during the attach phase. The framework aggressively strips the pre-generated DOM. It falls back to a clean CSR cycle to resolve the conflict. If crawler timing catches this exact swap, the bot parses a completely blank window. The fallback cycle takes too long to execute.
Timing metrics dictating pipeline success
System performance directly dictates rendering completion rates. Crawlers operate on strict internal budgets. They abandon slow environments without warning.
| Metric | Pipeline Vulnerability | Rendering Impact |
|---|---|---|
| TTFB | Delays the entire Two-wave indexing queue before evaluation starts. | High TTFB forces crawlers to abort the initial HTML request, preventing script execution entirely. |
| Time to Interactive | Measures main thread availability during script compilation. | Late Time to Interactive signals heavy execution blocking, causing rendering timeouts. |
| Latency | Measures network round-trip delays for secondary resources. | High Latency breaks asynchronous data fetching, resulting in empty component states. |
Run a deep technical crawl to identify 4xx errors, missing meta tags, and indexation blockers.
Network-Level diagnostics and API payload anomalies
Modern applications construct their interfaces dynamically through continuous network exchanges. The frontend logic requests data structures from the backend. The backend replies with raw JSON strings. Parsing the REST model correctly directly determines what content populates the final node tree. When this data pipeline breaks, the framework mounts an empty app shell. The interface renders without primary content.
Crawlers parse network traffic aggressively. They abandon stalled requests to preserve compute resources.
REST endpoint failures and method misconfigurations
Search engine bots follow strict stateless protocols. They execute idempotent requests. They do not trigger state-changing methods during rendering cycles. Evaluating PUT endpoint requests and POST requests reveals a common architectural flaw in SPA architectures. Developers frequently route search queries, filter states, or pagination commands through POST endpoints instead of URL parameters. The crawler intercepts the component logic attempting a POST request. It blocks the execution.
The REST endpoint failure occurs silently in the background. The server never receives the payload request. It returns nothing to the frontend. The rendering engine outputs empty body payloads where the core text should exist.
- GET endpoints guarantee crawler execution for data fetching.
- POST requests trigger security blocks within indexing environments.
- PUT endpoint requests fail validation during the initial scan phase.
Analyzing HTTP headers for streaming integrity
Network infrastructure dictates payload delivery via specific header directives. Proxies, CDNs, and load balancers must coordinate exact byte counts. Discrepancies here terminate the connection before the JSON string completes.
Engineers must audit the following HTTP headers during network transmission.
| Header Directive | Failure Mechanism | Rendering Outcome |
|---|---|---|
| Content-Length | The server declares a byte count smaller than the actual JSON payload. The crawler stops reading at the declared limit. | The parsing engine encounters a truncated JSON object. A syntax error crashes the rendering cycle. |
| Transfer-Encoding: chunked | The server streams data continuously but fails to send the zero-length terminating chunk. | The network thread hangs in an infinite wait loop. A hard timeout triggers an empty output. |
Chunked encoding bypasses the need for initial byte calculation. It streams dynamic content efficiently. Breaking the chunk sequence forces the rendering engine to discard the entire buffer.
Protocol layer frames and HTTP/2 stalls
Multiplexing over a single TCP connection introduces new failure points. HTTP/2 protocol frames divide API responses into discrete binary packets. The application layer rebuilds these packets into readable data.
A standard network response requires continuous DATA frames. The stream remains open until the server transmits the END_STREAM flag. If a backend database query hangs midway through compiling the JSON payload, the server stops transmitting DATA frames. It does not send the END_STREAM signal. The crawler network stack waits. It cannot differentiate between network latency and a dead backend process. The stream eventually hits a built-in timeout limit. The framework receives partial or zero data.
JSON serialization errors and soft 404 triggers
Backend exceptions frequently mask themselves behind successful network responses. An API encounters a database error while querying the main article text. Instead of throwing a 5xx status code, the backend catches the error poorly. It serializes a null value or an empty array. It returns a 200 HTTP status code.
The network layer reports total success. The frontend receives the payload.
API JSON serialization errors inject null client code data directly into the component state. The JavaScript logic maps over the empty array. It outputs zero child elements. The final DOM output contains navigation links, footers, and sidebars, but absolutely no primary content. Search engines index this exact state.
The 200 HTTP status code instructs the indexer that the page exists and functions properly. The absence of primary text algorithms categorizes the URL as defective. The indexing engine registers a Soft 404 error. The URL gets purged from the SERP. Identifying these anomalies requires deep inspection of the raw API payloads independent of the document status codes.
Configuring headless browsers and edge rendering solutions
Dynamic rendering environments route crawler traffic to pre-rendered DOM snapshots while serving standard client-side bundles to human visitors. This dual-path architecture requires strict monitoring to prevent cloaking anomalies and blank HTML outputs. Deploying intermediate rendering layers demands exact timeout configurations.
Puppeteer provides direct programmatic control over the Chrome DevTools Protocol. Engineers script custom wait conditions based on network idle events. A premature snapshot captures an empty body payload. You must intercept and abort non-essential network requests like analytics pixels and heavy media files during the Puppeteer execution phase. This minimizes main thread blocking.
Rendertron acts as a self-hosted middleware server. It spins up Headless Chromium instances on the fly. Memory leaks frequently degrade local Rendertron deployments. The browser processes fail to garbage-collect terminated tabs, eventually crashing the host machine.
Prerender.io offloads the compute burden to a managed cloud infrastructure. Caching dominates the architecture here. The engineering bottleneck shifts from CPU management to cache invalidation logic. Stale cached HTML serves outdated links to the SERP.
Server execution limits and resource isolation
Headless Chromium requires immense computational power to parse and execute large JavaScript bundles. Server-side rendering execution limits dictate system stability under high crawl demand. Concurrent page rendering tasks cause severe CPU contention.
- Disable GPU hardware acceleration in the launch arguments
- Cap maximum concurrent browser contexts based on available RAM
- Set hard navigation timeouts to terminate hanging DOM building processes
- Block CSS and font files to accelerate the critical rendering path
Resource-intensive rendering tasks often fail due to unsupported ECMAScript features within the crawler environment. Injecting polyfills bridges this execution gap. Polyfills modify the runtime environment to support modern API calls in outdated JavaScript engines. Unconditional polyfill injection bloats the memory footprint. Detect the user agent string and serve polyfills exclusively to legacy bots.
| Rendering Engine | Deployment Model | Primary Technical Bottleneck |
|---|---|---|
| Puppeteer | Custom Node.js scripts | Complex script maintenance and memory leaks |
| Rendertron | Self-hosted middleware | Scaling concurrent Headless Chromium instances |
| Prerender.io | Cloud-based caching | Cache invalidation delays |
Edge computing validation via Cloudflare workers
Edge computing platforms execute JavaScript logic globally before the request reaches the origin server. Cloudflare Workers utilize V8 isolates to inspect and manipulate traffic at the CDN layer. This provides a robust intercept mechanism for rendering failures.
The worker script intercepts the network response. It reads the outgoing HTML payload. You can program the edge logic to evaluate the structure of the returned string. If the origin server returns a 200 HTTP status code but the parsed document contains an empty root div, the edge environment intervenes.
The worker reads the incoming request.body and parses the intended destination. It formats HTTP response strings on the fly. Instead of passing the defective zero-byte DOM to the indexer, the edge script rewrites the header. It returns a 503 HTTP status code. The crawler delays indexing. The SERP rankings remain protected from blank page anomalies.
Bulk Google and Yandex index checker
Verify agency reports and track live SERP status in Google and Yandex to protect your SEO ROI.
Automating DOM verification via command line interfaces
Manual payload verification fails at scale. System administrators require automated CLI validation algorithms to continuously monitor rendering outputs across thousands of endpoints. Command line tools bypass caching layers. They reveal the raw network response exactly as a crawler receives it. This direct interrogation isolates rendering failures before they propagate to the index.
Engineers deploy cURL to simulate complex client requests and inspect the resulting payload structure. Standard GET requests often mask underlying rendering issues. You must configure cURL execution with specific parameters to expose true server behavior during application initialization. Inject test payloads via CURLOPT_POSTFIELDS to force the origin server to process dynamic components and trigger the rendering pipeline.
You must append CURLOPT_HTTPHEADER to intercept the response headers and parse Transfer-Encoding directives. Modern applications frequently stream responses using chunked encoding. When a backend rendering engine crashes mid-execution, premature termination leaves no error trace in standard web logs. The connection simply drops. Parsing the chunked output via CLI exposes truncated HTML structures and missing closing tags.
Node.js automated validation scripts
Shell commands lack the concurrency required for enterprise audits. Node.js scripts provide parallelized validation architectures for massive URL sets. Engineering teams deploy libcurl bindings within custom scripts to fire high-concurrency requests against staging and production environments. This bypasses the overhead of headless browsers.
You initialize http2.createSecureServer to handle multiplexed streams. This accurately mirrors modern crawler protocols. The script listens for incoming streams and calculates the response buffer length in real-time. Any payload evaluating to a length of zero triggers a critical alert. This deterministic check identifies zero-byte DOMs instantly. The script logs the precise URI and timestamp for debugging.
- Initialize the script to request the target URL using HTTP/2 protocols.
- Extract the HTTP response code from the initial header frame.
- Buffer the incoming stream payload into memory.
- Calculate the byte size of the parsed HTML document.
- Log a critical failure if the byte size equals zero despite a successful connection.
Diagnostic contrast: HTTP status codes in rendering timeouts
Status code configurations determine whether a rendering timeout causes an indexing catastrophe or a safe crawl delay. You must evaluate the HTTP header output systematically. Silent rendering timeouts are the most destructive architectural flaw in a SPA.
A silent timeout occurs when the backend rendering service hits an execution limit but the origin server fails to catch the error. The application shell returns immediately. The content remains blank.
| HTTP Header Output | Server Behavior | Crawler Action |
|---|---|---|
| Response code 200 | Returns zero-byte DOM or empty app shell | Indexes the blank page and overwrites SERP snippets |
| 500 internal server error | Fails to render and explicitly throws backend exception | Aborts indexing and preserves previous cache |
| 5xx HTTP status codes | Upstream timeout at the rendering middleware layer | Schedules a retry for the crawler without ranking penalty |
Response code 200 validates success to the machine. If the application returns a 200 HTTP status code alongside an empty body, the crawler processes the empty payload as the new, canonical version of the document. Rankings collapse. Traffic stops.
Returning a 500 internal server error or other 5xx HTTP status codes acts as a fail-safe. When your CLI validation algorithms detect a rendering timeout, the server must be configured to format the header explicitly as a 5xx failure. This forces search engine bots to halt processing. They discard the defective payload. The historical index remains intact until the architectural bottleneck resolves.
Deploying site audits for asynchronous DOM extraction
Validating the rendered DOM at scale requires specialized configuration within enterprise crawlers. Standard static extraction parses the initial server response. This misses delayed payloads. The baseline HTML means nothing when the content matrix relies entirely on client-side execution. You must configure the crawler to initiate the rendering pipeline, intercept the asynchronous requests, and parse the document only after the data structure stabilizes.
Crawler configuration paths vary, but the architectural objective remains identical. The software must spin up a headless instance, allocate execution memory, and capture the final state of the application shell.
| Enterprise Crawler | Exact Configuration Path | Execution Directive |
|---|---|---|
| Screaming Frog | Configuration > Spider > Rendering > JavaScript | Enable "Store HTML" and "Store Rendered HTML" to compare DOM states. |
| Sitebulb | Project Setup > Crawler Settings > Chrome Crawler | Toggle "Save HTML" to audit the final assembled payload. |
| DeepCrawl | Project Settings > Spider Settings > Enable JavaScript Rendering | Activate custom scripting configurations for complex SPA models. |
| OnCrawl | Crawl Profile > Spider Configuration > Execute JavaScript | Specify page load delay thresholds to match known API latency. |
Setting JavaScript execution parameters
Default crawler settings mask rendering bottlenecks. The execution environment requires strict parameter control to accurately mirror bot behavior. Timeout limits govern the parsing window. If you leave the default threshold at 5 seconds and your backend API responds in 6 seconds, the crawler extracts an empty app shell. Force the timeout limit to 10 seconds during diagnostic crawls to determine if the payload is missing entirely or simply delayed by network latency.
Capture runtime failures directly from the rendering engine. Enable error logs tracking JS console output within the crawler settings. When an asynchronous component fails to mount, the console logs the exact exception. Uncaught reference errors, syntax blocks, or cross-origin request violations render directly in these logs. Exporting this log analysis isolates the exact script causing the system failure.
Custom extraction regex for specific HTML tags
An empty body payload often disguises itself behind a fully populated global navigation and footer. The crawler registers a 200 status code. The header parses successfully. The actual central content remains completely blank. Relying on global word counts fails to detect this architectural flaw.
Deploy custom extraction regex for specific HTML tags to verify the core content injection. Target the specific container classes designated for the API payload.
- Product grid extraction:
<div class="product-grid">(.*?)</div> - Article body validation:
<article[^>]*>(.*?)</article> - Pricing array verification:
<span data-sku="[^"]*">([^<]+)</span>
If the custom extraction regex returns a null value for these specific HTML tags, the asynchronous DOM extraction failed. The application logic fired, but the data binding aborted. This isolates the precise technical error.
Evaluating the app shell model deficits
The app shell model frequently defers crucial SEO meta injections until the asynchronous data fetching completes. A failure to populate the app shell strips the document of its core indexing directives. The visual UI might load a spinning loader, but the structural code remains critically compromised.
- Missing Canonical URLs: The baseline HTML contains no canonical tag, or it contains a static fallback pointing to the root URL. The script intended to inject the exact canonical URL aborts during the timeout. Search engines index the parameterized version. Duplicate content clusters form immediately.
- Broken Structured Data: JSON-LD scripts rely on the dynamic payload to populate product prices, stock status, and aggregate review counts. When the fetch fails, the JSON-LD remains empty, partially invalid, or traps the crawler in an open script tag block. Rich snippet eligibility is revoked.
Filter your crawler reports to highlight the delta between raw and rendered states. Isolate URLs where the Canonical URL exists in the rendered DOM but vanishes when the timeout limit drops by two seconds. If structured data validation fails only on high-latency extraction passes, the system is actively serving empty body payloads under server load constraints. Rankings drop. Traffic stops. The component architecture requires immediate refactoring.
SEO structure and reciprocal link analyzer
Detect orphan pages, deep click depths, and toxic reciprocal links built by careless agencies.
Google search console and DevTools profiling protocols
System diagnostics require immediate examination of the Page Indexing report. Focus on the 'Discovered - currently not indexed' status bucket. This category frequently signals systemic render stalling rather than content quality issues. When a rendering queue overloads, search engines defer processing. Correlate these spikes directly with the Crawl Stats Report.
Navigate to the hostload data. Watch for sudden drops in crawl requests paired with high average response times. Hostload constraints dictate crawl demand limits. If the server delays script execution or drops database queries during high concurrency, bots abandon the fetch attempt. The system logs a partial read. The URL remains discovered but unindexed.
Fetch and render validation
Manual validation demands exact render emulation. Deploy the URL Inspection Tool. Execute a live test. Do not rely on the source code view. Open the tested page tab and inspect the rendered HTML output. Search for critical nodes that rely strictly on asynchronous population.
If the main text payload is missing, the render process timed out before data binding completed. The Rich Results Test provides an alternative rendering environment with different internal timeout constraints. Run the exact same endpoint through both interfaces. Discrepancies between the two output logs confirm edge-case latency issues. A failure in one tool but success in the other proves the server is operating directly on the border of acceptable timeout limits.
DevTools execution profiling
Client-side execution profiling isolates the exact breaking point of the render path. Open DevTools. Navigate to the Network tab. The sequence of asset loading dictates the final state of the DOM.
| Network Parameter | Diagnostic Target | Execution Impact |
|---|---|---|
| 3G Throttling | Latency threshold emulation | Mirrors crawler timeout limits for script execution |
| Fetch XHR Filtering | API endpoint stability | Identifies dropped payloads leaving empty nodes |
| Disable Cache | Cold state processing | Forces full parsing of the initial HTTP response |
Evaluate the console output for specific JS errors disrupting the render cycle.
- Unhandled promise rejections halt the component tree execution entirely.
- Syntax errors in third-party scripts block the main thread.
- CORS policy violations on external data endpoints return empty variables to the DOM.
Status code triggers and bot interaction
Server log analysis must isolate traffic from Googlebot and OAI-SearchBot. High-frequency API calls triggered by client-side frameworks often activate automated security protocols. The server responds with HTTP 429 status codes. The crawler receives no data. The bot indexes an empty body payload.
Aggressive rate limiting architectures backfire during standard crawl passes. Configure server logs to filter strictly by user agent. Map HTTP 429 and HTTP 410 responses against specific crawler ranges. An HTTP 410 intentionally signals permanent removal. Misconfigured API gateways throw this status when script assets fail to authenticate. The bot obeys the directive immediately. The URL drops from the SERP. Adjust firewall thresholds and rate limiting logic for verified crawler IP addresses to secure the rendering pipeline.