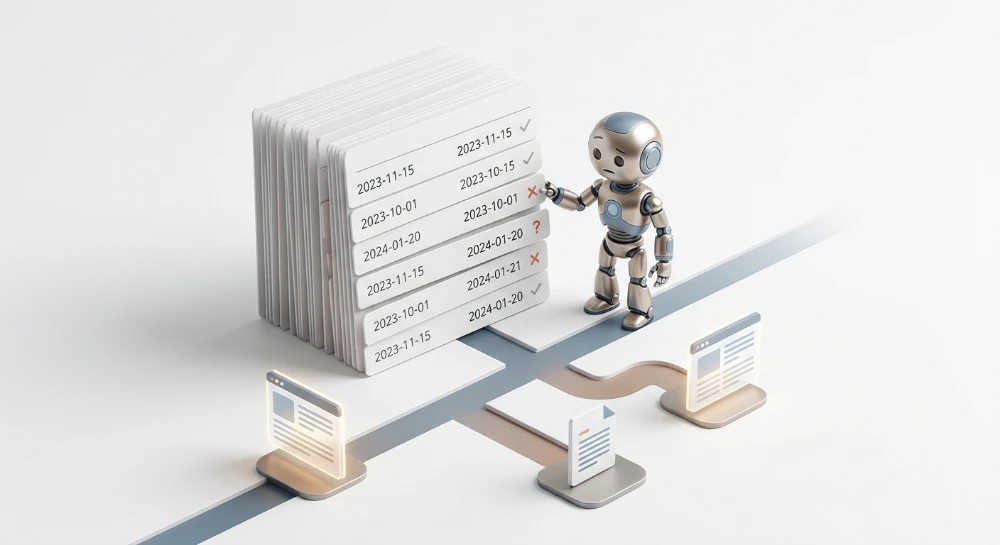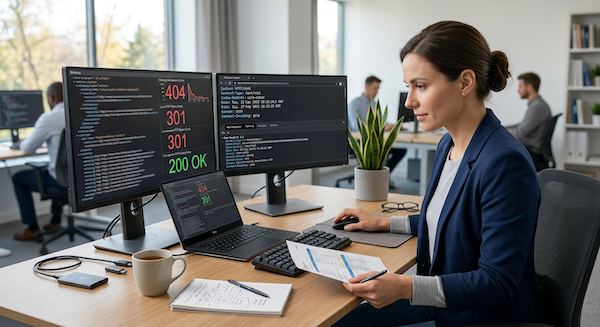
Matching live server response headers against actual sitemap errors establishes the baseline for indexation control. A sitemap file adhering strictly to the sitemaps.org protocol functions as a primary routing mechanism for crawler discovery. Desynchronization occurs immediately when XML directives point to endpoints returning anything other than a standard 200 OK HTTP status code. The Google Search Console Index Coverage Report exposes these specific mismatches between declared paths and actual live server states.
Eliminating Soft 404s and infinite redirect loops directly protects your crawl budget. Search engine bots deprecate trust in an XML configuration if the HTTP status discrepancy rate exceeds a 1% threshold.
Technical execution of sitemap-to-server synchronization mandates mapping database generation logic directly to the final live HTTP header status codes. A crawler issues HTTP GET requests based entirely on the loc tags provided within the XML structure. If the server responds with a 301 Moved Permanently or 302 Moved Temporarily, the bot executes a secondary request to resolve the final destination URL. This redundant hop consumes server resources and mathematically reduces total indexing capacity per crawl session. Cross-referencing raw server log analysis against Google Search Console export data isolates the exact timestamp of 304 Not Modified events versus 5xx server configuration failures.
Validating indexation parameters requires monitoring specific server response metrics directly tied to the XML standard:
- XML mapping protocols strictly dictate a maximum limit of 50,000 URLs per single sitemap file uncompressed under 50 megabytes.
- Elimination of 500 Internal Server Error and 503 Service Temporarily Unavailable status codes from the XML structure prevents temporary de-indexing of high-value endpoints.
- Verification of 304 Not Modified headers reduces unnecessary recrawling of static HTML documents.
Architectural foundation: XML sitemaps vs. dynamic server routing
Crawler ingestion strictly depends on architectural conformity to the sitemaps.org protocol. The foundation requires a rigid XML structure wrapping every URL declaration. A missing namespace declaration renders the entire payload invalid.
<?xml version="1.0" encoding="UTF-8"?>
<urlset xmlns="http://www.sitemaps.org/schemas/sitemap/0.9">
  <url>
    <loc>https://example.com/page-path/</loc>
    <lastmod>2023-10-14T17:30:00+00:00</lastmod>
  </url>
</urlset>
The xmlns attribute dictates the schema validation rules for the parsing bot. The urlset serves as the primary container. The loc tag defines the exact absolute URL. Any deviation from this node hierarchy triggers a system failure at the parser level. Bots drop improperly formatted nodes immediately.
HTTP header Content-Type directives
Search engines ignore file extensions. They evaluate the HTTP response headers.
Serving an XML file with a text/html Content-Type constitutes a critical architectural flaw. The server must explicitly declare the payload type in the response headers. Valid MIME types are strictly application/xml or text/xml.
Character encoding requires explicit definition as charset=utf-8. ASCII or ISO-8859-1 encodings corrupt special characters in the URL paths. Corrupted paths initiate crawl traps and waste rendering resources.
Static XML generation versus dynamic routing rules
Engineering teams implement sitemap generation through two distinct architectural models. Static generation relies on batch processing. Dynamic routing intercepts requests and generates responses on the fly.
| Architecture | Execution Model | Resource Consumption | Risk Factor |
|---|---|---|---|
| Static XML | Scheduled cron jobs writing physical files to disk. | Low server overhead during crawler requests. | High risk of data staleness between batch executions. |
| Dynamic Routing | CMS application logic generating XML upon HTTP request. | High database load if unoptimized. | Timeout errors during query execution for large URL sets. |
Static files offer raw speed. Dynamic routes offer immediate precision.
Modern CMS frameworks lean entirely on dynamic routing. When a bot requests the map, the application executes a database query, filters active records, formats the output into XML, and serves it directly from memory.
W3C datetime constraints
The lastmod tag communicates update frequency. Bots penalize improper formatting by ignoring the directive entirely. The syntax must adhere strictly to the W3C Datetime format.
- Complete date plus hours and minutes:
YYYY-MM-DDThh:mm:ssTZD - Date only:
YYYY-MM-DD
Timezone designators are mandatory if time is specified. Outputting a localized string invalidates the timestamp. Accurate datetime parameters form the baseline for future optimization cycles.
The desynchronization mechanism
Desynchronization occurs when database records fail to mirror live indexable pages. The sitemap outputs one reality. The web server routes a different one. This structural drift degrades crawl efficiency.
Several technical bottlenecks cause this drift:
- Asynchronous caching layers holding stale HTML while the dynamic XML updates instantly based on backend triggers.
- Application routing bugs where a product is marked active in the CMS database but lacks assigned taxonomy, resulting in a dead end on the frontend.
- Scheduled publishing delays where the database outputs the URL to the sitemap before the deployment pipeline pushes physical assets to the origin server.
A query might pull 10,000 published articles from the database to populate the urlset. If the application frontend routing logic requires a secondary relational check that fails, those URLs yield empty documents or routing errors. The crawler extracts the loc, executes the request, and encounters a structural dead end. Aligning the database generation query exactly with the frontend routing constraints prevents this resource drain.
Run a deep technical crawl to identify 4xx errors, missing meta tags, and indexation blockers.
Validating sitemap integrity and Content-Type responses
Sitemap generation means nothing if the delivery mechanism fails. Bots demand strict protocol adherence during the fetch phase. An immaculate XML structure fails entirely if the server delivers it with incorrect HTTP headers or broken character encoding. Validation requires verifying the exact payload and transport metrics the crawler processes.
HTTP header and MIME type conflicts
A prevalent system failure occurs when the server misinterprets the dynamic route generating the sitemap. The server transmits a Content-Type: text/html response header. It must send application/xml or text/xml. The bot expects strict XML parsing constraints. Receiving an HTML declaration causes a parsing conflict when it immediately hits the initial XML directive. The fetch aborts. You must configure the server block or application routing layer to declare the correct MIME type.
Character encoding introduces a secondary failure point. The protocol strictly requires UTF-8. Serving a payload encoded in ISO-8859-1 while declaring UTF-8 in the document head creates a fatal mismatch. The crawler drops the file. URLs containing special characters trigger immediate parsing errors without explicit UTF-8 encoding in both the HTTP header and the XML declaration.
Diagnostic tooling for payload verification
Browser rendering hides raw server data. You must inspect the actual response parameters to diagnose delivery failures.
Open the Chrome DevTools Network tab. Request the sitemap URL. Select the specific document in the network queue to expose the raw Response Headers. A dedicated HTTP Headers Viewer provides similar raw outputs for rapid audits. Standard browsers silently correct minor schema errors, making visual inspection useless. Pass the absolute URL through an XML Sitemap Validator to detect tag closure errors and namespace violations that bypass header checks.
Core delivery parameters
| Validation Parameter | Required Standard | Diagnostic Tool | Failure Impact |
|---|---|---|---|
| Content-Type | application/xml or text/xml | HTTP Headers Viewer | Bot aborts parsing; file treated as invalid HTML. |
| Character Encoding | charset=utf-8 | Chrome DevTools Network tab | Fatal parsing error on non-ASCII URL characters. |
| Schema Integrity | Valid sitemaps.org namespace | XML Sitemap Validator | Extraction failure for nested loc nodes. |
| File Size | Uncompressed size under 50MB | Network tab payload size | File rejection; partial indexation of the URL set. |
Server response latency and payload compression
Latency throttles crawl capacity. Generating a massive URL index dynamically places heavy load on the CMS database. If server response latency spikes during this query sequence, the connection times out. Bots abandon the request. High latency indicates an architectural flaw in the dynamic generation script requiring immediate caching intervention.
Text files are highly compressible. A massive sitemap consumes unnecessary bandwidth if transmitted raw. You must implement gzip compression at the server level. Inspect the response headers for Content-Encoding: gzip. A large file typically compresses down to roughly ten percent of its original size. Uncompressed delivery directly drains your allocated bandwidth and slows the bot fetch cycle. Optimize the transport layer before scaling the URL output.
Resolving URL desynchronization: 4Xx and 5xx errors in XML directives
URL desynchronization occurs when a CMS generates XML nodes for obsolete or inaccessible paths. The database assumes the page exists. The server routing protocol disagrees. Submitting a URL via sitemap mandates a clean success header. Any deviation into 4xx or 5xx territory wastes processing cycles and degrades domain trust. You must reconcile the gap between database query outputs and actual live server HTTP headers.
Diagnostic extraction via index coverage report
Navigate directly to the Index Coverage Report. Filter by the submitted sitemaps scope. You are looking for specific error clusters that indicate a severe disconnect.
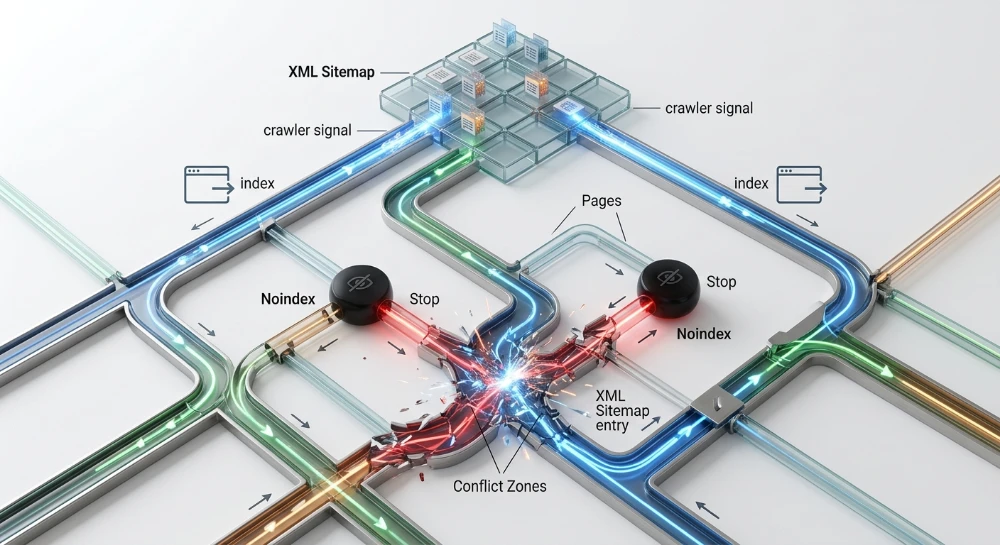
The 'Submitted URL marked noindex' error presents a direct contradiction. Your XML map demands indexation while your HTML meta robots or HTTP response headers explicitly block it. This conflict paralyzes the indexer. It forces bots to fetch the page, process the header, discover the exclusion block, and drop the payload. The processing bandwidth is already burned.
'Soft 404 Errors' require deeper architectural scrutiny. The CMS returns a success status code for a broken path, missing product, or empty category. Search engines detect the lack of primary content and classify the path as invalid despite the header state. '404 Not Found' errors trigger when the database retains a record of a deleted node, injecting a dead endpoint into the active sitemap sequence.
Differentiating routing protocols for 4xx and 5xx states
Not all server errors require the same remediation protocol. Precision matters. Bots handle distinct status codes with entirely different crawl prioritization logic.
Review the standard error states encountered during desynchronization audits.
| Status Code | Diagnostic Meaning | Resolution Protocol |
|---|---|---|
| 404 Not Found | Resource missing. Database out of sync with active file structure. | Purge URL from database query generating the sitemap. |
| 410 Gone | Resource intentionally and permanently deleted. | Remove from sitemap immediately. Accelerates bot deindexation. |
| 403 Forbidden | Server denies access. Common with regional blocking or bot-protection scripts. | Verify firewall rules. Do not submit protected internal paths. |
| 500 Internal Server Error | Fatal application or database failure during page generation. | Audit server resource limits and application code. Pause sitemap updates. |
| 503 Service Temporarily Unavailable | Server overloaded or undergoing maintenance. | Bots will retry. Ensure 503 drops cleanly once maintenance concludes. |
Validating the x-robots-tag against database logic
You must perform an exact comparison between your dynamic generation rules and the live header output. Extract a sample set of flagged paths. Run them through the URL Inspection tool. Inspect the indexing allowed data parameters.
A page might lack an HTML meta robots tag entirely but still trigger an exclusion. System administrators often configure the x-robots-tag globally via server daemon rules. The CMS generation script remains oblivious to these server-level overrides. It outputs the URL. The server immediately attaches a noindex directive in the HTTP header during the transmission.
Execute this exact verification sequence for flagged endpoints.
- Extract the raw HTTP response headers using a command-line tool or inspection protocol.
- Locate any x-robots-tag variables injected by global server policies.
- Parse the source HTML for conflicting meta robots parameters.
- Compare the resulting indexability status against the database logic generating the XML output.
Exclude conflicting URLs at the database query level. Do not rely on bots to sort out contradictory directives. Clean the XML feed at the source.
SEO structure and reciprocal link analyzer
Detect orphan pages, deep click depths, and toxic reciprocal links built by careless agencies.
Auditing redirect chains and 3xx status codes within sitemaps
A sitemap dictates canonical end-state destinations. It is not a historical log of routing pathways. Submitting a URL within a loc tag that triggers a 301 Moved Permanently or 302 Moved Temporarily response introduces immediate architectural friction.
The web server processes the bot request, initiates a redirect protocol, and forces the crawler to execute a secondary HTTP request. This burns operational resources on pathways instead of content.
Identifying routing collisions
Dynamic CMS environments frequently output legacy database strings into the XML feed while the server layer handles dynamic URL rewriting. This disconnect generates hidden routing failures.
- Target URL returns 301 Moved Permanently instead of 200 OK.
- Target URL returns 302 Moved Temporarily signaling an unstable canonical state.
- Multiple sequential 3xx hops trigger crawler abort protocols.
You must isolate Link Equity Loss across these hops. Search engines depreciate value across complex redirect paths. A strict 200 OK standard preserves crawl efficiency.
Redirect chains and loops
A standard redirect from a legacy endpoint to a current endpoint is expected behavior during site migrations. Submitting the legacy endpoint via the sitemap is a critical error.
Redirect Chains multiply this error. URL A routes to URL B, which routes to URL C. The crawler evaluates the entire path. Link Equity Loss compounds with each step in the chain.
Redirect loops occur when routing rules conflict. The server sends the bot from URL A to URL B, then immediately back to URL A. The system gets trapped in an infinite request cycle until the protocol times out. Purge these immediately from any database generating your loc parameters.
Canonicalization directives versus HTTP headers
Isolate the intersection between server response headers and HTML canonicalization directives. A sitemap submission must match both.
Engineers often point a sitemap loc parameter to URL A. URL A triggers a 301 redirect to URL B. URL B renders with an HTML canonical tag pointing back to URL A. You just engineered a canonicalization collision.
The HTTP header dictates movement. The HTML dictates indexing priority. When they conflict, indexation stalls.
Cross referencing URL hierarchy
Manual validation scales poorly across enterprise platforms. You need dedicated crawler diagnostics to enforce target URLs returning strictly 200 OK.
Deploy Screaming Frog, Sitebulb, or Lumar. Configure the software to ingest the live XML feed directly. Set the crawler to execute requests against every declared loc parameter. Do not allow the crawler to parse internal HTML links. Force an exact validation of the XML mapped targets against live server responses.
| Diagnostic Tool | Execution Parameter | Validation Target |
|---|---|---|
| Screaming Frog | List Mode XML Ingestion | Filter strictly for non-200 OK status codes within sitemap nodes. |
| Sitebulb | Indexability Audit | Highlight canonicalization collisions mapped against 3xx HTTP responses. |
| Lumar | Deep Crawl Configuration | Map URL Hierarchy depth against persistent Redirect Chains. |
Cross-reference the resulting URL Hierarchy. Any entity residing inside a sitemap loc tag must return a 200 OK. Extract the routing data. Update the database script generating the XML document. Map the final destination endpoints directly into the generator query.
Leveraging lastmod, ETag, and caching response headers
The lastmod value inside an XML node operates strictly as a scheduling parameter. It is not a ranking signal. Search engine crawlers extract this timestamp and validate it against live server response headers. System trust degrades rapidly if the declared sitemap date contradicts the actual HTTP payload.
Synchronizing XML scheduling with HTTP conditional requests
A crawler initiates an If-Modified-Since HTTP request based on its previous visit timestamp or the extracted lastmod data. The origin server evaluates this incoming request against its internal file modification records. The server must bypass standard HTML rendering and return a 304 Not Modified status code if the content remains unchanged.
You need exact alignment between the ETag, the Last-Modified header, and the XML loc node. Desynchronization occurs when a CMS updates the sitemap timestamp upon a global template change but the individual page cache retains the old HTTP headers. The crawler detects the mismatch. It downloads the redundant payload. It wastes processing power.
Implement the following server configurations to trigger accurate conditional responses.
- Format the Last-Modified HTTP header strictly using the standard GMT HTTP-date structure.
- Generate dynamic ETags based on database content updates rather than static file timestamps or inode numbers.
- Sync the XML generator script to pull the exact database modification timestamp used for the ETag generation.
- Strip the Vary response header from static HTML assets to prevent cache fragmentation.
Crawl budget conservation via 304 not modified
A 304 Not Modified is the most efficient response for static assets. It halts payload transfer instantly. The crawler registers the unchanged state, updates its internal scheduling system, and immediately moves to the next URL in the queue. This conserves Googlebot Crawl Budget.
Forcing a 304 Not Modified response prevents the transfer of redundant data. The network connection terminates early. Server CPU cycles drop. You force the search engine to reallocate its limited daily request quota toward newly published or recently updated pages rather than parsing identical text.
Edge caching and Cloudflare page rules
Origin servers waste compute cycles processing unmodified requests. Shift the validation load to the edge. Edge Caching reduces origin server strain by intercepting the crawler request at the node closest to the bot IP block. Cloudflare processes the If-Modified-Since request before it hits the application layer.
Navigate to Caching then Configuration then Page Rules in the Cloudflare interface. Configure the ruleset to cache the HTML payload and manage the ETag validation autonomously.
Deploy the following Cloudflare Page Rules parameters to force edge validation.
| Rule Parameter | Configuration Value | Execution Logic |
|---|---|---|
| Cache Level | Cache Everything | Forces the edge to store dynamic HTML responses alongside static assets. |
| Edge Cache TTL | Respect Existing Headers | Reads the origin ETag and Last-Modified data to dictate edge expiration. |
| Origin Cache Control | On | Prevents Cloudflare from stripping origin-set conditional headers. |
Search engine crawling efficiency metrics
Tracking infrastructure performance requires specific data points. Search Engine Crawling efficiency metrics regarding indexation frequency validate the caching architecture. Measure the time delta between the XML lastmod injection and the subsequent SERP update.
Monitor the following indexation frequency metrics to confirm infrastructure optimization.
- Time-to-Index Velocity measures the exact latency between database publication and successful rendering in the search index.
- Payload Transfer Reduction calculates the ratio of bytes downloaded versus total URLs crawled over a 24-hour period.
- Conditional Response Ratio tracks the percentage of 304 status codes against the total volume of daily bot requests.
A high volume of 304 responses on static URLs proves the architecture works. The system limits redundant data transfer. The crawler digests fresh content faster. Overall indexation frequency increases.
Bulk Google and Yandex index checker
Verify agency reports and track live SERP status in Google and Yandex to protect your SEO ROI.
Diagnostic tooling and server log analysis for crawl budget
Server logs provide the unvarnished reality of bot behavior. Third-party site crawlers simulate how a site might be indexed. Server Log Analysis records exactly how search engines actually traverse the architecture. Extracting and parsing this data exposes hidden system failures, architectural flaws, and bottlenecks draining server resources.
Relying solely on frontend diagnostic platforms leaves deep structural blind spots. You must process raw access logs through a dedicated log-file analyzer to isolate Googlebot and other Search engine bots HTTP request data.
Executing the log file extraction workflow
Raw access logs generate massive, unstructured datasets. Processing this data requires strict filtering protocols to eliminate human traffic, malicious scrapers, and headless browsers. A standardized workflow isolates genuine search engine activity.
- Consolidate raw access logs from all load balancers and web servers into a unified log-file analyzer environment.
- Filter the dataset by user-agent strings matching Googlebot, Bingbot, and specific target crawlers.
- Execute reverse DNS lookups on the extracted IP addresses to verify authenticity and discard spoofed bot traffic.
- Isolate the HTTP request data by URL path, response code, byte size, and timestamp.
- Cross-reference the queried paths against the active XML sitemap outputs to identify missing assets.
This verified dataset forms the foundation for evaluating server-side crawling efficiency. It reveals the exact percentage of bot requests hitting non-indexable, redirected, or deprecated URLs.
Defining crawl metrics and identifying anomalies
Quantifying server interaction requires specific performance indicators. Map the verified log data against these core architectural metrics.
Crawl Budget dictates the maximum number of requests search engine bots will execute on the server during a specific timeframe. Exceeding this capacity limit leaves deep-architecture URLs undiscovered. Budget depletion frequently correlates with drops in organic visibility for newly published content.
Crawl Depth measures the distance in structural clicks from the root domain to the target URL. Log analysis routinely reveals bots abandoning paths that exceed a Crawl Depth of four levels. Keep high-priority commercial URLs within three network hops from the root application.
Crawl Traps represent severe architectural flaws. These infinite structural loops generate millions of unique, low-value URLs. Common triggers include unoptimized faceted navigation, endless calendar pagination, or dynamic parameter sorting. Left unchecked, a single Crawl Trap will consume the entire daily Crawl Budget, starving the core pages of indexation.
Integrating Third-Party technical SEO audit platforms
Standalone log data indicates what bots are doing. Overlaying this data with cloud-based crawling platforms explains why. Integrate Semrush and Ahrefs site crawl exports directly with your parsed log data to form a complete diagnostic picture.
Ahrefs flags orphaned pages and structural bottlenecks. Matching an Ahrefs URL inventory against log-file analyzer outputs identifies which known pages receive zero bot hits. Semrush provides granular technical error reporting. Syncing Semrush data with server logs pinpoints exactly which broken internal links waste the highest volume of bot requests.
A comprehensive Technical SEO Audit merges these datasets. You locate the exact URLs triggering backend system failures and correlate them with frontend structural deficiencies.
Mapping crawl baseline against index controls
Optimizing server resources demands a strict separation between crawling directives and indexation directives. Mixing these mechanisms creates conflicting signals and degrades SEO performance.
Establish a crawl baseline. This metric represents the average daily volume of legitimate bot requests hitting 200 OK HTML URLs over a rolling 30-day period. Any sudden deviation from this baseline indicates a structural anomaly or configuration error.
Govern this baseline using specific control mechanisms.
| Control Type | Mechanism | Impact on Bot Behavior |
|---|---|---|
| Crawl Controls | robots.txt Disallow | Blocks network requests entirely. Conserves budget. Search engines drop the connection before downloading the payload. |
| Index Controls | noindex directives | Requires the bot to download and render the HTML. Consumes budget. Removes the URL from the SERP. |
| Parameter Controls | URL Inspection API | Forces localized recrawl overrides. Rapidly updates indexation status for isolated high-value URLs. |
Do not use index controls to manage crawl capacity issues. Applying a noindex directive to a faceted navigation parameter does not save server resources. Bots still execute the HTTP request to read the tag. Managing the crawl baseline requires implementing strict crawl controls at the root level to sever the network request before it reaches the application layer.
Enterprise server configuration: .Htaccess and Web.Config synchronization
Routing logic dictates server efficiency. Configuration files sit between the network layer and the CMS. They execute directives before any application scripts load. Misaligned server configurations overwrite database-level SEO intents. Synchronizing Apache .htaccess files and Microsoft IIS Web.Config files ensures crawlers receive the exact technical directives defined in the system architecture.
Automated HTTP header insertion for x-robots-tag
HTML tags require full page rendering. Bots waste processing power parsing the document object model to find indexing directives. Server-side HTTP headers bypass this rendering dependency. Injecting the x-robots-tag directly through the root configuration executes indexing exclusions instantly.
This mechanism is mandatory for non-HTML assets. Application routing cannot natively inject meta tags into PDF documents, raw text files, or JSON feeds. You must force the server to append the header to the outbound response.
- Apache environments utilize the Header directive wrapped in a FilesMatch condition to target specific file extensions.
- IIS environments modify the httpProtocol customHeaders node within the system.webServer configuration block.
- Nginx configurations leverage the add_header directive mapped to specific location blocks.
<FilesMatch "\.(pdf|doc|txt|json)$">
Header set X-Robots-Tag "noindex, noarchive"
</FilesMatch>
The code block above binds the noindex directive to specific file extensions. The crawler processes the HTTP header and drops the payload immediately. This precise exclusion pattern secures the SERP from raw system files.
Synchronizing static XML maps with dynamic routing
Enterprise platforms rarely serve static files for sitemap delivery. Managing millions of URL nodes requires dynamic database querying. Search engines expect a standard sitemap.xml path. URL rewrite modules bridge this architectural gap. The server intercepts the request for the static file extension and silently maps it to the dynamic application route.
The client receives the XML payload. The internal routing remains hidden. This eliminates structural desynchronization between the database records and the live indexable map.
| Environment | Rewrite Module Parameter | Execution Logic |
|---|---|---|
| Apache | RewriteRule ^sitemap\.xml$ /routes/sitemap-generator.php [L] | Matches the exact static request. Forwards internal processing to the PHP generator. The [L] flag halts further rule processing. |
| IIS | match url="^sitemap\.xml$" / action type="Rewrite" | Intercepts the requested path via URL Rewrite 2.0. Maps the request dynamically while preserving the original static URL string. |
HTTPS configuration and canonical redirection patterns
Strict canonicalization occurs at the server root. Relying on CMS plugins to handle protocol resolutions introduces network latency. Server-level execution enforces a single source of truth. Every request failing to match the target protocol triggers an immediate server response indicating permanent relocation.
Implement the following redirection patterns at the configuration level to consolidate link equity.
- Force secure connections by evaluating the HTTPS server variable and routing unencrypted port 80 traffic to port 443.
- Standardize domain prefixes by capturing HTTP_HOST parameters and routing all bare domain traffic to the www subdomain variant.
- Strip trailing slashes from directory paths using rewrite conditions to prevent duplicated URL variants from generating parallel index entries.
- Force lowercase uniform resource identifiers to prevent case-sensitive server environments from splitting page authority.
Consolidating these rules is critical. Processing sequential redirects creates system bottlenecks. A unified server block evaluates the protocol, subdomain, and path string simultaneously. It executes a single jump to the canonical destination. This unified execution safeguards the crawl capacity.
Server-Level indexing exclusions
Granular control over bot access extends beyond standard text-based blocking directives. Server configurations lock down specific system directories. You isolate staging environments, API endpoints, and internal search parameters directly at the application gateway.
Appending indexing controls based on request URI patterns forces search engines to process the directive before the database receives the query. You map specific regular expressions matching staging subdomains or sorting parameters to a global x-robots-tag noindex header. The system conserves processing resources while completely removing the URL footprint from the index.