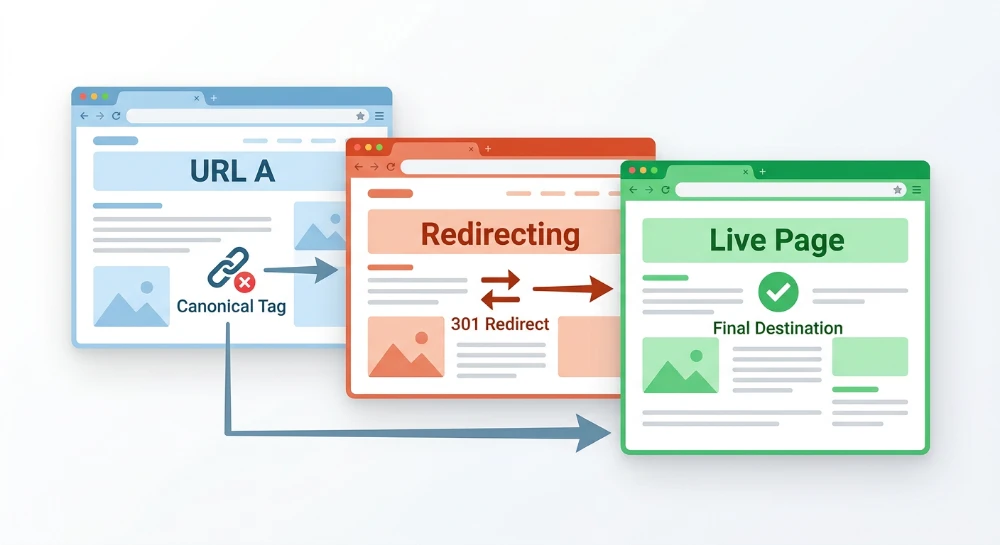
A rel="canonical" link element is designed to point directly to the final, definitive version of a web page. When this tag specifies a target URL that returns a 3XX redirect instead of a 200 OK status code, it creates conflicting indexing instructions. Rather than identifying a clear primary page, the tag sends search engine crawlers to a forwarding address.
This setup introduces an unnecessary step in the crawling process. When a crawler encounters a redirected canonical target, it cannot immediately apply the canonicalization signal. Instead, it must initiate a subsequent request, follow the redirect hop, and evaluate the final destination independently to determine the actual definitive URL.
While search engines are generally capable of following simple redirects, relying on them to resolve redirected canonical tags adds operational friction. Updating these tags to point strictly to the absolute URL of the final, live destination ensures that indexing signals remain clear and direct.
How crawlers process a redirected canonical target
Under standard conditions, a canonical tag provides a single, direct instruction. A search engine crawler reads the HTML of a page, extracts the URL from the rel="canonical" link element, and requests that target. When the configuration is correct, the server responds immediately with a 200 OK status code, presenting the content of the definitive page for evaluation.
When a canonical tag points to a redirected URL, this single instruction turns into a multi-hop sequence. The crawler parses the target URL and issues an initial HTTP request. Instead of receiving the expected page content, the server returns a 3XX status code, such as a 301 Moved Permanently or a 302 Found. This response includes a Location header indicating where the resource has moved.
Upon receiving the 3XX status code, the crawler cannot immediately validate the canonicalization signal. It must extract the forwarding address from the Location header and initiate a subsequent request. Depending on the search engine's scheduling architecture, this new URL is typically added to a queue rather than being fetched instantaneously, separating the parsing of the tag from the evaluation of its target.
The search engine must then execute the secondary request to reach the final destination. If that request results in a 200 OK status code, the crawler can finally access the content and process the canonical relationship. This sequence transforms a declarative pointer into a procedural chain, requiring the crawler to resolve intermediate server responses before identifying the actual definitive page.
Run a deep technical crawl to identify 4xx errors, missing meta tags, and indexation blockers.
Impact on signal consolidation and crawling
A canonical link element functions best as a clear, definitive statement of preference. When this element points to a URL that returns a 3XX redirect, it introduces ambiguity into the indexing signal. Instead of directly identifying the primary page, the tag points to a transitional state, forcing the search engine to determine whether the canonical intent applies to the initial URL or its ultimate destination. This ambiguity creates operational friction, as the search engine must evaluate the redirect behavior before it can trust and process the canonical relationship.
This friction directly delays signal consolidation. Canonical tags are designed to aggregate indexing signals, such as link equity, from duplicate or parameterized pages into a single primary version. When the target URL redirects, the consolidation process is paused until the crawler successfully fetches the final destination. Because crawler scheduling is typically asynchronous, the time between parsing the initial canonical tag and resolving the final redirect target can span days or weeks. During this interval, link equity and indexing signals remain fragmented across multiple URLs rather than being efficiently assigned to the definitive page.
Modern search engine crawlers, including Googlebot, are equipped to follow simple redirect chains to discover a final URL. However, relying on this capability as a standard implementation across a website introduces unnecessary processing overhead. Each redirect hop requires a separate HTTP request, additional server response time, and further queueing. At scale, resolving thousands of redirected canonical tags consumes crawl capacity that would otherwise be allocated to discovering new content or refreshing existing pages.
Beyond processing delays, chaining a canonical instruction through a redirect increases the risk of complete signal failure. Every additional hop introduces a potential breaking point in the crawl path. If the redirect chain leads to a dead end, such as a 404 Not Found or a 5XX server error, the search engine abandons the evaluation. Likewise, if server configuration errors cause the redirect to loop back to the original URL or create a circular chain, the crawler will detect the loop and halt the request sequence. When a canonicalization attempt fails due to these architectural dead ends, the search engine ignores the canonical instruction entirely and selects its own definitive version of the page algorithmically.
Common scenarios leading to redirected canonicals
Canonical tags usually point to redirected URLs due to a configuration mismatch between server-level routing rules and application-level HTML generation. When a website undergoes structural changes, server administrators or SEOs often implement 3XX redirects at the server configuration level, CDN, or edge router to enforce the new URL patterns. However, if the content management system (CMS) or static site generator is not updated to reflect these new absolute URL structures, the software continues to populate the canonical link element with the legacy URL.
This architectural disconnect means the server correctly redirects users and crawlers to the new destination, but the page's HTML explicitly requests canonicalization to the old, redirected address. Several common site updates frequently trigger this condition.
Protocol migrations
Transitioning a website from HTTP to HTTPS requires enforcing a global redirect rule so that all requests over port 80 (HTTP) redirect to port 443 (HTTPS). If the site's base URL setting or environmental variables within the CMS are not updated to use the HTTPS protocol, the application will continue to generate self-referencing canonical tags using HTTP.
In this scenario, a crawler evaluating the secure page reads a canonical tag pointing to the insecure HTTP version. The crawler requests the HTTP URL, encounters the global server-side redirect, and is sent back to the HTTPS version, creating a circular logic loop.
Trailing slash enforcement
Websites often standardize their URL paths to either strictly include or exclude a trailing slash. To prevent duplication, a site might implement a rule redirecting all non-slash URLs to their trailing-slash counterparts. If the CMS routing logic handles trailing slashes differently than the server rules, or if canonical tags are generated using a method that strips the slash, a persistent mismatch occurs.
For example, if the server enforces a trailing slash but the template logic generates canonicals without it, every canonical tag across the site will result in a 301 redirect back to the page the crawler is already evaluating.
Domain and subdomain consolidations
Consolidating subdomains, such as redirecting a www subdomain to a bare domain, relies on DNS and server-level redirection. When these redirects are deployed, the existing page content must be updated. If canonical URLs are hardcoded in legacy templates, stored as static strings in a database, or generated by third-party plugins using cached settings, they often retain the old subdomain.
Similarly, during a full domain migration, wildcard redirects seamlessly map the old domain's paths to the new domain. If the database on the new domain is a direct clone of the old site and the static canonical fields are not modified via a database search-and-replace operation, the canonical tags on the new domain will point back to the old domain, instantly triggering the migration redirect chain.
Taxonomy and path restructuring
Updating category structures, modifying product URL patterns, or removing parent directories from a URL path requires 1-to-1 redirects mapping the old paths to the new paths. The disconnect typically occurs when authors have manually defined custom canonical URLs in a CMS field for specific pages prior to the restructuring. While the dynamic self-referencing canonicals might update automatically with the new taxonomy, the manually entered, static canonical tags remain unchanged. They continue to output the legacy path, forcing crawlers to process the redirect mapped to the old taxonomy structure.
Detect stealthy removals, nofollow tag injections, and altered anchors instantly.
Auditing for canonical to 3XX issues
Identifying canonical tags that point to redirected URLs requires evaluating the active HTTP status code of the target URLs at scale. While the Google Search Console Page Indexing report highlights generalized symptoms of canonicalization and redirect behavior, it does not explicitly map a source page's canonical tag to the live response code of its target. Statuses like "Page with redirect" or "Alternative page with proper canonical tag" indicate how search engines process individual URLs, but they do not isolate the specific structural flaw of a canonical tag pointing to a 3XX destination.
To detect these mismatches comprehensively, dedicated site audit software is necessary. A crawler can parse the HTML of every page, extract the defined canonical URL, request that destination, and log the resulting HTTP status code across the entire architecture.
Configuring site audit software
When setting up a crawl to diagnose canonical configurations, the audit tool must be instructed to treat canonical link elements as discoverable, requestable URLs. Standard configuration steps include:
- Enabling canonical link extraction in the spider's parsing or spider configuration settings.
- Configuring the crawler to spider outside the start folder or verify external links, which is necessary if the canonical tag targets a different hostname, subdomain, or protocol (such as an HTTP to HTTPS mismatch).
- Checking the tool's redirect behavior settings to ensure it records the exact 3XX status code of the canonical target, rather than automatically resolving and reporting only the final 200 OK destination.
Evaluating the crawl data
Once the crawl is complete, export the canonical URL report. The dataset needed for this analysis requires three primary data points: the source URL where the tag is located, the extracted canonical URL, and the HTTP status code returned by the canonical URL.
Filter the dataset to isolate rows where the canonical URL returns a 301, 302, 307, or 308 status code. Grouping the filtered results by the destination URL path or the source URL directory can help determine if the issue stems from a site-wide configuration error or a localized template flaw.
For example, if every canonical target returns a 301 redirect enforcing a trailing slash, the root cause is likely a global CMS routing setting that generates URLs without slashes in the head element. If the 3XX targets are isolated to a specific product category, the pattern usually points to a recent taxonomy restructuring where manual, static canonical fields in the database were not updated to match the new URL paths.
Remediation and live verification
Correcting a redirected canonical target requires updating the link element to bypass the redirect chain entirely. The objective is to configure the canonical tag so that it points directly to the final, authoritative version of the page resolving with a 200 OK HTTP status code.
Locate the source of the canonical tag generation, whether it is a static database field, a global CMS routing rule, or a localized page template. Modify the URL string in the canonical link element so that it matches the exact absolute URL of the final destination. This string must include the correct protocol, subdomain, and specific path structure, matching the exact format that returns a 200 status code.
Running a live test in Google search console
After deploying the updated canonical tags, validate the fix using the URL Inspection tool in Google Search Console. Relying solely on site audits or source code checks leaves room for server-side caching issues. A live test confirms exactly how a search crawler processes the updated instruction.
- Enter the source URL containing the updated canonical tag into the URL Inspection tool search bar.
- Select the Test Live URL option. This action forces the crawler to fetch the current version of the page directly from the server, bypassing older indexed data.
- Once the live test completes, expand the Indexing section to view the detailed page evaluation.
- Examine the User-declared canonical field. Verify that this field extracts and displays the newly updated absolute URL rather than the previous redirected path.
Confirming the destination status
While the live test on the source page confirms that the canonical tag is outputting the correct string, verifying that the new target URL behaves as expected is the final requirement. To confirm the destination is reachable without further redirects, submit the updated canonical target URL into the URL Inspection tool as an independent query.
Execute a live test on this destination URL. Check the Page fetch field to ensure it reports a successful connection. If the live test shows that the URL loads directly without indicating a redirect, the remediation is complete. Providing crawlers with a definitive, non-redirecting canonical target removes ambiguity and allows the canonicalization signal to be processed without requiring subsequent network requests.